


CUDA and GPU programming
Kernels, memory, profiling and the tooling that makes NVIDIA GPUs fast.
80 links, newest first.
- CUDA and GPU programmingPost on X
NVIDIA CUDA C++ Guide: Execution, Memory, and Correctness
NVIDIA’s CUDA Programming Guide introduction covers kernel launches, thread organization, memory management, synchronization, runtime initialization, error handling, and validating GPU results against a CPU implementation.
A concise overview of CUDA execution and memory concepts helps engineers build and debug GPU programs.
- CUDA and GPU programmingRepository
auto-gpu-kernel 1.0 generates GPU kernels and harnesses
The author announces version 1.0 of auto-gpu-kernel, described as an autonomous kernel-generation meta-harness that evolves both the kernel and harness layer. Its GitHub page says it won the agent-only MLSys 2026 FlashInfer kernel generation contest's DSA track.
Engineers can inspect a project that generates GPU kernels and harnesses and competed in a kernel-generation contest.
- CUDA and GPU programmingPost on X
SlimServe fork enables PCIe P2P on GeForce
The author says they forked NVIDIA’s graphics drivers to enable PCIe peer-to-peer transfers on GeForce while optimizing SlimServe. They speculate it may also work on RTX Pro 6000, which they have not tested.
PCIe peer-to-peer support can matter when optimizing GPU serving, and the post points to a driver-level change.
FIBER Decouples Register Ownership from GPU Execution
The paper presents FIBER, a GPU architecture that decouples register ownership from parallel execution instances. It includes ISA extensions, lightweight microarchitectural enhancements, and a CUDA-compatible programming model.
It describes architectural and programming-model changes relevant to GPU and CUDA design.
CuTe Layout Representation and Algebra
A paper on the representation and algebra of CuTe layouts.
Relevant to engineers working with CuTe layout abstractions in GPU programming.
- CUDA and GPU programmingArticle
Tracing an LDG Instruction Through the RTX 4090
The post follows an LDG.E SASS instruction through the hardware units and memory hierarchy of an RTX 4090, including reverse-engineering undocumented details.
It offers a hardware-level view of how GPU memory reads move through an RTX 4090.
- CUDA and GPU programmingArticle
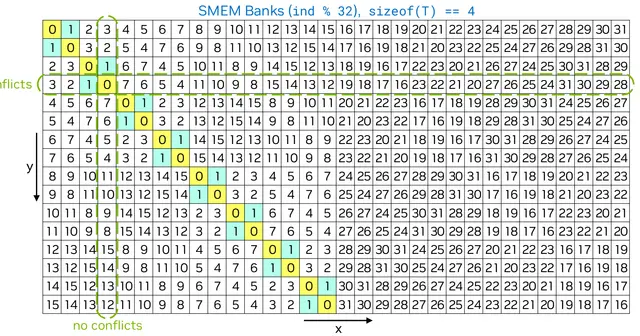
Using Swizzling to Handle CUDA Shared Memory Bank Conflicts
A technical article about using swizzling to deal with bank conflicts in CUDA shared memory.
It covers a memory-access issue that can affect CUDA kernel performance.
- CUDA and GPU programmingArticle
LeetGPU CUDA Challenges and a Suggested Practice Path
The post recommends LeetGPU challenges for CUDA practice and suggests progressing from naive SIMD kernels to shared memory, tiling, Blackwell instructions such as WMMA and TMA, and CuteDSL.
The suggested sequence highlights CUDA concepts and tools engineers can practice in GPU programming challenges.
- CUDA and GPU programmingArticle
How Blackwell Moves Matmul Accumulation into Tensor Memory
The post describes Blackwell tensor memory as a separate 256 KB-per-SM space for Tensor Core results, allowing matmul issuance to drop from 128 threads to one, according to the author.
It highlights how Tensor Memory changes accumulator storage and the thread model for GPU matmul.
GPU-Tile-Sim: Tile-Centric GPU Simulation for LLM Co-Design
The paper proposes GPU-Tile-Sim (GTSim), a tile-centric GPU simulation framework for LLM hardware-software co-design.
Engineers working on LLM hardware-software co-design may find a GPU simulation framework relevant.
Vulkan documentation introduces compute shaders and GPU architecture
The Vulkan tutorial introduces compute shaders, GPU architecture, and memory models. The post notes that much of the discussion also applies to DirectX 12.
GPU architecture and memory-model concepts are useful context for engineers working across GPU programming APIs.
- CUDA and GPU programmingPost on X
What Happens When You Run a CUDA Kernel
A blog post about the CPU–GPU communication involved in launching a CUDA kernel.
Useful for understanding the work involved in launching CUDA kernels.
- CUDA and GPU programmingPost on X
A Two-Core GPU Implemented on a $30 FPGA
The project includes a 16-bit ISA and assembler, a J++ language and compiler, and branch divergence and warp scheduling. It runs AI model inference at 81 MHz on a $30 FPGA.
Its ISA, compiler, and scheduling design offer a concrete look at GPU architecture implemented in hardware.
- CUDA and GPU programmingArticle
Tracing a CUDA Kernel from Compilation to Warp Execution
The article traces a vector-add kernel from nvcc through to the warps that execute it.
It connects CUDA compilation with how a kernel is executed on the GPU.
CUDA Stream Covers New Chapters in Programming Massively Parallel Processors
A CUDA live stream features Izzat El Hajj, author of Programming Massively Parallel Processors, discussing the book’s new chapters and giving an overview.
Useful for engineers who want an overview of new material in a CUDA programming book.
NVIDIA CUDA C++ Programming Guide Updated in June 2026
The post links to NVIDIA’s CUDA C++ Programming Guide PDF and says it was updated in June 2026.
It provides an updated reference for engineers working with CUDA C++.
- CUDA and GPU programmingArticle
Cornell Workshop on Understanding GPU Architecture
Cornell Virtual Workshop offers material on understanding GPU architecture.
A structured introduction to GPU architecture can help engineers reason about GPU performance.
Vasily Volkov’s GPU optimization papers and talks
The post collects work by Vasily Volkov on GPU performance, including loop unrolling, latency hiding, dense linear algebra, and GPU memory. One linked PDF is titled “Unrolling Parallel Loops.”
The collection points engineers to research on GPU optimization techniques and performance modeling.
- CUDA and GPU programmingArticle
GPU Execution Model in Modern GPU Programming
A chapter from Modern GPU Programming for MLSys titled “GPU Execution Model.”
Useful as a focused learning resource on how GPU execution works.
- CUDA and GPU programmingPost on X
Understanding GPU Latency Hiding
A chapter by Vasily Volkov of UC Berkeley on latency hiding on GPUs, covering GPU architecture and performance concepts.
It offers engineers a focused resource on how GPUs hide latency and on related performance concepts.
Build with AgentLog
Send your own newsletter
CommsHarbor keeps contacts, consent and one-click unsubscribe together.
Free workspace
Open CommsHarbor