CUDA and GPU programming
- CUDA and GPU programmingArticle
Beginner guide to writing a CUDA array addition kernel
A beginner-focused introduction to writing a simple array addition CUDA kernel, hosted on Tensara, a GPU programming challenge platform.
Useful as an entry point for engineers learning to write CUDA kernels.
- CUDA and GPU programmingArticle
A suggested learning path for CUDA programming
The author recommends building C/C++ and linear algebra foundations before studying CUDA, and suggests *Programming Massively Parallel Processors*, *Professional CUDA C Programming*, and a CUDA course.
It gives beginners a concrete sequence of foundations and resources for getting started with GPU programming.
- CUDA and GPU programmingArticle
Exploiting Two Bugs in NVIDIA’s Linux GPU Kernel Modules
Quarkslab details two bugs in NVIDIA’s Linux Open GPU Kernel Modules, triggered by a local unprivileged process. A proof of concept demonstrates kernel read and write primitives.
GPU driver developers can review the bugs and their security implications.
Video lectures for Programming Massively Parallel Processors
A YouTube playlist of video lectures accompanying the book “Programming Massively Parallel Processors.” The post highlights lecture 04 on GPU architecture.
The lectures offer engineers material on GPU programming and architecture.
A Step-by-Step Introduction to CUDA C++
NVIDIA’s blog post introduces CUDA programming with a simple, step-by-step parallel programming example in CUDA C++.
A concise starting point for engineers learning CUDA programming.
- CUDA and GPU programmingArticle
A compute-first mindset for learning GPU programming
The article makes a case for learning GPU programming with a compute-first mindset.
It offers engineers a perspective on how to approach learning GPU programming.
- CUDA and GPU programmingProject
Penny: a hand-rolled GPU communications library
Penny is a hand-rolled GPU communications library. The linked repository describes it as an open-source project.
Engineers can inspect the library’s implementation and contribute to its development.
- CUDA and GPU programmingArticle
GPU MODE Recaps the AF3 Trimul Kernel Competition
A GPU MODE blog post reviews why the AF3 trimul kernel was difficult to optimize, how the competition was intended to work, and what participants implemented.
The recap may offer insight into kernel optimization challenges and approaches from competition participants.
- CUDA and GPU programmingArticle
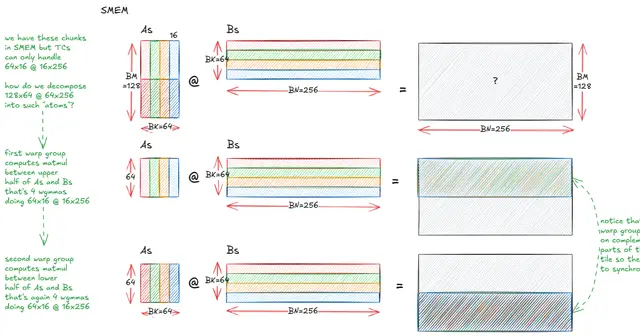
Inside NVIDIA GPUs: Anatomy of High-Performance Matmul Kernels
An article covering GPU architecture and PTX/SASS, then examining warp-tiling and asynchronous tensor core pipelines for matrix multiplication kernels.
Useful for understanding how GPU architecture and kernel design relate to high-performance matrix multiplication.
- CUDA and GPU programmingArticle
Blog post on kernels, graphics, and profiling
The author shares a blog post covering kernels, graphics, profiling, and related topics.
It may offer engineers a useful overview of several GPU programming areas.
- 1 year ago @gordic_aleksa
A Guide to High-Performance CUDA Matmul Kernels
The post describes a detailed guide to GPU memory hierarchy, the CUDA programming model, and using PTX/SASS to inspect and steer compiler output for matmul kernels.
It connects GPU architecture and compiler behavior to practical CUDA matmul kernel development.
- CUDA and GPU programmingArticle
Reverse-Engineering FlashAttention-4 for a 20% Performance Gain
Modal describes reverse-engineering Flash Attention 4, citing asynchrony, fast approximate exponents, and more efficient softmax. The post attributes a 20% performance boost to a cubic polynomial, numerical-stability improvements, and increased asynchrony.
Useful for engineers exploring kernel optimization techniques for attention workloads.
- 1 year ago @murage_kibicho
CUDA Tutorial: 256-Bit Multiplication and Addition on a GPU
A CUDA GPU tutorial on implementing 256-bit multiplication and addition. The post says complete code is included in the comments.
It covers GPU implementations of multiword arithmetic, a useful topic for engineers working with low-level CUDA kernels.
- CUDA and GPU programmingArticle
Penny: A Worklog on Building a GPU Communications Library
A worklog describing the creation of Penny, a hand-rolled GPU communications library. The post is part one of the series.
Useful for engineers interested in how a GPU communications library is developed.
- 1 year ago @murage_kibicho
CUDA in C on Google Colab: A Free Practice Guide
The author says they made a video guide to practising CUDA GPU programming in C for free on Google Colab.
It points engineers to a guide for practising CUDA programming in a Colab environment.
- CUDA and GPU programmingArticle
Designing a SIMD Algorithm from Scratch
An article by Miguel describes designing a SIMD algorithm from scratch. The linked page focuses on SIMD Base64.
Useful as a concrete example of how to develop a SIMD algorithm.