Training and fine-tuning
- Training and fine-tuningArticle
How to Scale Your Model: a free guide to LLM scaling on TPUs and GPUs
An online book that explains how TPUs and GPUs work, how LLMs run on real hardware, and how to parallelize training and inference at large scale. The linked page presents it as a demystification of LLM scaling.
Covers the hardware and parallelism math behind training and serving LLMs, useful for estimating training cost and memory.
- 4 days ago @MaximeRivest
Author argues fine-tuning may beat prompt optimization for cost and speed
A post arguing that fine-tuning model weights may be faster, cheaper and easier than prompt optimization such as GEPA. It suggests fine-tuning a small model with Tinker, starting from a paper and a dataset.
Offers a concrete cost and effort case for fine-tuning over prompt optimization.
- 6 days ago @aaronklaw
Fine-tuning a legal LLM with LoRA and the overfitting lesson from a hold-out set
The author describes learning to fine-tune Llama for a legal task with LoRA using Unsloth notebooks. The model memorized the training data and performed worse than the base model on unseen examples, so they stress validating on a hold-out set.
A concrete reminder that a strong training loss doesn't show generalization, so evaluate fine-tunes on held-out data.
- 11 days ago @ChangJonathanC
Neuron Tuning: fine-tuning only context-firing neurons
The author introduces Neuron Tuning, which fine-tunes only a few neurons that fire in the target context. The author claims it changes the model 3-19x less on unrelated text than LoRA.
Offers a parameter-efficient alternative to LoRA that may limit unintended behavior changes outside the target context.
RoboJEPA: Scaling JEPA World Models for Robotics
Meta presents RoboJEPA, a JEPA-based robotic world model scaled from 22M to 8B parameters and trained on data from 12 robotic embodiments. The paper studies whether latent prediction error can forecast downstream planning performance.
Shows how world-model size and multi-embodiment data are studied as scaling variables for robot planning.
- Training and fine-tuningArticle
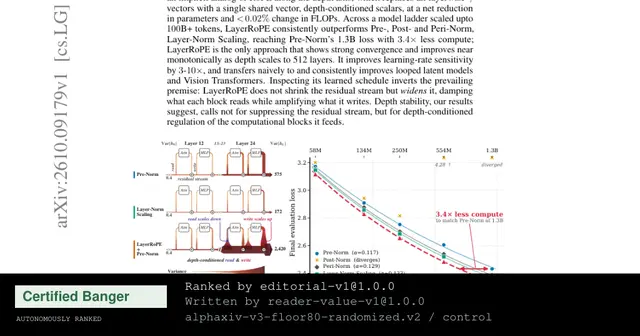
LayerRoPE: depth-encoded normalization weights for Transformers
Proposes LayerRoPE, which encodes depth into normalization weights to address hidden-state norm growth across layers. The author reports Pre-Norm's 1.3B model loss with 3.4x less compute and stable scaling to 512 layers.
Targets the depth-related norm growth that can destabilize training of very deep Transformers.
- 1 month ago @vai_viswanathan
RoboJEPA: scaling laws for robot world models, per a social post
A social post describes RoboJEPA, an 8B-parameter JEPA world model from FAIR at Meta and Mila, trained on 15,022 hours of robot video to plan toward goal images. The author reports scaling-law fits that predict the 4B and 8B results.
Shows a forecastable compute-to-capability relation for robot world models, a training-scaling question engineers can plan around.
Memory-Efficient Expert Routing for Distributed MoE Training
An arXiv paper proposing methods to reduce peak memory in distributed Mixture-of-Experts training, where the MoE dispatch pipeline dominates memory use. It targets the all-to-all dispatcher, which builds the full top-k-expanded buffer at once.
Relevant if you train large MoE models and hit memory limits in expert dispatch across devices.
- Training and fine-tuningArticle
H-JEPA: hierarchical JEPA world models for long-horizon visual planning
A paper advised by Yann LeCun proposes H-JEPA, stacking JEPA world models across multiple timescales so higher levels plan further ahead and lower levels produce actions. The author reports success on Visual AntMaze rising from 18% to 73% with a 3-level setup and less planner compute.
Shows how hierarchical latent world models can cut planning cost while handling both low-level motion and high-level goals.
- 1 month ago @cwolferesearch
Multi-teacher on-policy distillation for consolidating specialists
The post describes MOPD, which trains a student on its own generated rollouts and uses domain-specialized teachers to provide token-level supervision with a sampled reverse-KL objective.
It outlines a way to combine capabilities from independently trained specialist models in one student.
JEPA-Anything applies predictive learning across seven domains
JEPA-Anything introduces a domain-agnostic framework for world modeling based on orthogonal predictive factorization. The post says it explores predictive representation learning across seven domains, from biology to weather.
Engineers working on predictive models can examine a shared learning framework spanning different domains.
- Training and fine-tuningArticle
Scaling Pre-Training from 16 to 512 B200 GPUs
Aleph Alpha describes scaling a 30B-A3B MoE model from 16 to 512 B200 GPUs, reporting near-linear scaling and 35.3% MFU. The approach shrinks the search space at small scale before increasing the GPU count.
The report offers a practical scaling approach for testing training configurations before committing more GPUs.
- Training and fine-tuningArticle
Projection Sampling for Supervised Fine-Tuning
The paper introduces projection sampling to rewrite expert demonstrations as task-correct trajectories that are more likely under the target model, then uses them for standard supervised fine-tuning.
It explores how adapting training examples to a model’s distribution can improve SFT without changing the training method.
- Training and fine-tuningProject
KohakuFA targets backward-pass precision issues
The post claims that cuDNN, FA4, and FlexAttention have precision issues in backward passes, and presents KohakuFA as an alternative kernel. The linked GitHub page is the project repository.
Engineers evaluating training stability can inspect the kernel implementation and assess the precision claims.
- 1 month ago @HuggingPapers
Distillation Study Highlights the Direction of Token-Level KL
A systematic study reports that the direction of token-level KL matters more than rollout policy in on-policy versus off-policy distillation, challenging the assumption that on-policy rollouts are inherently better.
The finding may inform choices about rollout policies and KL objectives when designing distillation recipes.
- 1 month ago @aakaran31
Sampling-Based SFT for Post-Training
The post introduces a method that adds sampling to the post-training stack. Its authors say it can make SFT competitive with current post-training methods, with better generalization and less forgetting in some cases.
Engineers evaluating SFT and RL post-training can investigate the authors’ claimed generalization and forgetting trade-offs.
A 7B Model for Continuous Learning from Prediction Markets
The post describes a 7B model that continually updates its weights using prediction-market data and rolling backtests over 390 days. It claims the model outperformed several larger models in the same test environment.
It raises practical questions about updating model weights after deployment and evaluating continual learning against real-world feedback.
One-Shot OPD studies distillation from a single training example
The paper tests on-policy distillation using one query, reporting results across math, code, instruction following and agentic tool use. It argues that OPD can benefit more from algorithm improvements than from adding training data.
It suggests a way to reduce OPD data requirements while preserving much of the reported gain.
- Training and fine-tuningProject
IFM-AI Open-Sources LLM Training and Serving Tools
IFM-AI says it has open-sourced xLLM, lightweight infrastructure for LLM pre-training, plus xattn, an attention backend, and xBridges, a checkpoint conversion and serving toolkit.
Engineers can inspect tools for pre-training, attention, checkpoint conversion, and serving.
- 1 month ago @hugues_va
SIGReg Adds Pairwise Repulsion to JEPA Training
The post says SIGReg, used by LeJEPA and LeWM, approximates a sliced MMD whose expansion reveals pairwise repulsion between samples in a batch.
This offers a way to understand how a regularizer can shape representations during JEPA training.
 arxiv.org