Reinforcement learning
- Reinforcement learningArticle
Visual introduction to contraction operators in RL
An article in an intuitive RL series about contraction operators. The author describes a visual-first approach that aims to explain ideas with precision and few words.
It offers engineers a visual resource for learning a foundational RL concept.
Writeup on Policy Gradient Derivations and Variants
The author describes an article covering foundational reinforcement learning papers, deriving the policy gradient algorithm, and discussing its variants.
It may help engineers review the derivation behind policy gradient methods and how they have evolved.
- Reinforcement learningArticle
Sampling methods for optimizing objectives without RL
The post introduces a series on methods beyond reinforcement learning for optimizing evaluable objectives. Part I surveys sampling methods.
It gives engineers an overview of alternative approaches to objective optimization.
- Reinforcement learningArticle
Practical resources on GRPO and OPD
The post shares two resources for practical RL-style post-training beyond SFT. One covers techniques for making vanilla GRPO work at scale; the other is about OPD.
The GRPO guide may help engineers address practical challenges in scaling RL training.
- Reinforcement learningArticle
A Guide to Reinforcement Learning for LLMs
A guide covering RL fundamentals, policy gradients, REINFORCE, and LLM-specific formulations such as token-level MDPs, completion-level bandits, and outcome versus process rewards.
It connects core RL concepts to methods and setups used to train language models.
- Reinforcement learningProject
SQL-based RL replay buffer with weighted top-k sampling
Replayhouse uses a table as an RL replay buffer and implements Efraimidis-Spirakis weighted top-k sampling in SQL, allowing draws to be filtered with WHERE. The post reports sampling 8,192 rows from 50 million in about 1.1 seconds on a laptop.
A table-based buffer with SQL filtering may simplify replay-buffer sampling workflows.
WANDR: An RL Environment for Evaluating Agentic Search
Perplexity says it is open-sourcing an evaluation and RL environment for agentic search, synthesized from production traces with weak human supervision. The company says it uses these environments internally to train models.
Engineers can examine an environment built from production traces for evaluating and training agentic search systems.
- Reinforcement learningArticle
Policy Gradients Part 1: The REINFORCE Estimator
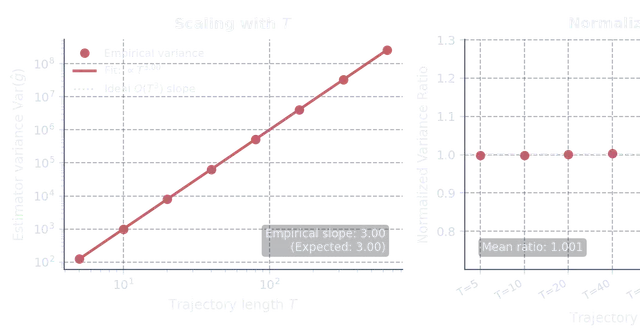
The first post in a series derives unbiased policy gradients with the REINFORCE estimator without differentiating through the environment, and analyzes variance scaling with trajectory length.
Useful for understanding a foundational policy-gradient method and its variance properties.
- 4 months ago @askalphaxiv
A proposed account of how RL builds on SFT
The post describes a paper’s hypothesis that SFT solutions contain tangled useful components, while reward-guided variation during RL helps separate them into reusable skills and routing rules for new problems.
The hypothesis offers a way to think about how RL may improve generalization beyond SFT examples.
LED uses intermediate-layer diversity to restore exploration
The paper reports that RL post-training reduces entropy in the final-layer distribution while intermediate layers retain higher entropy. Its training-free Latent Exploration Decoding method uses intermediate-layer distributions to improve sampling in reasoning models.
Engineers can evaluate a decoding approach aimed at improving pass@n without further training.
Single-Rollout Asynchronous Optimization for Agentic RL
The linked paper examines asynchronous RL for post-training language models, where models are updated as rollouts arrive. The post says GLM 5.2 PPO uses async RL improvements including clipping adjustments, and also links to VAPO.
Engineers working on agentic RL can review approaches to asynchronous training and stability.
Privileged Self-Distillation Can Degrade Long Reasoning Traces
The paper studies self-distillation with privileged information, such as a math solution, in thinking models. It reports degradation on long reasoning traces across five Qwen3 and OLMo models evaluated on AIME.
It highlights a potential trade-off when using privileged information to improve reasoning models.
- 4 months ago @askalphaxiv
RubricEM decomposes research-agent policies with rubrics
RubricEM trains research agents to create rubrics before working, then use them to plan, search, review, and answer. A judge scores trajectory stages, and judged attempts become lessons for future tasks.
Stagewise rubric rewards and reusable lessons offer an approach to training agents beyond single final-score feedback.
EfficientRollout speeds up RL rollout generation for LLMs
The paper presents system-aware self-speculative decoding for RL rollouts, using a quantized copy of the model, a roofline-based activation rule, and adaptive draft lengths. It reports up to 19.6% faster rollout generation and 12.7% faster training steps.
It describes ways to reduce rollout latency without changing the model being trained.
Two-Phase Distillation for Multi-Task Agentic LLMs
The paper studies consolidating separately trained, task-specific RL experts into a multi-task model through distillation, instead of training one model on mixed tasks. The post describes using off-policy distillation for initialization and on-policy distillation for refinement.
The approach offers an alternative to mixed-task training and examines a limitation of off-policy distillation in multi-task settings.
DreamSmooth smooths sparse rewards in model-based RL
The ICLR paper proposes temporally smoothing rewards across neighboring steps, using kernels such as Gaussian or EMA, to make reward modeling easier. The post says it evaluates the method on RoboDesk and Shadow Hand.
Reward smoothing may help engineers train model-based RL agents when rewards are sparse in time.
- 4 months ago @pr0me
AutoDecompiler Uses RL for Feedback-Driven Decompilation
The post describes AutoDecompiler as an RL-optimized model for multi-turn decompilation that uses feedback directly, unlike prior one-shot approaches.
It may interest engineers exploring reinforcement learning for iterative code generation and decompilation.
- 4 months ago @askalphaxiv
TMAX trains terminal agents with diverse Dockerized RL environments
The TMAX post describes 14.6k Dockerized RL environments and an outcome-only DPPO recipe for training terminal agents. It reports a 9B model reaching 27% on Terminal-Bench 2.0.
The recipe and environment design may help engineers train terminal agents for multi-turn shell tasks.
A Proposal for Training-Free Reasoning with Verified Examples
The post proposes keeping an LLM frozen and retrieving verified reasoning from an external pool instead of updating weights. It uses SymbCoT-style symbolization for checking logical structure; whether this can approximate RL gains remains open.
It outlines a possible alternative to weight updates, while highlighting verification and deployment as unresolved challenges.
- Reinforcement learningArticle
Infrastructure optimizations for RL at trillion-parameter scale
A deep dive into prime-rl 0.6.0 training trillion-parameter MoE models, covering FP8, wide expert parallelism, P/D disaggregation, router replay, and 3-D parallelism.
Engineers can review training and inference techniques for scaling RL workloads on large MoE models.
 arxiv.org