


RAG and retrieval
Chunking, embeddings, rerankers, evaluation and what holds up in production.
66 links, newest first.
- RAG and retrievalPost on X
MTEB v2 updates the embedding evaluation suite
The MTEB team released version 2 of its evaluation suite for embedding models. The accompanying blog post covers easier evaluation, multimodal support, rerankers, new interfaces, documentation, dataset statistics, and a migration guide.
Engineers evaluating embedding models can review the suite’s updated capabilities and migration guidance.
- RAG and retrievalRepository
Open-source RLM implementation for long-context processing
A Python implementation of Recursive Language Models stores long input in a Python REPL for analysis. The project says it supports 100+ LLM providers through LiteLLM.
Engineers evaluating alternatives to RAG for processing very long documents can inspect the implementation.
- RAG and retrievalArticle
Information Retrieval Papers: Generative Embeddings and Document Retrieval
Vol. 124 of a weekly information retrieval paper roundup, covering generative embeddings with test-time scaling and efficient visual document retrievers.
A paper roundup can help engineers track research relevant to retrieval systems.
- RAG and retrievalPost on X
REFRAG Replaces Retrieved Tokens with Reusable Chunk Embeddings
A paper introduces REFRAG, which replaces most retrieved tokens with precomputed, reusable chunk embeddings. The post says it achieves 30× speed and supports 16× longer contexts without accuracy loss.
It describes a retrieval change aimed at improving RAG speed and context capacity.
- RAG and retrievalPost on X
Curated resources on GraphRAG
Awesome-GraphRAG is a curated list of surveys, papers, benchmarks, and open-source projects on graph-based retrieval-augmented generation.
It offers engineers a starting point for exploring research, benchmarks, and projects focused on GraphRAG.
- RAG and retrievalPost on X
LogicRAG Builds a Reasoning Graph at Query Time
LogicRAG plans a per-query DAG of dependent subproblems, retrieves evidence in order, and carries forward a rolling summary. The post says it outperforms GraphRAG systems on three multi-hop QA sets without offline graph building.
The approach offers an alternative to prebuilt knowledge graphs for multi-hop retrieval.
- RAG and retrievalPost on X
Survey Reviews Memory Mechanisms in LLM-Based Agents
A post describes a survey by Renmin University of China and Huawei covering memory design and evaluation, applications, limitations, and future directions for LLM-based agents.
Its overview of memory design and evaluation may inform engineers building agents for long-term tasks.
- RAG and retrievalPaper
VideoRAG retrieves videos for multimodal RAG
VideoRAG is a framework proposed by research teams from KAIST for retrieving query-relevant videos and incorporating visual and textual information into generated responses. It uses automatic speech recognition to create auxiliary text when videos lack subtitles.
It offers an approach to bringing video content into RAG retrieval and response generation.
- RAG and retrievalPost on X
Graphiti builds temporal knowledge graphs for evolving data
Graphiti builds and queries dynamic knowledge graphs that represent relationships between entities over time. It handles temporal data and supports multiple search methods.
Engineers exploring retrieval beyond conventional document search may find its temporal knowledge-graph approach relevant.
- RAG and retrievalPost on X
Auto-RAG Uses Iterative Retrieval for RAG
The post describes Auto-RAG, a fine-tuned LLM that plans retrievals and refines queries through multiple turns until it has enough external information. It says the method adjusts the number of iterations based on question difficulty.
It highlights an approach to automating retrieval planning and query refinement in RAG systems.
- RAG and retrievalPost on X
RARe Uses Retrieved Examples to Adapt Retrieval Models
The paper proposes RARe, which augments queries with task instructions and semantically similar query-document examples retrieved with BM25. The post reports that similar examples outperform random ones, with gains as the number of examples increases up to 10 tested.
It explores a way to apply in-context examples to retrieval models and reports retrieval performance changes.
- RAG and retrievalPost on X
HijackRAG Uses Injected Text to Target RAG Systems
The post describes HijackRAG, an attack that combines retrieval, attention-hijacking, and instruction text to manipulate RAG outputs. It outlines black-box and gradient-based white-box modes.
The attack highlights risks from malicious content in a RAG knowledge base and the limits of existing defenses.
- RAG and retrievalPost on X
AssistRAG separates memory and retrieval from answer generation
AssistRAG uses a trainable assistant LLM for memory and external-knowledge management while keeping the main answer-generating LLM frozen. Its training combines Curriculum Assistant Learning and Reinforced Preference Optimization.
The design offers an approach to adding memory and knowledge management without retraining the main LLM.
- RAG and retrievalPost on X
LazyGraphRAG combines vector and graph retrieval
The post describes LazyGraphRAG as combining vector RAG with iterative breadth-first and best-first search, while avoiding index summarization. It says the approach targets one-off queries, exploratory analysis, and streaming data.
Its retrieval and indexing trade-offs may help engineers assess alternatives to full GraphRAG.
- RAG and retrievalRepository
Notebook: RAG over PDFs with Docling and Weaviate
A recipe notebook demonstrates RAG over PDF files using Docling and Weaviate. Docling is described as an open-source Python package that converts documents including PDFs to Markdown or JSON.
Useful as a practical starting point for building a PDF-based RAG pipeline with Docling and Weaviate.
- RAG and retrievalPost on X
Autoflow is a Graph RAG knowledge base built with TiDB
The post describes pingcap/autoflow as a conversational knowledge base based on Graph RAG, using TiDB Serverless for vector storage.
Engineers evaluating Graph RAG tools can note its use of TiDB Serverless as vector storage.
- RAG and retrievalRepository
OpenScholar Releases Code, Models, and a 45M-Paper Datastore
OpenScholar releases code and model checkpoints, an OpenScholar Datastore with 45M+ papers through October 2024, and ScholarQABench. Its project page describes a research assistant for finding, summarizing, and analyzing scientific evidence.
Engineers can inspect an open research-assistant stack and its paper datastore, models, and evaluation benchmark.
- RAG and retrievalPost on X
KAR Uses Knowledge Graphs for Query Expansion
KAR parses query entities with an LLM, retrieves relevant documents, propagates through knowledge-graph relations, scores and filters those relations, and generates knowledge-aware query expansions.
The workflow offers a concrete approach to expanding retrieval queries with document context and knowledge-graph relations.
- RAG and retrievalPost on X
SimpleQA: A Benchmark for Factuality and Hallucinations
SimpleQA contains 4,000 human-written fact-seeking questions with single, indisputable answers. An autograder labels responses correct, incorrect, or not attempted; reference answers were verified by two annotators.
Engineers can use it to evaluate model factuality with a human-written question set and verified reference answers.
- RAG and retrievalPaper
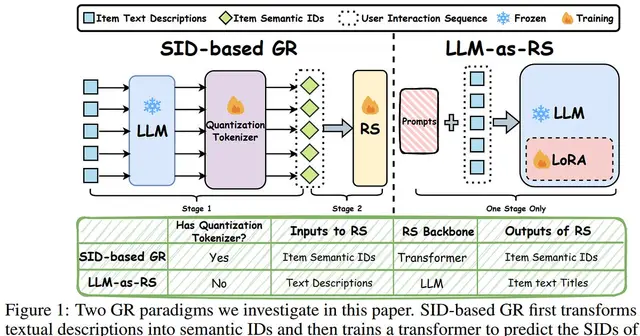
FACT uses iterative context rewriting for multi-fact retrieval
The paper introduces Find All Crucial Texts (FACT), an iterative approach to context rewriting for multi-fact retrieval. It examines how models can lose track of critical information while generating from extended contexts.
It explores a retrieval failure mode that can lead to incomplete answers when a task requires combining multiple facts.
 arxiv.org
Build with AgentLog
Send your own newsletter
CommsHarbor keeps contacts, consent and one-click unsubscribe together.
Free workspace
Open CommsHarbor