LLM inference
- LLM inferencePost2 years ago @rohanpaul_ai
AirLLM runs large models with layer-wise inference
AirLLM uses layer-wise inference, loading one Transformer layer at a time from disk so the full model need not stay in GPU memory. The post also describes block-wise quantization and compression support.
Engineers evaluating inference on memory-constrained GPUs may find its layer-loading approach relevant.
- LLM inferencePost2 years ago @reach_vb
AI21 releases Jamba 1.5 Mini and Large
AI21 Labs announced Jamba 1.5 Mini and Large, MoE models combining Mamba and Joint Attention with a 256K context window. The post mentions ExpertInt8 quantization, JSON mode, tool use, and Transformers integration.
The models’ architecture and quantization are relevant to engineers evaluating LLM inference options.
- LLM inferencePost2 years ago @rohanpaul_ai
Llama 3.1 8B Inference on One RTX 3090
The post says a Backprop blog benchmark of Llama 3.1 8B in fp16 on one RTX 3090 found reasonable tokens per second at 100+ concurrent requests.
It offers a reference point for evaluating single-GPU inference capacity under concurrent load.
- LLM inferenceProject
LLM Compressor brings model compression tools to vLLM
Neural Magic released LLM Compressor, a library for applying compression algorithms including GPTQ, SmoothQuant, and SparseGPT. The post says compressed models aim to reduce inference latency while maintaining accuracy.
Engineers using vLLM can explore one library for several model-compression methods.
- LLM inferencePost2 years ago @hu_yifei
SGLang and vLLM throughput comparison on A6000 GPUs
An engineer reports replacing vLLM with SGLang in a local data-generation pipeline. On four A6000 GPUs running 4-bit Mistral Large 2, they report about 1,100 tokens/s with SGLang versus under 750 with vLLM; performance is similar at smaller batch sizes.
The comparison highlights how inference throughput can vary by serving engine and batch size on the same hardware and model.
- LLM inferenceArticle
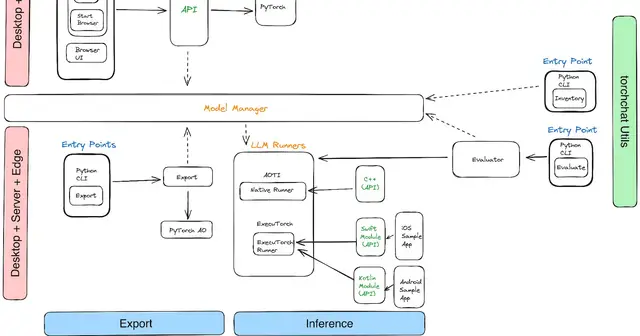
PyTorch introduces torchchat for local LLM inference
Torchchat is a PyTorch library for running Llama 3, 3.1, and other large language models on laptops, desktops, and mobile devices. The post describes it as designed for seamless, performant local inference.
Engineers exploring local LLM deployment across device types can evaluate the library.