Attention and model architecture
Looped Flows Train Recurrent Updates with Local Denoising
The paper proposes looped flows, which train recurrent hidden-state updates using local denoising objectives. It aims to address the difficulty of training early updates to support later ones when backpropagation covers only a few updates.
Engineers exploring recurrent inference architectures can learn about an alternative training objective for looped models.
- 2 months ago @alec_helbling
Flow Reasoning Models use recurrent flows for structured reasoning
Flow Reasoning Models (FRMs) use a recurrent flow-based architecture to solve structured reasoning problems such as Sudoku. They apply continuous flows to discrete data and refine past mistakes through self-conditioning.
The post describes an architecture that combines continuous flows with recurrent refinement for discrete reasoning tasks.
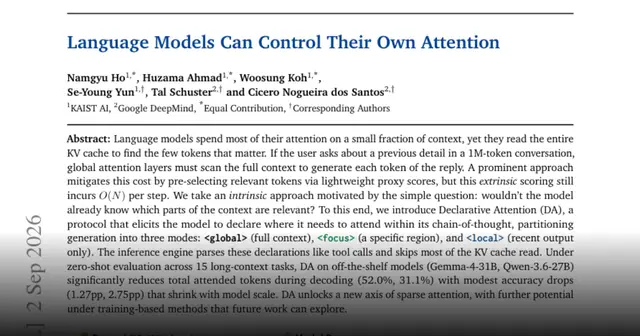
Language Models Can Control Their Own Attention
A paper titled “Language Models Can Control Their Own Attention” is linked; the page provides a discussion for the paper.
The paper’s focus may be relevant to engineers exploring attention mechanisms in language models.
Depth-wise batching for recurrent models
The post describes overlapping requests at different recurrent depths as “depth-wise batching,” saying it can improve utilization with adaptive compute. It links to work on Recursive Transformers and MoR.
The idea connects recurrent depth and request scheduling to utilization in models with adaptive compute.
Astra’s recurrent-depth approach raises monitoring concerns
A post says OpenAI’s Astra AI uses a reasoning approach called “recurrent depth.” Researchers are concerned it may make the model’s thinking process harder to monitor.
The approach may affect both model costs and performance, while complicating oversight.
- 2 months ago @kyleichan
Post claims Chinese frontier models share efficiency-focused designs
The post claims Chinese frontier models are adopting linear or sparse attention, specialized residual designs, and Muon, and frames open-source collaboration as a strategy for efficient models.
It highlights architecture and optimization techniques engineers may want to investigate, while presenting broad adoption claims without supporting links.
- 2 months ago @AryaTschand
Post claims GLM-5.3 combines linear and sparse attention
The post claims GLM-5.3 uses three linear-attention layers for each sparse-attention layer, combining subquadratic attention variants. It contrasts this design with other hybrid and sparse-attention models.
The architecture claim highlights trade-offs in compute-efficient attention for long-context models.
- 2 months ago @rasbt
GLM-5.3-Flash Architecture Overview
The post identifies Ox Alpha as GLM-5.3-Flash and describes its 3:1 hybrid attention pattern, smaller sparse MoE backbone, four-stream mHC residual path, and native vision encoder.
The architecture details offer engineers a concise view of how GLM-5.3-Flash combines attention, MoE, and residual-path components.
CTM-AI applies a consciousness model to AI architecture
The paper presents CTM-AI, an early blueprint for a general AI system inspired by the Conscious Turing Machine. The preview describes it as combining the model with other components, but does not provide benchmark results.
It explores whether a formal model of consciousness can inform AI system architecture.
DeepSeek's Engram module retrieves embeddings from token n-grams
Engram hashes the last N input tokens to retrieve multi-head embeddings, applies a context-aware gate, then adds the result to a layer's hidden state. The post says the lookup table can be offloaded to CPU with little inference slowdown.
Engineers exploring model architectures can assess a lookup-based module for adding token n-gram information during pretraining.
Understanding Transformers and Attention Mechanisms
This paper explains Transformers from an applied-mathematics perspective, covering vector representations, attention, Multi-Head Attention, and core architecture components. It also discusses KV caching, Grouped Query Attention, and Latent Attention as ways to reduce attention costs.
It connects the linear algebra behind attention to methods for reducing its computational and memory costs.
- 3 months ago @BrianRoemmele
Paper links consciousness safety tuning to mind attribution
The post describes a paper reporting that safety fine-tuning against models claiming consciousness also reduces mind attribution across other entities in Llama-3-8B-IT and two Gemma-2 models. It says mechanistic interventions restore these tendencies.
The reported residual-stream direction may help engineers examine how safety fine-tuning affects capabilities beyond its target.
A chronological reading list on Looped Transformers
A chronological list of papers on Looped Transformers, including Universal Transformers, Relaxed Recursive Transformers, Mixture-of-Recursions, and DeepLoop.
Useful for engineers comparing approaches to recurrent computation and parameter sharing in Transformer architectures.
DeepLoop studies depth scaling for looped Transformers
The paper examines how looped Transformers reuse a compact stack of blocks across multiple rounds, increasing unrolled depth without adding stored parameters. It analyzes how parameter sharing changes residual scaling.
Useful for engineers exploring parameter-efficient depth scaling and training stability in looped architectures.
- 3 months ago @hardmaru
Diffusing Blame Trains Networks Under Dale’s Principle
The post describes a routing method that sends error signals to hidden layers to train networks of dedicated excitatory and inhibitory neurons without backpropagation. It reports results on image recognition, locomotion, and Craftax.
It explores an alternative to backpropagation for training networks with biologically constrained neuron types.
Sparse Delta Memory adds sparse-addressed memory to RNNs
The post describes Sparse Delta Memory (SDM), which uses sparse addressing to read and write an explicit memory alongside an RNN. It claims this increases state capacity while keeping per-token compute flat.
Engineers exploring long-context architectures can assess a memory design intended to expand RNN capacity without increasing per-token compute.
MiniCPM-SALA combines sparse and linear attention
MiniCPM-SALA is a 9B-parameter hybrid architecture for long-context modeling that integrates sparse and linear attention. The post reports strong long-context benchmark results and inference scaling to 1M tokens.
The paper explores how hybrid attention can balance context quality, compute, and memory use.
Rethinking Thinking Tokens with LLM Improvement Operators
The paper asks whether models can use metacognition to improve the trade-off between accuracy, context length, compute cost, and latency, rather than relying on long chains of thought.
It explores alternatives to long chain-of-thought reasoning that could reduce context and latency costs.
Grok’s Triton Paged Attention Kernel
A post shares a paged attention kernel attributed to Grok, with a link to a solution file hosted on KernelBench.
Engineers can inspect the implementation of a paged attention kernel.
Three papers on efficient LLM serving
The post recommends papers on PagedAttention, Sarathi-Serve, and SGLang, highlighting KV-cache management, chunked prefills, scheduling, and structured generation. The PagedAttention paper describes virtual-memory-inspired KV-cache management to reduce fragmentation and duplication.
These papers cover techniques for managing KV-cache memory and improving LLM serving throughput and utilization.
 arxiv.org