


resubmit-pipeline
wanshuiyin/auto-claude-code-research-in-sleep · skills.sh
Open source Repository Open in the app JSON README (API)
About
Skill publicada por wanshuiyin/auto-claude-code-research-in-sleep no skills.sh. Instale com: npx skills add wanshuiyin/auto-claude-code-research-in-sleep@resubmit-pipeline
Details
- Kind
- Agent skills
- Publisher
- wanshuiyin
- Origin
- skillssh
- Category
- ferramentas
- Stars
- 17,029
- Forks
- 1,432
- Open pull requests
- 14
- Last push
- 2026-10-05T15:31:25Z
- Repository state
- ativo
- Language
- Python
- License
- MIT
- Added
- 2026-10-06 04:50:49
- Updated
- 2026-10-06 04:50:49
- Origin id
wanshuiyin/auto-claude-code-research-in-sleep/resubmit-pipeline
README
# Auto-claude-code-research-in-sleep (ARIS ⚔️🌙)
<p align="center">
<a href="https://huggingface.co/papers/2605.03042">
<img src="https://raw.githubusercontent.com/wanshuiyin/auto-claude-code-research-in-sleep/HEAD/docs/hf_daily_paper_1.svg" alt="Hugging Face Daily Paper · #1 Paper of the Day" width="360">
</a>
</p>
[](#quick-start) · [](#how-to-run) · [](https://huggingface.co/papers/2605.03042) · [](https://wanshuiyin.github.io/Auto-claude-code-research-in-sleep/ARIS_INTRO.html) · [](docs/aris_intro_slides.pdf) · [](AGENT_GUIDE.md) · [](https://mp.weixin.qq.com/s/tDniVryVGjDkkkWl-5sTkQ) · [](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/stargazers) · [💬 Join Community](#community) · [](#citation)
🌱 *ARIS is a methodology, not a platform. What matters is the research workflow — take it wherever you go.*
💡 *Use ARIS as a skill-based workflow in [Claude Code](https://docs.anthropic.com/en/docs/claude-code) / [Codex CLI](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/skills/skills-codex/) / [Cursor](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/CURSOR_ADAPTATION.md) / [Trae](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/TRAE_ARIS_RUNBOOK_EN.md) / [Antigravity](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/ANTIGRAVITY_ADAPTATION.md) / [GitHub Copilot CLI](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/COPILOT_CLI_ADAPTATION.md) / [OpenClaw](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/OPENCLAW_ADAPTATION.md) / [DeepSeek Harness](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/tree/dsh-aris#readme) — enjoy any way you like!*<br>*The executor drives, an independent model (Codex MCP by default) reviews. [Alternative model combinations](#alternative-model-combinations), including [ModelScope](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/MODELSCOPE_GUIDE.md)-hosted models, need no Claude or OpenAI API.*
📦 *Those are the skills installed directly. Want it in one command? ARIS also ships as a standalone CLI and as plugins:* [](docs/ARIS-Code-README_EN.md) · [](#plugins) · [](#plugins) · [](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/tree/dsh-aris#readme)
❗  **codex-cli 0.154.0 removed `codex mcp-server` — the entry point every ARIS reviewer call used. No impact on ARIS:** the `codex` MCP server is now ARIS's own bridge over `codex exec` (`mcp-servers/codex-exec/`), same tools, same results, all 82 skills unchanged, `ultra` and per-thread resume intact. One re-registration is all it takes — **[already installed? → Quick Start step 2b](#quick-start)** · **[new install → step 2](#quick-start)** · [what changed](#whats-new).
**🧩 The ARIS family** — same method, other jobs. One line each; the details live in their own repos.
[](https://github.com/wanshuiyin/ARIS-in-AI-Offer) — **EasyAIOffer**: 34 bilingual ML / LLM interview cheat sheets on [one page](https://wanshuiyin.github.io/ARIS-in-AI-Offer/) — derivations, from-scratch PyTorch, 25 questions each. 希望大家秋招轻松一点 🌱
[](https://github.com/wanshuiyin/HERO-Anti-OverDefense) · [](https://github.com/wanshuiyin/Anti-Autoresearch) — two sides of one disease. HERO: a ~550-token block for `CLAUDE.md` / `AGENTS.md` against the four shapes agents over-defend in (Hashing, Edge cases, Rubrics, Overbuild), bounding what the agent *proposes*, never what it *looks for*. Anti-Autoresearch: 61 integrity signals into a deterministic, reviewer-ready report — fabrication forensics, not an AI-text detector.
[](https://github.com/wanshuiyin/ARIS-Movie-Director) — **ARIS goes multimodal**: a rough story in, a movie told in still frames out, every scene checked by another model; the same loop draws clean method diagrams (`/method-figure`).
[](aris-monitor/) — a tiny always-on-top macOS widget that lights up 🔴 when a session waits for your approval; `cd aris-monitor && ./run.sh`. Many windows? [Claude Fleet](https://github.com/tianyilt/claude-fleet) by [@tianyilt](https://github.com/tianyilt) is the full dashboard.
🔥 [**ARIS-Code CLI — 独立安装版**](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/ARIS-Code-README_CN.md) · [English](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/ARIS-Code-README_EN.md) | [⬇️ Download](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/releases/latest) · [](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/releases) — **v0.4.28**: `ARIS_REASONING_EFFORT` works on the Anthropic channel, tool calls through `{}`-placeholder relays fixed, OS proxy honoured. v0.4.27: launching and quitting the REPL leaves no empty session file. v0.4.26: the `fable` alias and `/model` now point at Fable 5.1 (default stays Opus 5). v0.4.25: the Codex reviewer works again on codex-cli ≥ 0.154 (built-in `codex exec` bridge, nothing to register), `/since` takes you back to your last input, `/resume` lists sessions by index, Windows multi-line paste fixed (pending confirmation), 83 bundled skills on GPT-6-Astra.
<details><summary>ARIS-Code — screenshot, what's in v0.4.28, per-release details, older versions</summary>
<p align="center"><img src="https://raw.githubusercontent.com/wanshuiyin/auto-claude-code-research-in-sleep/HEAD/docs/aris-code-banner.png" width="100%" alt="ARIS-Code CLI terminal — Auto Research in Sleep"></p>
📰 **ARIS-Code v0.4.28** (2026-09) — latest: **`ARIS_REASONING_EFFORT` works on the Anthropic channel** ([#446](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/446)), tool calls through relays that send a `{}` placeholder no longer fail ([#444](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/444)), and the OS proxy on Windows / macOS is used without exporting `HTTPS_PROXY` ([#401](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/401)). v0.4.27: launching and quitting the REPL no longer leaves an empty session file, and `/resume` lists only sessions with messages ([#439](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/439) follow-up). v0.4.26 made **Fable 5.1** the `fable` alias and the first `/model` entry (the default executor stays Opus 5). v0.4.25 is the **reviewer-bridge release**: codex-cli 0.154 removed `codex mcp-server`, so every Codex review from ARIS-Code died on an updated codex. The reviewer now runs over a **built-in `codex exec` bridge** — no `mcpServers.codex` entry, old entries migrate in memory, thread records interoperate with ARIS's Python bridge. Also: **`/since`** replays everything after your last input (folded like the live display, `/since full` for complete output), **`/resume`** lists sessions with indices and shows where you stopped ([#439](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/439)), Windows multi-line paste no longer submits line by line ([#430](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/430), pending confirmation), the Windows shim message carries the native installer ([#428](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/428)), and the bundle moves to **83 skills** on **GPT-6-Astra**. Recent headliners: **v0.4.24 — Claude 5 model refresh** (Opus 5 default, Fable 5 tier, availability chain) and **v0.4.23 — output folding**. Caps a 24-release run (v0.4.5 → v0.4.28); per-release detail below. Credits: [@GetIT-Sunday](https://github.com/GetIT-Sunday), [@Anduin9527](https://github.com/Anduin9527), [@GO-player-hhy](https://github.com/GO-player-hhy), [@Jxy-yxJ](https://github.com/Jxy-yxJ), [@screw-44](https://github.com/screw-44), [@StevenUST](https://github.com/StevenUST), [@opposj](https://github.com/opposj), [@ShijunLei-cn](https://github.com/ShijunLei-cn), [@algojogacor](https://github.com/algojogacor), [@YukinoshitaLove](https://github.com/YukinoshitaLove), [@jinliye-2026](https://github.com/jinliye-2026), [@SajimJC](https://github.com/SajimJC), [@JasmineLCY](https://github.com/JasmineLCY).
> <details><summary>Per-release details (v0.4.5 → v0.4.28)</summary>
>
> **v0.4.28** (2026-09-28) — **`ARIS_REASONING_EFFORT` now works on the Anthropic channel** ([#446](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/446)): `low` / `medium` / `high` / `xhigh` / `max` for the main session and subagents; unset, requests are unchanged. **`ARIS_MAX_TOKENS`** raises the output cap when a high effort runs into it. **`autoCompactEnabled: false`** in settings turns automatic compaction off. **🐛 [#444](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/444)** tool calls through relays that send a `{}` placeholder no longer fail with `invalid tool input JSON`. **🌐 System proxy** on Windows / macOS is used without exporting `HTTPS_PROXY` ([#401](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/401), by @JasmineLCY); `NO_PROXY=*` connects directly as before. **Upgrading:** if you already export `ARIS_REASONING_EFFORT`, have an OS proxy, or have `autoCompactEnabled: false` in settings, read the [upgrade notes](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/blob/aris-code/CHANGELOG.md).
>
> **v0.4.27** (2026-09-19) — launching and quitting the REPL no longer leaves an empty session file; `/resume` lists only sessions with messages ([#439](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/439) follow-up).
>
> **v0.4.26** (2026-09-16) — **Fable 5.1**: the `fable` alias now resolves to `claude-fable-5-1`, `/model` lists Fable 5.1 first (Fable 5 stays selectable) and the system-prompt identity names it; the default executor remains `claude-opus-5` (the Mythos tier is $10/$50 vs Opus 5's $5/$25, so the default does not move). Saved `executor_model` values are ids, not aliases, and are untouched. Pricing already matched on `fable`; a test pins 5.1. Tests unchanged (aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6). Codex MCP (gpt-6-astra xhigh) gate: GO.
>
> **v0.4.25** (2026-09-16) — **the reviewer-bridge release**. codex-cli 0.154 removed `codex mcp-server`, the entry point ARIS-Code's `aris setup` had written into settings.json for every Codex review; on an updated codex every review call died. **Built-in `codex exec` bridge**: `mcp__codex__codex` / `codex-reply` run as `codex exec --json` with nothing to register — no settings entry, a legacy `codex mcp-server` entry is migrated in memory (env, `-c` defaults, `requestTimeoutSecs`, trust kept), an explicit Python-bridge entry is used as configured, thread records share `~/.codex/state/codex-exec/threads/` with the Python bridge, 1800 s budget for `ultra` audits, `ARIS_CODEX_BRIDGE=0` restores the old path; `aris doctor` prints the effective backend. Found on the way: the model never received a Codex result's `threadId` (it lives only in `structuredContent`), so `codex-reply` could not continue a thread — results now start with a `threadId:` line. **`/since [full]`** replays the user's last input and everything after it with the live formatters (display only; after `/resume` and in `--resume` batch mode too); a dim hint after turns with ≥ 8 tool calls (`ARIS_TURN_SUMMARY=0`). **#430** Windows consoles deliver no paste event, so each pasted line became its own Enter — lines are now merged into the input and never auto-submitted, Ctrl+C discards the rest (`ARIS_PASTE_BURST=0`; inferred from crossterm's source, pending confirmation on a Windows machine). **#439** `/resume` lists sessions with `[n]` indices and ages and accepts an index, a unique id prefix or a path; the last turn is replayed after loading. **#428** the `.cmd`-shim message carries the official native installer one-liner. **Bundle 81→83** (pin 3e49e63 → 4734364): `/proof-orchestrator`, `/research-implement-feature`, 32 helpers (+`review_gate.py`, `copilot_native_evidence.py`, `idea_discovery_gate.py`), repo-root `templates/` bundled; reviewer doctrine and system prompt on **gpt-6-astra** (fallback gpt-5.6-sol → gpt-5.5), explicit `— reviewer:` directives win, `LlmReview` results carry `reviewer_model:` so HTTP rounds report to `review_gate.py` truthfully; gpt-6-astra pricing tier $10/$50 (cache write $12.50, read $1). Tests: api 35+6 / aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6, all green; live `codex exec` fresh + resume roundtrip on codex-cli 0.154.0. Codex MCP (gpt-6-astra): ultra design gate (2 rounds), xhigh implementation gate per step (5/2/2/2 rounds), final whole-diff gate (2 rounds) → GO.
>
> **v0.4.24** (2026-08-09) — **the Claude 5 model refresh** ([#392](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/392), requested by [@YukinoshitaLove](https://github.com/YukinoshitaLove)). Explicit `--model claude-opus-5` / `claude-fable-5` already passed through on every platform — this release makes them first-class. **Default → `claude-opus-5`** (main session, subagents, `aris setup`; same $5/$25 tier as Opus 4.8); the v0.4.18 availability fallback becomes an ordered **chain walk** (Opus 5 → Opus 4.8 → Opus 4.7, one step per precise `404 not_found_error`, explicit choices never silently change) — the naive constant swap would have stranded 4.7-only accounts and configs saved by v0.4.23's setup, a regression the cross-model review caught and an end-to-end mock-404 chain test now locks. `/model` picker adds Fable 5 / Opus 5 / Sonnet 5; new `fable` alias. **New Mythos-class pricing tier** (`fable`/`mythos` = $10/$50, cache write $12.50 / read $1, verified 2026-08 — previously fell to the conservative $15/$75 unknown-model tier, a 1.5× over-estimate); Opus 5 / Sonnet 5 pinned on their existing branches. Tests: api 41 / aris-cli 213 + 4 e2e / runtime 226 / tools 70 / commands 5, all green; live smoke on claude-opus-5, claude-fable-5 and the fable alias. Codex MCP (gpt-6-astra xhigh) implementation gate: NO-GO → NO-GO → GO.
>
> **v0.4.23** (2026-08-02) — **the output-folding release** (top real-user complaint: "aris dumps thinking and the full content of documents it reads onto the screen"). **🧹 Tool-output folding, display layer ONLY**: the disk-verified culprits were format_read_result appending the ENTIRE read payload, bash pushing full stdout/stderr, grep dumping its full content blob, and the edit preview capping line counts but not line LENGTH. Now Read/Grep show the first 6 lines, Bash shows first 4 + last 4 per stream (stderr keeps its red), each kept line capped at 240 chars (the minified-single-line case), then one dim "… (+N more lines — set ARIS_TOOL_OUTPUT_LINES=0 for full output)" hint. ONE env knob: unset = defaults, a positive integer overrides every tool, 0 = the exact old display; the session, model context, `--output-format json` and `/export` are untouched and always complete. Thinking was verified to never print (Anthropic deltas only accumulate; Kimi reasoning_content only feeds the replay cache — the "thinking dump" perception came from the document dumps); two end-to-end sentinel tests (real binary vs mock SSE server) lock that thinking/reasoning never reaches the terminal. Interactive expand/collapse was deliberately rejected as over-engineering. **🐛 Bash timeout now kills the command**: a timed-out call reported `interrupted: true` while the dropped tokio future left the child RUNNING — side effects landed after the report; now kill_on_drop (escape hatch `ARIS_BASH_KILL_ON_TIMEOUT=0`; background tasks untouched; locked by a real behavioral test — a timed-out "sleep 1 && touch marker" must not create the marker). **📦 Bundle 79→81** (pin 7182624 → 3e49e63): **`/integrity-forensics`** — the Anti-Autoresearch SHA-pinned thin launcher (span-anchored evidence ledger → GPT auditors propose → deterministic rules-only adjudicator decides → typed BLOCK/WARN gate + obligations ledger) — and `/web-debug-search`, +tools/forensics_gate.py (29 helpers, 104 embedded resources). **🎁 Also**: grep's content mode no longer shows a false "0 matches" above real results (the gate caught that `"numMatches": null` serializes with the key present, defeating a naive presence check); all four crates' local-mock-server tests are now proxy-immune (a shell with http(s)_proxy set used to turn 15 tests red on a released tag — 127.0.0.1 was routed through the proxy). The rest of the runtime-state package (compaction re-arm, failed-turn cleanup, /cost dollars, SSE tail) ships as v0.4.24 — the cached-token cost fix is deliberately held back because it changes what the compaction trigger measures. Tests: api 41 / aris-cli 212 + 3 e2e / runtime 225 / tools 69 / commands 5 (+13), all green **under a live proxy**; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra scope+design adjudication, then a 3-round implementation gate (round 1 caught the null-serialization defeat and a non-hermetic behavioral test; round 3 GO).
>
> **v0.4.22** (2026-07-12) — **the skills-resync + GPT-6-Astra release**. **📦 Bundle resync** (pin 7e3ab67 → 7182624, 93 commits): **79 bundled skills** (+`meta-apply`, +`paper-poster-html`; `paper-poster` retired to a redirect stub), 28 tools helpers (8 new: capture_filter, evidence_check, iteration_log, provenance, run_state, threat_scan, meta_opt/trigger_eval + sample evals), 11 new shared-references docs (fan-out-pattern, acceptance-gate, external-cadence, skill-governance, compute-env-contract, resumable-runs, evidence-precheck, injection-hygiene, capture-antipatterns, output-composition, taste-calibration); sync hardening — `ARIS_SYNC_EXPECT_SHA` guard (aborts before touching assets if main moved; it caught a real move on first use) + exact-inventory drift tests + the vendored posterly MIT license text now ships. **🎛 GPT-6-Astra two-tier reviewer alignment**: the CLI's system-prompt nudge now passes the skills' explicit `model: gpt-6-astra` + per-call effort pins through (the v0.4.17 blanket "never pass a model" rule would have silently stripped deep audits from ultra to xhigh), carries the canonical capability-only fallback chain (effort-unsupported → same model xhigh, deep tier only; model-unknown → explicit gpt-5.5+xhigh; never degrade on transport-class errors; an explicit call-level override disables the chain), pins `approval-policy: "never"` + explicit `sandbox` on every fresh codex call, and makes the HTTP fallback pre-dispatch-only with parameter stripping; the HTTP LlmReview default deliberately stays gpt-5.5 pending a real smoke; gpt-5.6 family pricing (sol $5/$30, terra $2.50/$15, luna $1/$6) verified against the official page; banner/Reviewer display/`/reviewer` are honest about primary-vs-fallback (pure-Codex setups get status + guidance instead of a fake picker). **🐛 8 verified fixes**: explicit `--model` was silently overridden by the saved executor model (model provenance now tracked end-to-end; the 4.8→4.7 availability fallback respects explicit choices; `/model` and `/setup` re-arm it); saved models no longer leak across provider transports (blank saved models count as absent; OpenAI transport with no model source fails fast; the first-run wizard's config now actually feeds startup model resolution); `--output-format json` never prompts (locked by a real end-to-end binary test against a mock SSE server); **Windows `aris login` fixed** (PKCE randomness read /dev/urandom → getrandom); **Windows command probing fixed** (the PowerShell tool probed itself through `sh`; now where.exe); codex `.cmd` shims classified honestly (three-state probe; setup requires explicit confirmation before writing a config the MCP client can't spawn); nested config.json warns instead of silently parsing to all-defaults; NotebookEdit mints collision-free cell ids. **🖥 New windows-latest CI job** (workspace compile gate + three targeted test groups, each guarded against silent 0-test green). Tests: api 41 / aris-cli 204 + 1 e2e / runtime 223 / tools 69 / commands 5 (+54), all green; new-code clippy delta zero. Codex MCP (gpt-6-astra): **ultra** design gate — 5 rounds, NO-GO ×4 → GO — then a 3-round implementation gate whose round 2 caught a first-run config-wiring blocker before it shipped; 4 implementation subagents, every report disk-verified.
>
> **v0.4.21** (2026-06-28) — **bug-fix patch**: 5 new user-facing bugs from a Codex adversarial hunt (all disk-verified, distinct from v0.4.20), each cross-model reviewed at a design gate and an implementation gate (gpt-5.5 xhigh; both started NO-GO — the reviewer caught an off-by-one in the grep line-mapping and a missing stream-level test before GO). **🐛 Headline**: OpenAI-compatible streaming corrupted multi-byte UTF-8 (CJK / emoji) split across network chunks into `�` — each HTTP body chunk was `from_utf8_lossy`'d independently, so a 3-byte Chinese character or 4-byte emoji straddling a chunk boundary broke on both sides (a frequent hit for Chinese users on domestic OpenAI-compatible providers — Kimi/GLM/MiniMax/DeepSeek/Qwen/Doubao — streaming Chinese text); the stream buffer is now raw bytes, decoding only complete SSE lines. **A saved OpenAI/custom executor config no longer overrides a shell-set `EXECUTOR_PROVIDER`** — the startup "shell-provided vars win" path had one ungated write that re-pointed `EXECUTOR_PROVIDER=anthropic … aris …` to OpenAI (wrong executor / model-not-found). **An Anthropic stream truncated after content but before a terminal signal now hard-errors** (`premature_eof`) instead of saving a half-finished answer to history as a complete turn (symmetric to the OpenAI `#249` guard; the `stop_reason`-only compat path is preserved, and `ARIS_ALLOW_EOF_WITHOUT_STOP=1` opts a terminal-signal-less proxy back into the old behavior). **`grep_search` with `multiline: true`** now matches across lines in content mode (was silently empty — `count` mode already worked). **MCP tool results carried only in `structuredContent`** (empty `content`) are no longer dropped — the model gets the JSON structured payload. Tests (CI mode): api 32→35 / runtime 205→212 / tools 67 / aris-cli 172→181 / commands 5 (+21, incl. 2 stream-level integration tests), all green. Codex MCP (gpt-5.5 xhigh): design gate (NO-GO → GO after fixing the off-by-one) → implementation gate (NO-GO → GO after adding the stream-level integration tests); the Anthropic streaming spec (every stream ends with `message_stop`) was WebFetch-verified. Two latent-only candidates (Anthropic block-`index` routing, OpenAI multi-line SSE) remain deferred.
>
> **v0.4.20** (2026-06-19) — **bug-fix patch**: 7 user-facing bugs surfaced by a Codex adversarial hunt, each reviewed across 3 rounds (the reviewer caught a redraw gap, a trailing-blank, a spinner tail, and a blank-line edge before GO). **🐛 Headline ([#299](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/299))**: short REPL replies showed only "✔ Done" — the spinner draws "⠋ Thinking…" with Save/RestorePosition so streamed output overwrites it on the same line, but `finish` then cleared that whole line, **erasing a short single-line reply**. The REPL now finishes without clearing when the turn printed visible text (`Clear(UntilNewLine)` wipes only the spinner tail after the reply). **Streamed multi-paragraph replies rendered glued** ("para1para2") — each chunk's paragraph separator was trimmed at the stream boundary; the markdown streamer now preserves separators via a held-separator so streamed output equals a single full render (no dangling blank line). **Markdown tables with CJK/fullwidth content misaligned** — width now counts display cells (CJK = 2), not chars. **`aris "prompt"` / `--print` ignored the executor model saved by `aris setup`** (REPL-only before) — a configured OpenAI/custom executor got the Anthropic default sent to its endpoint; the one-shot and REPL paths now share one resolver. **Esc** now actually closes the completion dropdown (it was recomputed right back). **`glob_search`** reports the total matched count when truncated (not the capped 100, which made the model think a 1000-match glob had 100 files). **`/model`'s custom menu** reads the effective env the executor uses, not stale on-disk config. Tests (CI mode): api 32 / runtime 205 / tools 67 / aris-cli 172 / commands 5, all green; +7 new; real-machine verified (short reply renders + "✔ Done"; paragraphs keep their blank lines). Codex MCP (gpt-5.5 xhigh): hunt → 3 review rounds (NO-GO → NO-GO → GO). Two latent-only candidates (Anthropic block-`index` routing, OpenAI multi-line SSE) deferred to a hardening pass.
>
> **v0.4.19** (2026-06-14) — **honesty / guardrails patch** (theme from a Codex fresh-eyes audit; no behavior change for healthy setups). **🔴 MCP protocol-version negotiation guard** — the stdio handshake requested `2025-03-26` but never read the version the server negotiated back (a parsed-but-dead field), so a server agreeing on a version ARIS can't speak was silently accepted and later `tools/list` / `tools/call` ran on an incompatible protocol with opaque failures. ARIS now validates the negotiated version against a supported set (`2025-11-25` / `2025-06-18` / `2025-03-26` / `2024-11-05` — stdio framing is identical across these) and, on an unsupported one, terminates the child + clears the slot + surfaces a clear per-server error (`aris doctor` shows it) — the "terminate when versions can't be agreed" behavior the MCP lifecycle spec requires. The *request* stays `2025-03-26` (proven against `codex mcp-server`), so healthy servers are unaffected — verified end-to-end: the real Codex MCP server still spawns + initializes + advertises its tools under the guard. **🧹 Papercuts**: the OpenAI-family subagent fail-loud message dropped its stale "lands in v0.4.18" marker (now version-agnostic + actionable, still credential-free); OpenAI upstream error bodies are now truncated (500 chars) + credential-redacted (`sk-…` keys and `Bearer …` tokens, via a substring scanner that catches the compact-JSON shape `{"api_key":"sk-…"}` a misconfigured proxy can reflect back) instead of splatted verbatim; the system-prompt hook-events summary now counts only the hooks the runtime actually executes (a `command` hook with a `command` string), matching the parser. Tests (CI mode): api 32 / runtime 204 / tools 67 / aris-cli 167 / commands 5, all green; live smoke confirms the real Codex MCP server still initializes under the guard. Reviewed by Codex MCP (gpt-5.5 xhigh): design GO → impl NO-GO (compact-secret miss + command-string strictness) → GO after fixes.
>
> **v0.4.18** (2026-06-14) — **default model → Claude Opus 4.8**, with corrected pricing and a safety net. The bump moves `DEFAULT_MODEL`, the `opus` alias, the model picker, `aris setup`, and the subagent default to `claude-opus-4-8` — with an **availability fallback**: if the account lacks 4.8 (the API returns `404 not_found_error`), ARIS auto-falls-back to `claude-opus-4-7` for the session, **rebuilds the system-prompt model identity so it stays coherent** (the model is never told it's 4.8 while served 4.7), warns once, and retries — for the main session (text + JSON) and subagents. It fires only on that precise 404 (never 400/rate-limit/auth), latches against loops, and the text path rebuilds from a pre-turn snapshot so a retry never double-appends the user message; accounts **with** 4.8 are byte-identical to a plain bump. **💰 Pricing corrected** (verified against Anthropic's published schedule; had been a 3–5× over-estimate): current **Opus 4.5–4.8 = `$5/$25`** (deprecated Opus 4/4.1 keep `$15/$75`, split by word-boundary so a future `opus-4-10` isn't mis-tiered); **Sonnet 4.x = `$3/$15`** (decoupled from the generic unknown-model fallback, which stays `$15/$75`); Haiku was already correct. **🧹 Backlog**: `aris setup` option 10 pins the Codex MCP reviewer to `model_reasoning_effort="xhigh"` (deterministic for new setups, independent of `~/.codex/config.toml`; idempotent merge never clobbers an existing entry); a startup + `aris doctor` **misconfig hint** ([#259](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/259)) for a silently-ignored/misplaced config (malformed JSON, or a stray `~/.aris/config.yaml` — stderr-only so `--print`/JSON stdout stays clean); the system-prompt hook summary now marks parsed-but-never-fired events **"PARSED ONLY … will NOT run"** instead of implying dead hooks run (full event expansion — actually firing `SessionStart`/`SessionEnd`/… — deferred to a separate issue). Tests (CI mode): api 32 / runtime 202 / tools 67 / aris-cli 166 / commands 5, all green; a live one-shot smoke returns `model=claude-opus-4-8` end-to-end. Reviewed by Codex MCP (gpt-5.5 xhigh) across the design + both implementation batches (design REWORK→GO, impl NO-GO→GO, batch-2 GO).
>
> **v0.4.17** (2026-06-13) — **the MCP release.** Before v0.4.17, `mcpServers` in `settings.json` parsed, showed in `aris doctor`, and did *nothing*; now ARIS spawns each configured stdio server, runs the MCP handshake, discovers tools, and advertises them as `mcp__<server>__<tool>` on **both** provider paths (Anthropic + OpenAI-family), with end-to-end dispatch, soft per-server degradation, and an approval gate for untrusted MCP tools (external processes the sandbox can't cover; `--allowedTools` now accepts `mcp__` names). **🆕 zero-API-key cross-model reviewer**: `aris setup` → **option 10 (Codex MCP, ChatGPT subscription, no API key)** writes an idempotent `mcpServers.codex` entry into the settings file the runtime actually reads (atomic write + backup, explicit consent before `trust: true`), with an optional API reviewer as **fallback** (`ARIS_REVIEWER_PROVIDER=codex-mcp` + `ARIS_REVIEWER_FALLBACK_PROVIDER`); `/setup` in-REPL rebuilds the system prompt + runtime so reviewer changes take effect without quitting. **🔴 Protocol fix the fakes couldn't catch**: real-machine e2e against `codex mcp-server` exposed that our stdio transport spoke LSP-style `Content-Length:` framing while the MCP spec (and codex) use **newline-delimited JSON-RPC** — every fake-server test passed because the fakes spoke the same wrong dialect; writes are now NDJSON, reads auto-detect both, and the spec-mandated `notifications/initialized` is sent after `initialize` (a select-based round-trip also closes the [#286](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/286) large-request deadlock). **Hooks**: object-style Claude Code hooks preserve `matcher` / `timeout` / `async` (anchored-regex matcher filtering; per-hook timeout, default 30 s kill = warning not deny). **Long tail**: `ARIS_DISABLE_KEYCHAIN` gate, Anthropic `stop_reason` clean-EOF symmetry (CL2), OpenAI tool-call `index`-missing merge-by-id (OE6), slash commands enter history. **Real-machine push-gate hardening** (the zero-key reviewer's first run): codex `codex/event` notification spam silenced by default (gated behind `ARIS_MCP_STDERR=inherit`), the system prompt now tells the model **not** to pass a `model` parameter to Codex (account default = gpt-5.5 + xhigh; arbitrary names are rejected by a ChatGPT account), and a Codex-MCP-primary-with-no-fallback `LlmReview` call returns a clear "use `mcp__codex__codex`" message instead of a misleading `OPENAI_API_KEY`/`gpt-5.5` error. Built with the v0.4.16 zero-regression methodology (24 new characterization tests; every deliberate flip annotated in-place). Tests (CI mode): runtime 199 / aris-cli 165 / tools 67 / api 30 / commands 5, all green. Reviewed phase-by-phase by Codex MCP (gpt-5.5 xhigh) across 17 rounds (7 NO-GOs all resolved). Subagent MCP routing (P8) + MCP `protocolVersion` bump + hook `async` execution deferred to v0.4.18.
>
> **v0.4.16** (2026-05-30) — REPL UX + provider hardening, shipped under a zero-regression discipline: 64 characterization ("golden") tests locked the *current* provider-routing / pricing / reviewer / subagent / REPL behavior first, then stayed green through every change. Closes [#274](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/274): command history now persists to `~/.config/aris/history` (0600) and reloads on startup, with an `ARIS_NO_HISTORY` kill-switch and a disk-only secret-skip (credential-looking lines stay in in-session history but never touch disk); bash-style **Ctrl+R** reverse incremental search (CJK display-width-aware single-line render; no existing key binding changed; no new dependency). Security: an OpenAI-family main session (Kimi / GLM / MiniMax / …) spawning a subagent previously **silently billed the user's Anthropic OAuth/Keychain credential** — it now fails loud with a clear, credential-free error; full OpenAI-family subagent routing is a cross-crate change deferred to v0.4.17. Groundwork (no behavior change): the 3 byte-identical word-boundary matchers consolidate into one canonical `runtime::word_match`; new pure `ProviderFamily` classifier (unwired). Tests (CI mode): runtime 164 / aris-cli 128 / tools 49 / commands 5, all green. Codex MCP (gpt-5.5 xhigh) reviewed each phase + a final integration pass.
>
> **v0.4.15** (2026-05-29) — OpenAI-compatible streaming robustness hotfix. Closes [#249](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/249): MiniMax (and other OpenAI-compatible providers / proxies) were effectively unusable because the clean-EOF completion check treated the `data: [DONE]` SSE sentinel as the *only* authoritative signal. A non-empty `choices[].finish_reason` is the Chat Completions spec's terminal-chunk marker; `[DONE]` is a transport convention some compatible providers never emit (MiniMax sends `finish_reason: "stop"` then closes without `[DONE]`). The clean-EOF decision is now a pure, unit-tested `stream_eof_action(...)` that completes on EITHER `[DONE]` OR a non-empty `finish_reason`; reads are NOT stopped early at finish_reason (a trailing `include_usage` usage-only chunk is still consumed), genuine truncation still hard-errors, and a pre-output proxy abort still restarts. Coupled fixes: **OE7** reads finish_reason before the `delta` guard (delta-less terminal choice); **OE2** flushes pending tool calls on any non-empty finish_reason; **OE4** surfaces a mid-stream error envelope as a hard error instead of silently dropping it; **OE3** tolerates `data:{...}` without the space after the colon. +5 unit tests (77→82) extract the previously-untested SSE completion logic into pure helpers. Anthropic SSE path untouched. Codex MCP (gpt-5.5 xhigh) 3 rounds (GO-WITH-NITS → GO-WITH-NITS → GO).
>
> **v0.4.14** (2026-05-25) — Security-hygiene release closing the top items from the v0.4.13 codex audit (gpt-5.5 xhigh, 6/10 NEEDS-REWORK verdict). **🔴 S9 (P0) system-prompt config redaction** — before v0.4.14, `render_config_section()` dumped the merged `settings.json` verbatim into the system prompt sent to the LLM provider, leaking `env`, `mcpServers.<name>.headers.Authorization` Bearer tokens, hook command env, signed-URL query params, and `apiKey` fields. New renderer whitelists top-level fields (`model`/`permissionMode`/`theme`/`outputStyle`/`permissions`/`sandbox` with recursive redaction inside), redacts sensitive keys (`apikey`/`token`/`secret`/`password`/`authorization`/`headers`/`env`/`_KEY`/`_SECRET`/`_TOKEN`), replaces MCP `command` with `<configured>` placeholder, reduces MCP `url` to strict `<scheme://host[:port]>` origin (scheme allow-list `http`/`https`/`ws`/`wss`, ASCII host, digit-only port, IPv6 brackets), and drops hook command strings entirely. Regression test exercises 9 distinct leak surfaces; URL parser has its own targeted test for 7 smuggling attempts including port-position secret injection (codex round-3 catch). **🟡 P9 (P1)**: DeepSeek `aris --help` now points at `aris setup` option 7 instead of an env-var path the resolver never honored. **🟡 M1/M2 (P1) doc**: `aris doctor` + README/README_CN gain experimental warning whenever `mcpServers.len() > 0` (full MCP tool dispatch lands v0.4.16). **🟢 C11 (P2) stream idle timeout** — both Anthropic `MessageStream` and the OpenAI SSE loop wrap `response.chunk().await` in `tokio::time::timeout` (env `ARIS_STREAM_IDLE_TIMEOUT_SECS`, default 120, clamp `[10, 1800]`, 0/negative disables); closes the "aris hangs forever with no output" symptom when an upstream HTTPS proxy holds a connection without keepalives. **Bundle**: 77 skills (+1 `/wiki-enrich` via late same-day sync to main `7e3ab67` which also picks up upstream `check_ready.sh` awk + grep-c null-match fix), 54 helpers. Codex MCP 6 rounds (NO-GO + 4 → GO-WITH-NITS + 3 → NO-GO + port smuggling → GO → release metadata GO → sync GO).
>
> **v0.4.13** (2026-05-25) — Residue-cleanup release closing every codex audit P1 carried since v0.4.10–v0.4.12, plus the long-tail regression tests. **🟡 v0.4.10 P1.D per-server MCP timeout** — `mcpServers.<name>.requestTimeoutSecs` override > `MCP_REQUEST_TIMEOUT_SECS` env > 300s default (clamped 1..=1800), so one Codex MCP agent can run 5 min while filesystem MCP errors in 5 s. **🟡 v0.4.10 known limitation closed** — `McpStdioProcess::request()` skips JSON-RPC notifications (id absent/null) and keeps reading until the correlated response. **🟢 meta_opt hook deploy via `aris init`** — `tools/meta_opt/{log_event,check_ready}.sh` bundle into the binary; `aris init` writes ARIS-namespaced **`aris-meta-opt-log-event.sh`** / **`aris-meta-opt-check-ready.sh`** to `~/.claude/hooks/` (codex round-1 #1: never clobbers user hooks); settings.json merge idempotent, backups hard-fail, final rewrite atomic via tempfile + rename. **🧪 9 v0.4.12 targeted regression tests** for sandbox.strictMode (3) + parse strictMode + provider_match pricing + has_word o-series + stream_options 400 + meaningful-content classification + premature-EOF retry truth table (codex round-1 #3 — `should_retry_on_premature_eof()` extracted to pure fn, 7-row test). **Bundle**: 76 skills, **54 helpers** (+2 meta_opt scripts vs v0.4.12). Codex 3 rounds (NO-GO + 3 → NO-GO + metadata → GO).
>
> **v0.4.12** (2026-05-22) — Bug-fix + small-feature release. **#238 `sandbox.strictMode`** opt-in config key; when set, `SandboxConfig::resolve_request()` ignores all five LLM-supplied overrides (`dangerouslyDisableSandbox`, `namespaceRestrictions`, `isolateNetwork`, `filesystemMode`, `allowedMounts`) — closes the gap where a tool call could silently bypass user sandbox policy. `aris doctor` adds a "Sandbox:" row; bash tool schema documents the strictMode semantics. **#232** `auto-review-loop-llm` updated from legacy `deepseek-chat` / `deepseek-reasoner` (deprecate 2026-07-24; reasoner rejects `tool_choice`) to `deepseek-v4-flash` / `deepseek-v4-pro`. **v0.4.10 audit P1 follow-ups**: P1.A Anthropic stream retry gates on `has_emitted_meaningful_content` (a stream that only sent `MessageStart` before EOF is retry-eligible); P1.B `supports_reasoning_effort` + reviewer mirror use word-boundary match so `openai/o3-mini` / `proxy:o4` route correctly; P1.C `stream_options.include_usage:true` proxy fallback retries once without on real 400 unknown-field errors; P2 pricing match precision via `provider_match()` so `qwen3.6-plus` / `kimi-k2.5` route correctly while `my-kimi-clone` does not. **Skills sync** (76 skills, 52 helpers): `/interview-cheatsheet` + `/render-html` newly bundled; `build.rs` `ALLOWED_EXTS` gains `html` for render-html templates; `EXCLUDED_SKILL_PREFIXES` → `starts_with("skills-codex")`. **CI fetch-depth: 0** + origin/main fetch so drift-test ancestor check runs. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) over 4 rounds.
>
> **v0.4.11** (2026-05-18) — Skills bundle refresh + sync infrastructure. The embedded skills set in the v0.4.10 binary had fallen behind main (~6 of 56 main `skills/` commits had been cherry-picked); v0.4.11 syncs the full set and ships sync infrastructure so the gap can't silently reopen. Bundle: 65→74 user-facing skills, 34→49 helper resources. 10 new skills bundled: `/citation-audit` (fourth-layer bibliography audit), `/experiment-queue` (SSH multi-seed job queue with OOM retry), `/kill-argument` (two-thread adversarial review for theory papers), `/resubmit-pipeline` (W5: text-only port to a new venue), `/paper-talk` (end-to-end conference talk pipeline), `/slides-polish` (per-page Codex layout review), `/overleaf-sync` (two-way Overleaf Git-bridge), `/gemini-search` + `/openalex` (broader literature sources), `/qzcli` (Qizhi GPU jobs). 46 existing SKILL.md refreshed — most critically the canonical resolver chain rollout (closes real user incident where `/research-wiki` was empty for a week from hardcoded `tools/research_wiki.py`), submission assurance gate + external verifier (`/paper-writing` Phase 6 now functions). tools/ goes 9→18: 9 baseline helpers refreshed (`research_wiki.py` 315→767 lines with canonical `ingest_paper` API), 9 new helpers (`extract_paper_style.py`, `figure_renderer.py`, `paper_illustration_image2.py`, `overleaf_{setup,audit}.sh`, `verify_wiki_coverage.sh`, `watchdog.py`, `experiment_queue/{build_manifest,queue_manager}.py`). New `tools/sync_main_skills.sh` automates main → bundle rsync with symlink pre-flight + codex-mirror prune + `SKILLS_SOURCE_COMMIT` pinning. 3 new CI drift tests in `crates/runtime/src/cache.rs` cover all 4 resolver layer patterns. Gemini MCP calls in `/research-lit` and `/gemini-search` now pass `model: 'auto-gemini-3'` (avoids silent downgrade to 2.5-pro on OAuth-personal capacity exhaustion). CLI runtime unchanged — codex-audit P1 follow-ups remain on v0.4.12 backlog. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) across 5 rounds (REQUEST CHANGES → APPROVE WITH NITS → NO-GO → GO → final GO).
>
> **v0.4.10** (2026-05-17) — Stream + MCP reliability + multi-provider pricing. C6 whole-stream restart in Anthropic `MessageStream` + OpenAI SSE loop on chunk decode failure / premature EOF (`ARIS_STREAM_RETRY`, default 2, clamp 0..=5, fires only when nothing emitted yet — closes [#228](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/228)-style "error decoding response body" loop). M3 MCP stdio gains 300s default `tokio::time::timeout` over send+read (override `MCP_REQUEST_TIMEOUT_SECS`, clamp 1..=1800); `response.id ↔ request.id` correlation; `ensure_server_ready()` `try_wait()` dead-process respawn; `kill().await` on all failure paths so the next call starts clean (closes [#151](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/151) / [#172](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/172) "Calling codex..." stalls). C8/P4 OpenAI streaming requests now send `stream_options.include_usage:true` + parse `cached_tokens`; Anthropic streaming merges `MessageStart.usage` (input/cache) with `MessageDelta.usage` (output). C9 multi-provider pricing registry (15+ models, OpenAI cache_read = input × 0.1 corrects 5× generic overstatement, DeepSeek cache_hit/cache_miss tiers, `has_word()` boundary matcher for `provider/<model>` slugs). 9 dead-code warnings cleared; `aris setup` help text synced with actual behaviour.
>
> **v0.4.9** (2026-05-17) — Closes Codex v0.4.7 audit residuals (L1 TLS double-stack, L3 reasoning_cache compaction misalign, L4 reasoning replay unbounded). 2 new skills bundled (`/figure-spec` + `/paper-illustration-image2` with `scripts/` subdirs, new Layer 0b = `$ARIS_CACHE_DIR/skills/<name>/scripts/`); `research_wiki.py` promoted to shared `tools/` (9+ callers); 5 more SKILL.md migrated to fallback chain.
>
> **v0.4.8** (2026-05-17) — Skill helper subsystem rewrite. Bundled helpers extract to `~/.config/aris/cache/<version>/` at startup; every Skill invocation surfaces `helperReport` JSON + 4-layer resolver preamble; `/skills export` copies helpers; new `integration-contract.md` with 6 failure policies; 8 shared helpers (arxiv/deepxiv/exa/S2/openalex/save_trace/verify_papers/verify_paper_audits) bundled; `/research-lit` + `/deepxiv` migrated. Plus 4 bug fixes: gpt-5.5+tools 400 on OpenAI; Custom reviewer reset; missing `signature` field ([#228](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/228)); `--version` Build date hardcoded.
>
> **v0.4.7** (2026-05-16) — DashScope Coding Plan 405 fixed ([#159](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/159)) via `native-tls` switch ([#225](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/225)); `reasoning_content` replay for all reasoning models (OpenAI o1/o3/o4 / DeepSeek-R1 etc.), not just Kimi ([#226](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/226)); 600+ lines dead code cleanup + `rustyline` dep removed + "Claw Code" → "ARIS-Code" rebrand.
>
> **v0.4.6** (2026-05-14) — 🚨 Two long-standing silent bugs fixed: `PermissionMode::Prompt` silently allowed every tool (derived-`Ord` bug); system prompt hardcoded `current_date = "2026-03-31"` made models reject post-cutoff data as future/prompt-injection. Plus Custom OpenAI-compatible provider (`/setup` option 11) with dynamic `/models` discovery ([@Anduin9527](https://github.com/Anduin9527) [#221](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/221) + [#222](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/222)).
>
> **v0.4.5** (2026-05-13) — First-class reasoning-model support: thinking content blocks end-to-end (fixes [#161](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/161)) + `reasoning_effort='xhigh'` for GPT-5.5 / o1 / o3 / o4 / DeepSeek-thinking. DeepSeek V4 Pro + Xiaomi MiMo + Qwen 3.6 + Doubao in `/setup` (options 7-10). Object-style hooks parser. Default model bumped to Claude Opus 4.7 + GPT-5.5. REPL input hardening (multi-line wrap / Cmd+V paste / CJK boundary). GitHub Actions CI. Credits: [@GO-player-hhy](https://github.com/GO-player-hhy) ([#186](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/186)), [@Jxy-yxJ](https://github.com/Jxy-yxJ) ([#171](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/171)), [@GetIT-Sunday](https://github.com/GetIT-Sunday) ([#216](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/216) partial).
>
> </details>
>
> <details><summary>Older versions</summary>
>
> **v0.4.4** (2026-04-20) — **Setup UX + reviewer routing fixes** (resolves [#158](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/158), [#162](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/162)) | `/setup` no longer forces Bearer for Anthropic + custom URL | Provider-aware proxy URL hints | Stale state no longer leaks across provider switches | LlmReview smart fallback
>
> **v0.4.3** (2026-04-17) — **Third-party Anthropic-compat proxy support** (Bedrock etc.) | Skip beta flags that proxies reject | Propagate custom base URL for `anthropic` provider | Credit [@screw-44](https://github.com/screw-44)
>
> **v0.4.2** (2026-04-17) — **Auto-compaction corruption fix** | Compaction summary preserved on OpenAI-compat executors | Shell-provided API keys no longer erased on launch
>
> **v0.4.1** (2026-04-15) — **Plan mode** (`/plan`) | Cooperative Ctrl+C interrupt | Auto-retry (429/5xx/network) | **Research Wiki** 📚 (persistent knowledge base) | **Self-Evolution** 🧬 (`/meta-optimize`) | Local models (LM Studio/Ollama) | 62 skills synced
>
> **v0.3.11** (2026-04-13) — Reviewer Anthropic-compatible mode (Claude via proxy)
>
> **v0.3.9** (2026-04-11) — Proxy/custom base URL (CCSwitch) | Local models (LM Studio/Ollama) | Windows (experimental)
>
> **v0.3.5** (2026-04-08) — **Research Wiki** (persistent papers/ideas/experiments/claims + relationship graph) | **Meta-Optimize** self-evolution (analyze logs → propose SKILL.md patches)
>
> **v0.3.0** (2026-04-03) — Multi-file memory index | Rich task system (TodoWrite) | `/plan` | Security hardening
>
> **v0.2.2** (2026-04-03) — `/plan` step-by-step planning | `/tasks` persistent tracking
>
> **v0.2.1** (2026-04-03) — Persistent Memory | Kimi K2.5 multi-turn fix | CJK cursor fix
>
> **v0.2.0** (2026-04-02) — Open source | Kimi + MiniMax + GLM support | Smart LlmReview routing | CI/CD
>
> **v0.1.0** (2026-04-02) — Initial release | Multi-executor & reviewer | 42 bundled skills
>
> </details>
</details>
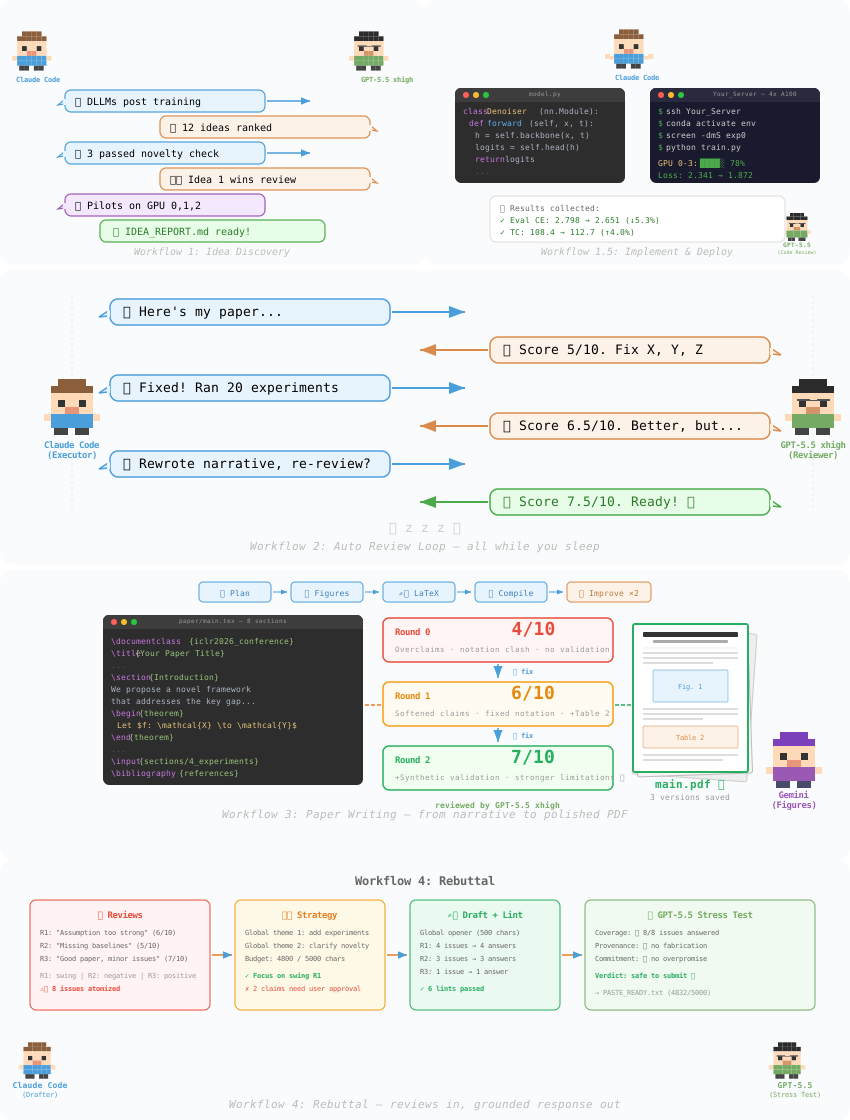
[中文版 README](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/README_CN.md) | English
> 🌙 **Let Claude Code do research while you sleep.** Wake up to find your paper scored, weaknesses identified, experiments run, and narrative rewritten — autonomously.
>
> 🪶 **Radically lightweight — no infrastructure, zero lock-in.** The entire skill layer is plain Markdown files. No framework to learn, no database to maintain, no Docker to configure, no daemon to babysit. Every skill is a single `SKILL.md` readable by any LLM — swap Claude Code for [Codex CLI](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/skills/skills-codex/), [OpenClaw](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/OPENCLAW_ADAPTATION.md), [Cursor](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/CURSOR_ADAPTATION.md), [Trae](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/TRAE_ARIS_RUNBOOK_EN.md), [Antigravity](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/ANTIGRAVITY_ADAPTATION.md), [Copilot CLI](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/docs/COPILOT_CLI_ADAPTATION.md), Windsurf, or your own agent and the workflows still work. Fork it, rewrite it, adapt it to your stack.
> 💭 **Why not self-play with a single model?** Using Claude Code subagents or agent teams for both execution and review is technically possible, but tends to fall into **local minima** — the same model reviewing its own patterns creates blind spots.
>
> *Think of it like adversarial vs. stochastic bandits: a single model self-reviewing is the stochastic case (predictable reward noise), while cross-model review is adversarial (the reviewer actively probes weaknesses the executor didn't anticipate) — and adversarial bandits are fundamentally harder to game.*
>
> 💭 **Why two models, not more?** Two is the minimum needed to break self-play blind spots, and 2-player games converge to Nash equilibrium far more efficiently than n-player ones. Adding more reviewers increases API cost and coordination overhead with diminishing returns — the biggest gain is going from 1→2, not 2→4.
>
> Claude Code's strength is fast, fluid execution; Codex (GPT-6-Astra xhigh) is slower but more deliberate and rigorous in critique. These complementary styles — **speed × rigor** — produce better outcomes than either model talking to itself.
>
> 🧿 **Want the strongest possible reviewer?** Add `— reviewer: oracle-pro` to any skill to route reviews through **GPT-5.5 Pro** via [Oracle MCP](https://github.com/steipete/oracle). Pro-level reasoning for proof verification, experiment auditing, and final stress tests. Works with API key or free browser mode. [Setup →](#-optional-gpt-54-pro-via-oracle)
<a id="contents"></a>
## Contents
1. [More Than Just a Prompt](#more-than-just-a-prompt)
2. [What's New](#whats-new) · changelog
3. [Quick Start](#quick-start) · install + first run
4. [Features](#features)
5. [Score Progression (Real Run)](#score-progression)
6. [Community Showcase — Papers Built with ARIS](#community-showcase)
7. [Awesome Community Skills & Extensions](#awesome-community-skills)
8. [Workflows](#workflows) · 13 named pipelines (W1 / W1.5 / W2 / W3 / W4 / W5 / W6 / Wiki / WM + Effort / Assurance / Oracle)
9. [Setup](#setup) · prerequisites / install / update / usage / [GPU server config](#gpu-server-setup)
10. [Customization](#customization) · per-skill config knobs
11. [Alternative Model Combinations](#alternative-model-combinations) · GLM / MiniMax / Kimi / etc.
12. [Community](#community)
13. [Citation](#citation)
14. [Star History](#star-history)
15. [Acknowledgements](#acknowledgements)
16. [License](#license)
---
<a id="more-than-just-a-prompt"></a>
## 1. 🎯 More Than Just a Prompt
> These are full pipelines — you can also use each workflow independently. Already have an idea? Skip to Workflow 1.5. Have results? Jump to Workflow 3. Got reviews? Jump to Workflow 4. Want persistent memory? Enable [Research Wiki](#-research-wiki--persistent-research-memory). See [Quick Start](#quick-start) for all commands and [Workflows](#workflows) for the full breakdown.
<a id="how-to-run"></a>
**Basic mode** — give ARIS a research direction, it handles everything:
```
/research-pipeline "factorized gap in discrete diffusion LMs"
```
**🔥 Targeted mode** — got a paper you want to improve? Give ARIS the paper + the code:
```
/research-pipeline "improve method X" — ref paper: https://arxiv.org/abs/2406.04329, base repo: https://github.com/org/project
```
ARIS reads the paper → finds its weaknesses → clones the codebase → generates ideas that specifically fix *those* weaknesses with *that* code → runs experiments → writes your paper. Like telling a research assistant: *"read this paper, use this repo, find what's missing, and fix it."*
> Mix and match: `ref paper` only = "what can be improved?", `base repo` only = "what can I build with this code?", both = "improve *this* paper using *this* code."
**🛠️ Build a feature** — already know what to build?
```
/research-implement-feature "add KV-cache reuse to the decoder" — base repo: https://github.com/org/project
```
Spine first, then one feature at a time, each with a runnable check. Every choice the request left open is written to an assumption ledger before the code that depends on it, and a different model family then reads the raw diff for the ones that went undeclared. It reports "the checks passed", never "the method works". Contributed by [@heroarmor](https://github.com/heroarmor).
**🔥 Rebuttal mode** — reviews just dropped? Don't panic. ARIS reads every concern, builds a strategy, and drafts a rebuttal that's grounded, structured, and under the character limit:
```
/rebuttal "paper/ + reviews" — venue: ICML, character limit: 5000
```
Three safety gates — rebuttal will NOT finalize if any fails:
- 🔒 **No fabrication** — every claim maps to paper/review/user-confirmed result
- 🔒 **No overpromise** — every promise is user-approved
- 🔒 **Full coverage** — every reviewer concern is tracked
Two outputs: `PASTE_READY.txt` (exact char count, paste to venue) + `REBUTTAL_DRAFT_rich.md` (extended version for manual editing).
<details>
<summary><b>Show rebuttal parameters</b> — venue, character limit (required), quick mode, auto experiment, stress test rounds, followup rounds</summary>
| Parameter | Default | What it does |
|-----------|---------|-------------|
| `venue` | `ICML` | Target venue (ICML/NeurIPS/ICLR/CVPR/ACL/AAAI/ACM) |
| `character limit` | — | **Required.** Hard character limit for rebuttal text |
| `quick mode` | `false` | Stop after parsing + strategy (Phase 0-3). See what reviewers want before drafting |
| `auto experiment` | `false` | Auto-run supplementary experiments via `/experiment-bridge` when reviewers ask for new evidence |
| `max stress test rounds` | `1` | How many times GPT-6-Astra xhigh stress-tests the draft |
| `max followup rounds` | `3` | Per-reviewer follow-up round limit |
</details>
**After acceptance** — your paper is in, now prepare the presentation:
```
/paper-slides "paper/" # → Beamer PDF + PPTX + speaker notes + Q&A prep
/paper-poster-html "paper/" # → measurement-gated HTML/CSS poster → print-ready PDF
```
> *💡 From idea to paper to podium — one toolchain. 🌱*
<a id="whats-new"></a>
## 2. 📢 What's New
> ⚠️ Any entry that touches skills: `bash tools/smart_update.sh --apply` pulls it.
- **2026-10-05** — 🔌 **New [Grok](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/mcp-servers/grok-exec/README.md) and [Gemini / Antigravity](https://github.com/wanshuiyin/auto-claude-code-research-in-sleep/blob/HEAD/mcp-servers/antigravity-exec/README.md) MCP bridges** — use your existing CLI login to read files and resume conversations from Claude Code or Codex. ([#454](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/454))
- **2026-09-28** —  📚 **Real papers stop being reported as hallucinated citations** ([#445](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/445), [#447](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/447), [#450](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/450); thanks [@ilya-pershin](https://github.com/ilya-pershin) and [@AfonsoZhang](https://github.com/AfonsoZhang)). arXiv sometimes refuses Python's HTTP client with a 406 for minutes while `curl` gets through; `verify_papers.py` read that refusal as "paper not found" and one user saw a 47% hallucination rate on 38 real papers. A 406 now goes through `curl`, and a refusal (406 / 401 / 403) is `verify_pending`, never `unverified`. Set `SEMANTIC_SCHOLAR_API_KEY` and title checks use it. Seen a suspicious hallucination rate recently? Re-run with `--no-cache` once. Also in this round: five skills can now actually invoke the sub-skills their text tells them to ([#440](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/440), [@Jeremy-xuan](https://github.com/Jeremy-xuan)); concurrent watchdog registrations no longer overwrite each other ([#443](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/443), [@hiro-nikaitou](https://github.com/hiro-nikaitou)); `xhigh` is described as the regular reviewer tier it is ([#442](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/442), [@dreamworld2023](https://github.com/dreamworld2023)).
- **2026-09-16** —  🧩 **ARIS is a Claude Code plugin now** ([#437](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/437), thanks [@white-drizzle](https://github.com/white-drizzle)). `claude plugin marketplace add wanshuiyin/Auto-claude-code-research-in-sleep` → `claude plugin install aris@aris` → `/aris:setup` once → restart. Setup registers the Codex reviewer bridge that ships inside the plugin, so the reviewer works on codex-cli 0.154+ out of the box. Plugin skills are typed with the prefix (`/aris:idea-discovery`); they call each other by short name internally. Codex CLI reads the same repo as a plugin too (`codex plugin marketplace add …` → `codex plugin add aris@aris`) and gets the Codex-native mirror. Cursor, Trae and DeepSeek Harness keep their own routes.
- **2026-09-10** — ![FIX](https://img.shields.io/badge/FIX-2ea44f?style=flat-squar