\n Cross-platform semantic memory for AI coding agents.\n
\n\n
\n \n \n \n \n \n \n \n \n \n \n \n \n \n
\n\n
\n \n
\n\n## 📰 What's New\n\n- **Optional Jev reranking** — rerank memory search results with Jev through the TypeSafe API, with no local model download. See [configuration](docs/home/configuration.md#optional-remote-reranking) and the [Chinese/English evaluation](evaluation/reranking-evaluation.md).\n\n- **DeepSeek Harness support** — MemSearch now brings automatic capture, pre-step memory injection, native skill-based recall, background maintenance, and a read-only memory browser to [DeepSeek Harness (DSH)](https://zilliztech.github.io/memsearch/platforms/dsh/).\n- **Skills from memory** — MemSearch now distills the workflows you repeat into reusable, installable agent skills (a third \"procedural memory\" layer) and keeps them up to date in the background. See [Skills from Memory](#skills-from-memory).\n- **Advanced memory maintenance** — optional background tasks keep durable `PROJECT.md` and `USER.md` notes current across sessions. See [Advanced Memory Maintenance](#advanced-memory-maintenance).\n\n---\n\n### Why memsearch?\n\n- 🌐 **All Platforms, One Memory** — memories flow across [Claude Code](plugins/claude-code/README.md), [Codex](plugins/codex/README.md), [DeepSeek Harness](plugins/dsh/README.md), [OpenClaw](plugins/openclaw/README.md), and [OpenCode](plugins/opencode/README.md). A conversation in one agent becomes searchable context in all others — no extra setup\n- 👥 **For Agent Users**, install a plugin and get persistent memory with zero effort; **for Agent Developers**, use the full [CLI](https://zilliztech.github.io/memsearch/cli/) and [Python API](https://zilliztech.github.io/memsearch/python-api/) to build memory and harness engineering into your own agents\n- 📄 **Markdown is the source of truth** — inspired by [OpenClaw](https://github.com/openclaw/openclaw). Your memories are just `.md` files — human-readable, editable, version-controllable. Milvus is a \"shadow index\": a derived, rebuildable cache\n- 🔍 **Progressive retrieval, hybrid search, smart dedup, live sync** — 3-layer recall (search → expand → transcript); dense vector + BM25 sparse + RRF reranking; SHA-256 content hashing skips unchanged content; file watcher auto-indexes in real time\n\n---\n\n## 🧑💻 For Agent Users\n\nPick your platform, install the plugin, and you're done. Each plugin captures conversations automatically and provides semantic recall with zero configuration.\n\n\n
For Claude Code Users
\n\n```bash\n# Install\n/plugin marketplace add zilliztech/memsearch\n/plugin install memsearch\n# Restart Claude Code to activate the plugin\n```\n\nAfter restarting, just chat with Claude Code as usual. The plugin captures every conversation turn automatically.\n\n**Verify it's working** — after a few conversations, check your memory files:\n\n```bash\nls .memsearch/memory/ # you should see daily .md files\ncat .memsearch/memory/$(date +%Y-%m-%d).md\n```\n\n**Recall memories** — two ways to trigger:\n\n```\n/memory-recall what did we discuss about Redis?\n```\nOr just ask naturally — Claude auto-invokes the skill when it senses the question needs history:\n```\nWe discussed Redis caching before, what was the TTL we chose?\n```\n\n> 📖 [Claude Code Plugin docs](https://zilliztech.github.io/memsearch/platforms/claude-code/) · [Troubleshooting](https://zilliztech.github.io/memsearch/platforms/claude-code/troubleshooting/)\n\n\n\n\n
For Codex Users
\n\n```bash\n# Install\ngit clone --depth 1 https://github.com/zilliztech/memsearch.git\nbash memsearch/plugins/codex/scripts/install.sh\ncodex --yolo # needed for ONNX model network access\n```\n\nAfter installing, chat as usual. Hooks capture and summarize each turn.\n\n**Verify it's working:**\n\n```bash\nls .memsearch/memory/\n```\n\n**Recall memories** — use the skill:\n\n```\n$memory-recall what did we discuss about deployment?\n```\n\n> 📖 [Codex Plugin docs](https://zilliztech.github.io/memsearch/platforms/codex/)\n\n\n\n\n
For DeepSeek Harness Users
\n\n```bash\n# Install the published plugin into your DSH profile\nuv tool install \"memsearch[onnx]\"\ndsh plugin --profile web add @zilliz/memsearch-dsh\n# Restart that DSH profile, or start a new session\n```\n\nAfter installing, use DSH normally. Completed turns are captured automatically, and relevant memories are injected before the first model step only when they are useful.\n\n**Verify it's working:**\n\n```bash\nls .memsearch/memory/\n```\n\n**Recall memories** — ask naturally or tell DSH to use the registered `memory-recall` skill:\n\n```\nUse memory-recall to find what we decided about the deployment architecture.\n```\n\nThe web profile also adds a compact MemSearch dock where you can review skill candidates and browse supported files under `.memsearch/` without editing them.\n\n> 📖 [DeepSeek Harness Plugin docs](https://zilliztech.github.io/memsearch/platforms/dsh/)\n\n\n\n\n
For OpenClaw Users
\n\n```bash\n# Install from ClawHub\nopenclaw plugins install --force clawhub:memsearch\nopenclaw config set plugins.entries.memsearch.hooks.allowConversationAccess true\nopenclaw config set plugins.entries.memsearch.hooks.allowPromptInjection true\nopenclaw gateway restart\n```\n\nAfter installing, chat in TUI as usual. The plugin captures each turn automatically.\n\n**Verify it's working** — memory files are stored in your agent's workspace:\n\n```bash\n# For the main agent:\nls ~/.openclaw/workspace/.memsearch/memory/\n# For other agents (e.g. work):\nls ~/.openclaw/workspace-work/.memsearch/memory/\n```\n\n**Recall memories** — two ways to trigger:\n\n```\n/memory-recall what was the batch size limit we set?\n```\nOr just ask naturally — the LLM auto-invokes memory tools when it senses the question needs history:\n```\nWe discussed batch size limits before, what did we decide?\n```\n\n> 📖 [OpenClaw Plugin docs](https://zilliztech.github.io/memsearch/platforms/openclaw/) · [Browse on ClawHub](https://clawhub.ai/plugins/memsearch)\n\n\n\n\n
For OpenCode Users
\n\n```json\n// In ~/.config/opencode/opencode.json\n{ \"plugin\": [\"@zilliz/memsearch-opencode\"] }\n```\n\nAfter installing, chat in TUI as usual. A background daemon captures conversations.\n\n**Verify it's working:**\n\n```bash\nls .memsearch/memory/ # daily .md files appear after a few conversations\n```\n\n**Recall memories** — two ways to trigger:\n\n```\n/memory-recall what did we discuss about authentication?\n```\nOr just ask naturally — the LLM auto-invokes memory tools when it senses the question needs history:\n```\nWe discussed the authentication flow before, what was the approach?\n```\n\n> 📖 [OpenCode Plugin docs](https://zilliztech.github.io/memsearch/platforms/opencode/)\n\n\n\n### ⚙️ Configuration (all platforms)\n\nAll plugins share the same memsearch backend. Configure once, works everywhere.\n\n#### Embedding\n\nDefaults to **ONNX bge-m3** — runs locally on CPU, no API key, no cost. On first launch the model (~558 MB) is downloaded from HuggingFace Hub.\n\n```bash\nmemsearch config set embedding.provider onnx # default — local, free\nmemsearch config set embedding.provider openai # needs OPENAI_API_KEY\nmemsearch config set embedding.provider ollama # local, any model\n```\n\n> All providers and models: [Configuration — Embedding Provider](https://zilliztech.github.io/memsearch/home/configuration/#embedding-provider)\n\n#### Milvus Backend\n\nJust change `milvus_uri` (and optionally `milvus_token`) to switch between deployment modes:\n\n**Milvus Lite** (default) — zero config, single file. Great for getting started:\n\n```bash\n# Works out of the box, no setup needed\nmemsearch config get milvus.uri # → ~/.memsearch/milvus.db\n```\n\n⭐ **Zilliz Cloud** (recommended) — fully managed, [free tier available](https://cloud.zilliz.com/signup?utm_source=github&utm_medium=referral&utm_campaign=memsearch-readme) — [sign up](https://cloud.zilliz.com/signup?utm_source=github&utm_medium=referral&utm_campaign=memsearch-readme) 👇:\n\n```bash\nmemsearch config set milvus.uri \"https://in03-xxx.api.gcp-us-west1.zillizcloud.com\"\nmemsearch config set milvus.token \"your-api-key\"\n```\n\n\n⭐ Sign up for a free Zilliz Cloud cluster\n\nYou can [sign up](https://cloud.zilliz.com/signup?utm_source=github&utm_medium=referral&utm_campaign=memsearch-readme) on Zilliz Cloud to get a free cluster and API key.\n\n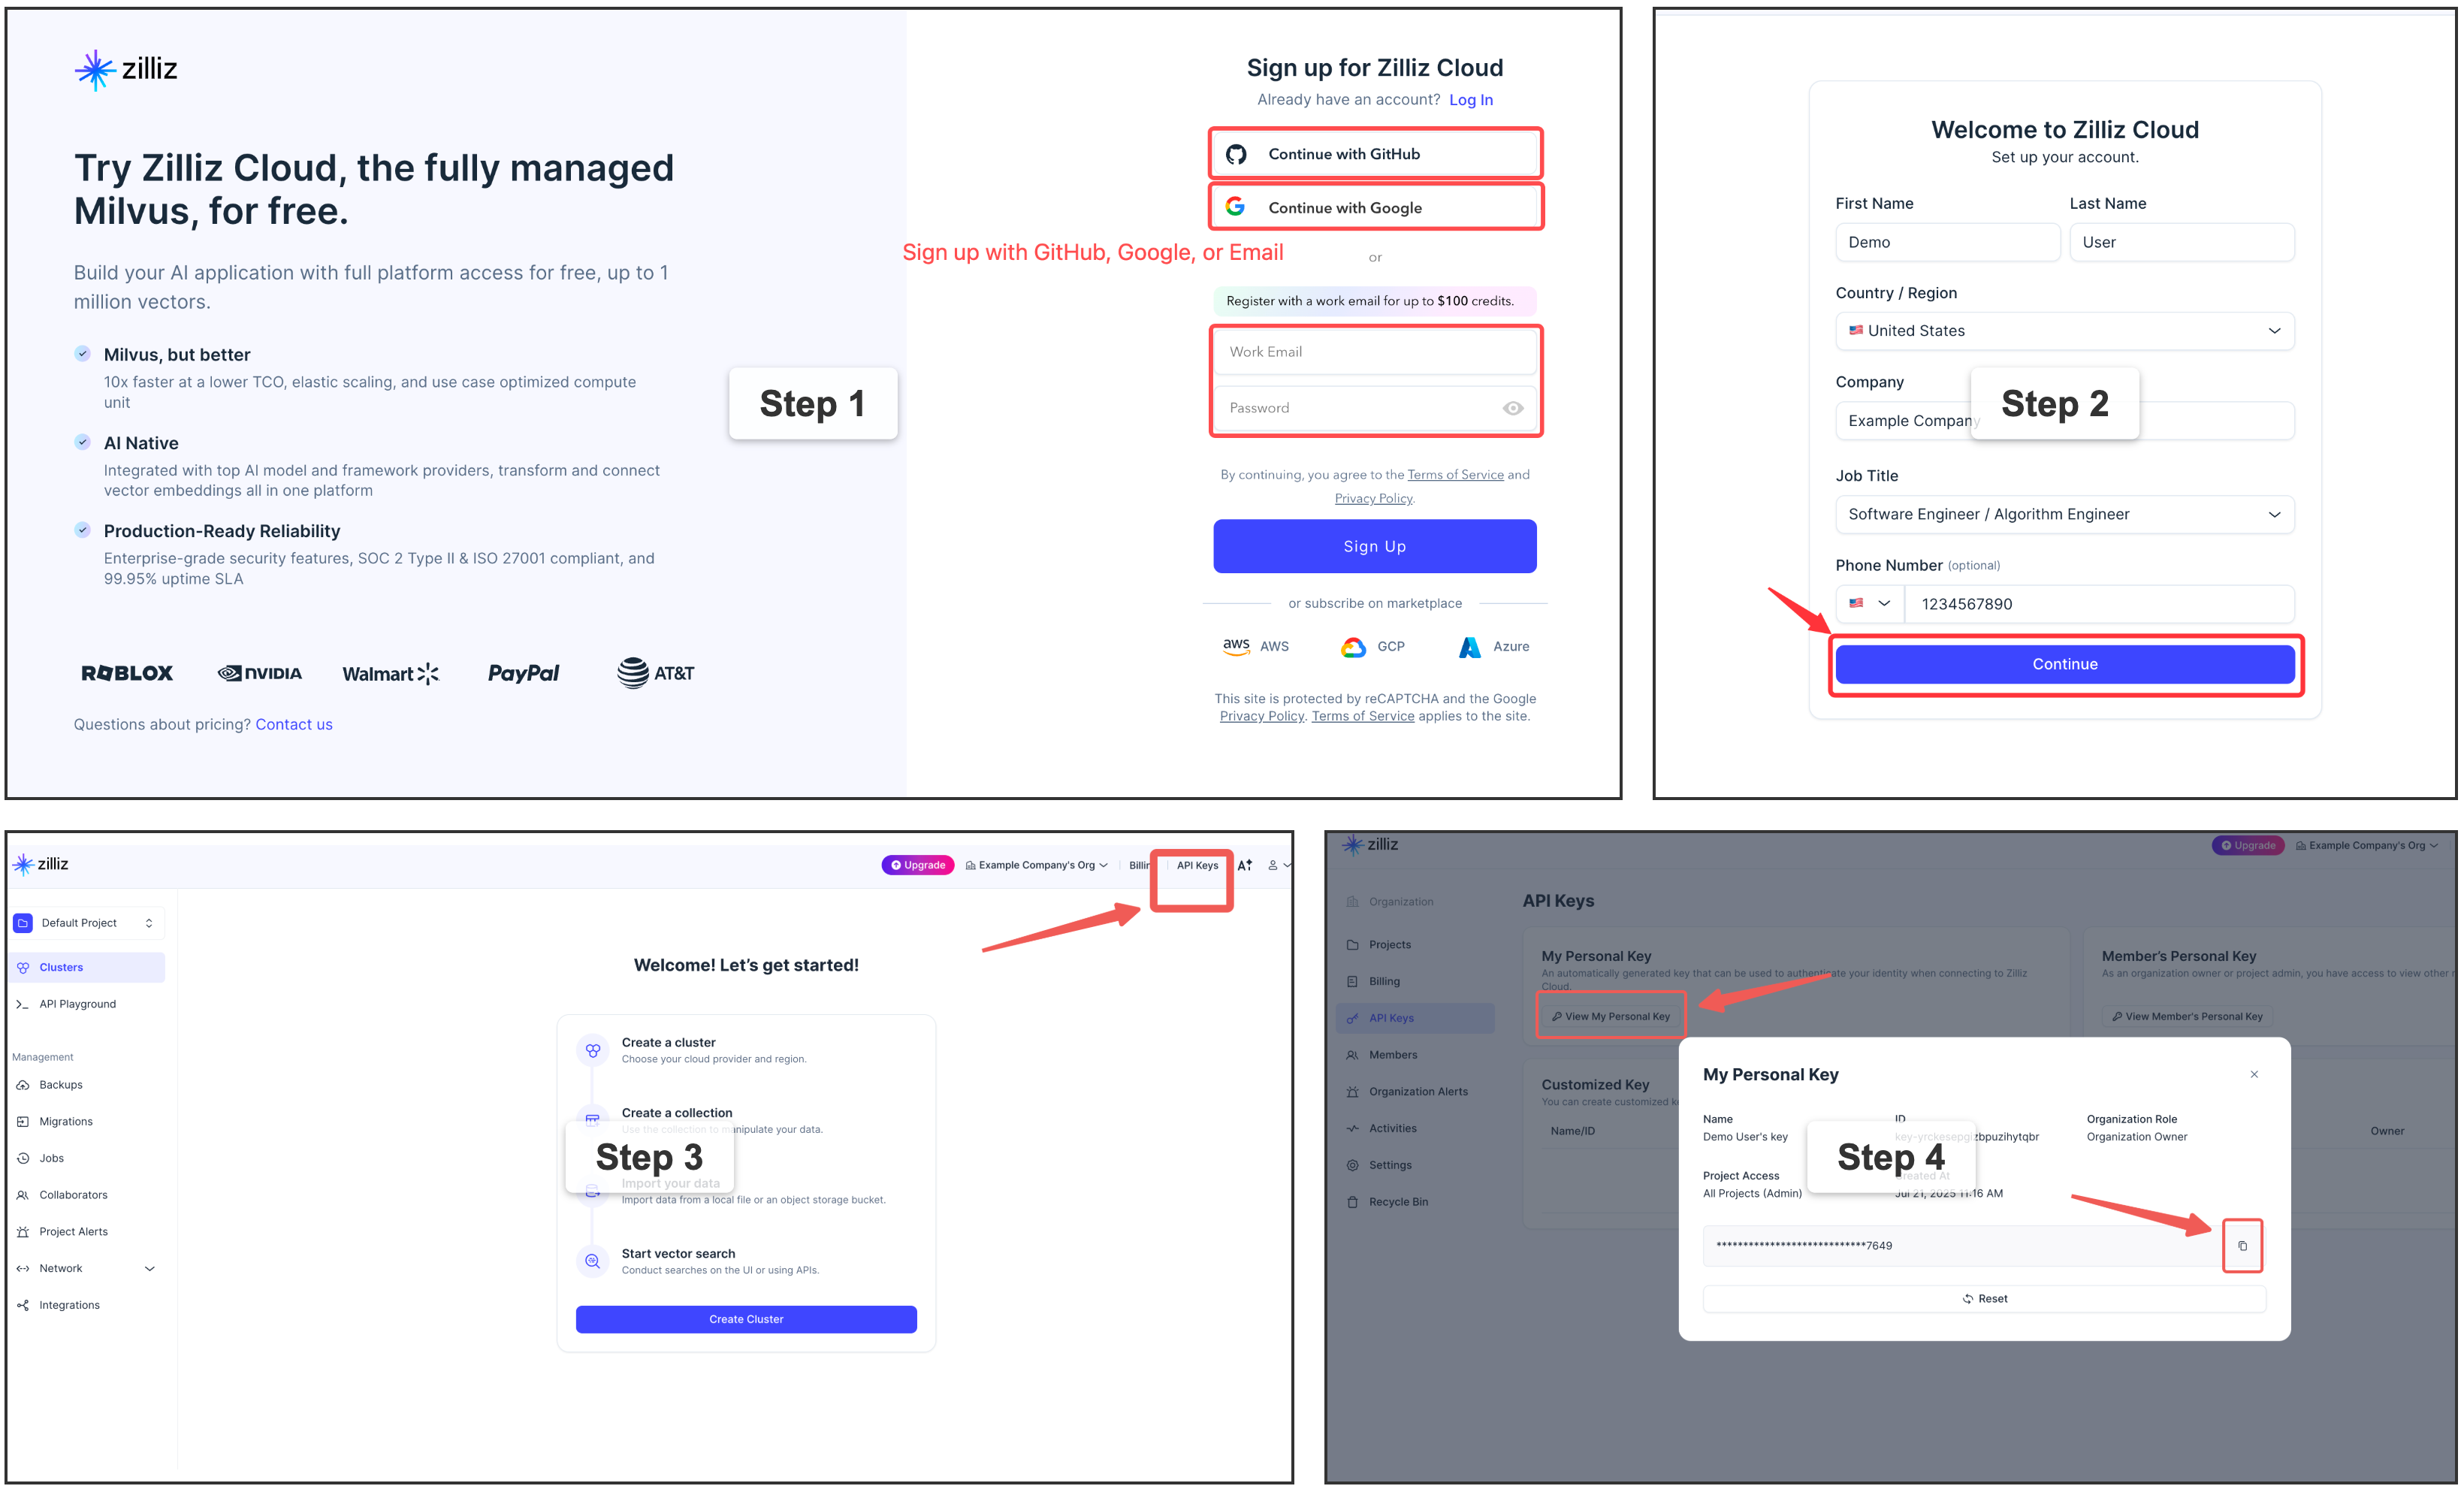\n\n\n\n\nSelf-hosted Milvus Server (Docker) — for advanced users\n\nFor multi-user or team environments with a dedicated Milvus instance. Requires Docker. See the [official installation guide](https://milvus.io/docs/install_standalone-docker-compose.md).\n\n```bash\nmemsearch config set milvus.uri http://localhost:19530\n```\n\n\n\n> 📖 Full configuration guide: [Configuration](https://zilliztech.github.io/memsearch/home/configuration/) · [Platform comparison](https://zilliztech.github.io/memsearch/platforms/)\n\n#### Capture Summarization Routing\n\nEach plugin keeps its native capture summarizer unless you override it explicitly:\n\n```bash\nmemsearch config set plugins.codex.summarize.model gpt-5.1-codex-mini\nmemsearch config set plugins.opencode.summarize.model anthropic/claude-haiku\n```\n\nAdvanced users can route plugin summarization through a memsearch-managed API provider:\n\n```bash\nmemsearch config set llm.providers.openai.type openai\nmemsearch config set llm.providers.openai.model gpt-5-mini\nmemsearch config set llm.providers.openai.api_key env:OPENAI_API_KEY\nmemsearch config set plugins.codex.summarize.provider openai\n```\n\nLeave `plugins..summarize.provider` empty to preserve the platform's default behavior. Claude Code, Codex, OpenClaw, and OpenCode also accept `native`; DSH selects its headless-agent backend when the provider is unset. Plugin-specific summarize settings do not fall back to `llm.model`.\n\nYou can also disable automatic capture globally for a platform while keeping the plugin installed:\n\n```bash\nmemsearch config set plugins.codex.summarize.enabled false\n```\n\n#### Advanced Memory Maintenance\n\nYour agent can keep two higher-level notes current in the background: **`PROJECT.md`** — durable project state (active threads, decisions, risks, next steps) — and **`USER.md`** — your reusable preferences, working style, and recurring goals. They refresh after a session only when the journals changed and a minimum interval has passed, and they are **off by default**.\n\nTurn them on by asking your agent — *\"enable MemSearch's PROJECT.md and USER.md maintenance\"* — and it configures them through the `memory-config` skill, which can also choose the model/provider, the interval, and custom prompts, or diagnose the current setup. Prefer editing files? The settings live under `[plugins..project_review]` and `[plugins..user_profile]` in your MemSearch config (both read `.memsearch/memory` and write `.memsearch/PROJECT.md` / `.memsearch/USER.md` by default).\n\nIf a background maintenance task seems silent, check `.memsearch/.maintenance-state.json` or ask the `memory-config` skill to inspect it; failed runs record `last_error` and retry on the next due run because failed input digests are not marked successful.\n\n#### Skills from Memory\n\nBeyond the episodic journals and the semantic `PROJECT.md` / `USER.md` notes, MemSearch grows a third memory layer — **procedural memory**: your agent turns the workflows you repeat into reusable, installable skills. You drive it entirely through your agent, in natural language — nothing to memorize:\n\n- *\"Make a skill out of what we just did.\"* — the agent drafts a skill from the session (reading the original transcript so the steps are exact, not guessed), saves it as a candidate, and offers to install it.\n- *\"What skill candidates do I have? Install the deploy one.\"* — the agent lists candidates and installs the one you pick into its own skill directory, where it becomes a real `/`-command.\n\n
\n \n
\n\nUnder the hood, candidates live in a git-tracked `.memsearch/skill-candidates/` store — diffable and revertible, and **inert until you install one** (that step is always yours). An optional background pass can also mine recurring workflows from your history on its own. Distilled skills follow the [Agent Skills](https://agentskills.io) open standard, so one capture is portable across Claude Code, Codex, DSH, OpenClaw, OpenCode, and other compatible agents.\n\n**Turning it on is also just a sentence:** ask your agent *\"enable MemSearch skill distillation\"* (or *\"make it more eager\"*) and it configures things through the `memory-config` skill — it's off by default. Prefer editing files? The same settings live under `[plugins..memory_to_skill]` in your MemSearch config. Full guide: **[Skills from Memory](https://zilliztech.github.io/memsearch/home/skills-from-memory/)**.\n\n### What can you use it for?\n\n- **Resume debugging threads** — ask how a similar Redis, Docker, database, or deployment issue was fixed last time.\n- **Recover decision rationale** — find why the project chose one architecture, library, migration path, or API design over another.\n- **Trace feature history** — understand how a feature evolved across sessions, including the files changed and tradeoffs discussed.\n- **Do code archaeology** — ask when and why a module, config, or workflow was changed before touching it again.\n- **Find the right session to resume** — ask which previous conversation covered a topic, recover the relevant context, and continue from there.\n- **Carry context across agents** — keep Claude Code, Codex, DeepSeek Harness, OpenClaw, and OpenCode working from the same project memory.\n\n---\n\n## 🛠️ For Agent Developers\n\nBeyond ready-to-use plugins, memsearch provides a complete **CLI and Python API** for building memory into your own agents. Whether you're adding persistent context to a custom agent, building a memory-augmented RAG pipeline, or doing harness engineering — the same core engine that powers the plugins is available as a library.\n\n### 🏗️ Architecture Overview\n\n```\n┌──────────────────────────────────────────────────────────────┐\n│ 🧑💻 For Agent Users (Plugins) │\n│ Claude Code · Codex · DSH · OpenClaw · OpenCode · Your App │\n│ │ │\n├────────────────────────────┬─────────────────────────────────┤\n│ 🛠️ For Agent Developers │ Build your own with ↓ │\n│ ┌─────────────────────────┴──────────────────────────────┐ │\n│ │ memsearch CLI / Python API │ │\n│ │ index · search · expand · watch · compact │ │\n│ └─────────────────────────┬──────────────────────────────┘ │\n│ ┌─────────────────────────┴──────────────────────────────┐ │\n│ │ Core: Chunker → Embedder → Milvus │ │\n│ │ Hybrid Search (BM25 + Dense + RRF) │ │\n│ └────────────────────────────────────────────────────────┘ │\n├──────────────────────────────────────────────────────────────┤\n│ 📄 Markdown Files (Source of Truth) │\n│ memory/2026-03-27.md · memory/2026-03-26.md · ... │\n└──────────────────────────────────────────────────────────────┘\n```\n\nPlugins sit on top of the CLI/API layer. The API handles indexing, searching, and Milvus sync. Markdown files are always the source of truth — Milvus is a rebuildable shadow index. Everything below the plugin layer is what you use as an agent developer.\n\n### How Plugins Work (Claude Code as example)\n\n**Capture — after each conversation turn:**\n\n```\nUser asks question → Agent responds → Stop hook fires\n │\n ┌────────────────────┘\n ▼\n Parse last turn\n │\n ▼\n LLM summarizes (haiku)\n \"- User asked about X.\"\n \"- Claude did Y.\"\n │\n ▼\n Append to memory/2026-03-27.md\n with anchor\n │\n ▼\n memsearch index → Milvus\n```\n\n**Recall — 3-layer progressive search:**\n\n```\nUser: \"What did we discuss about batch size?\"\n │\n ▼\n L1 memsearch search \"batch size\" → ranked chunks\n │ (need more?)\n ▼\n L2 memsearch expand → full .md section\n │ (need original?)\n ▼\n L3 parse-transcript → raw dialogue\n```\n\n### 📄 Markdown as Source of Truth\n\n```\n Plugins append ──→ .md files ←── human editable\n │\n ▼\n memsearch watch (live watcher)\n │\n detects file change\n │\n ▼\n re-chunk changed .md\n │\n hash each chunk (SHA-256)\n │\n ┌───────────┴───────────┐\n ▼ ▼\n hash unchanged? hash is new/changed?\n → skip (no API call) → embed → upsert to Milvus\n │ │\n └───────────┬───────────┘\n ▼\n ┌──────────────────┐\n │ Milvus (shadow) │\n │ always in sync │\n │ rebuildable │\n └──────────────────┘\n```\n\n### 📦 Installation\n\n```bash\n# Install as a global CLI tool — recommended when you mainly use the\n# `memsearch` command or any of the agent plugins (Claude Code, Codex,\n# DSH, OpenClaw, OpenCode), which all shell out to the CLI.\nuv tool install memsearch # via uv\npipx install memsearch # via pipx\npip install memsearch # plain pip\n\n# Install as a project dependency — use this if you want to import\n# `memsearch` from your own Python code (e.g. via the MemSearch class).\nuv add memsearch # via uv, adds to pyproject.toml\npip install memsearch # into an activated venv\n```\n\n\nOptional embedding providers\n\n```bash\n# As a CLI tool (recommended — local ONNX, no API key)\nuv tool install \"memsearch[onnx]\"\npipx install \"memsearch[onnx]\"\npip install \"memsearch[onnx]\"\n\n# As a project dependency\nuv add \"memsearch[onnx]\"\n\n# Other options: [openai], [google], [voyage], [jina], [mistral], [ollama], [local], [all]\n```\n\n\n\n### 🐍 Python API — Give Your Agent Memory\n\n```python\nfrom memsearch import MemSearch\n\nmem = MemSearch(paths=[\"./memory\"])\n\nawait mem.index() # index markdown files\nresults = await mem.search(\"Redis config\", top_k=3) # semantic search\nscoped = await mem.search(\"pricing\", top_k=3, source_prefix=\"./memory/product\")\nprint(results[0][\"content\"], results[0][\"score\"]) # content + similarity\n```\n\n\nFull example — agent with memory (OpenAI) — click to expand\n\n```python\nimport asyncio\nfrom datetime import date\nfrom pathlib import Path\nfrom openai import OpenAI\nfrom memsearch import MemSearch\n\nMEMORY_DIR = \"./memory\"\nllm = OpenAI() # your LLM client\nmem = MemSearch(paths=[MEMORY_DIR]) # memsearch handles the rest\n\ndef save_memory(content: str):\n \"\"\"Append a note to today's memory log (OpenClaw-style daily markdown).\"\"\"\n p = Path(MEMORY_DIR) / f\"{date.today()}.md\"\n p.parent.mkdir(parents=True, exist_ok=True)\n with open(p, \"a\") as f:\n f.write(f\"\\n{content}\\n\")\n\nasync def agent_chat(user_input: str) -> str:\n # 1. Recall — search past memories for relevant context\n memories = await mem.search(user_input, top_k=3)\n context = \"\\n\".join(f\"- {m['content'][:200]}\" for m in memories)\n\n # 2. Think — call LLM with memory context\n resp = llm.chat.completions.create(\n model=\"gpt-5-mini\",\n messages=[\n {\"role\": \"system\", \"content\": f\"You have these memories:\\n{context}\"},\n {\"role\": \"user\", \"content\": user_input},\n ],\n )\n answer = resp.choices[0].message.content\n\n # 3. Remember — save this exchange and index it\n save_memory(f\"## {user_input}\\n{answer}\")\n await mem.index()\n\n return answer\n\nasync def main():\n # Seed some knowledge\n save_memory(\"## Team\\n- Alice: frontend lead\\n- Bob: backend lead\")\n save_memory(\"## Decision\\nWe chose Redis for caching over Memcached.\")\n await mem.index() # or mem.watch() to auto-index in the background\n\n # Agent can now recall those memories\n print(await agent_chat(\"Who is our frontend lead?\"))\n print(await agent_chat(\"What caching solution did we pick?\"))\n\nasyncio.run(main())\n```\n\n\n\n\nAnthropic Claude example — click to expand\n\n```bash\npip install memsearch anthropic\n```\n\n```python\nimport asyncio\nfrom datetime import date\nfrom pathlib import Path\nfrom anthropic import Anthropic\nfrom memsearch import MemSearch\n\nMEMORY_DIR = \"./memory\"\nllm = Anthropic()\nmem = MemSearch(paths=[MEMORY_DIR])\n\ndef save_memory(content: str):\n p = Path(MEMORY_DIR) / f\"{date.today()}.md\"\n p.parent.mkdir(parents=True, exist_ok=True)\n with open(p, \"a\") as f:\n f.write(f\"\\n{content}\\n\")\n\nasync def agent_chat(user_input: str) -> str:\n # 1. Recall\n memories = await mem.search(user_input, top_k=3)\n context = \"\\n\".join(f\"- {m['content'][:200]}\" for m in memories)\n\n # 2. Think — call Claude with memory context\n resp = llm.messages.create(\n model=\"claude-sonnet-4-6\",\n max_tokens=1024,\n system=f\"You have these memories:\\n{context}\",\n messages=[{\"role\": \"user\", \"content\": user_input}],\n )\n answer = resp.content[0].text\n\n # 3. Remember\n save_memory(f\"## {user_input}\\n{answer}\")\n await mem.index()\n return answer\n\nasync def main():\n save_memory(\"## Team\\n- Alice: frontend lead\\n- Bob: backend lead\")\n await mem.index()\n print(await agent_chat(\"Who is our frontend lead?\"))\n\nasyncio.run(main())\n```\n\n\n\n\nOllama (fully local, no API key) — click to expand\n\n```bash\npip install \"memsearch[ollama]\"\nollama pull nomic-embed-text # embedding model\nollama pull llama3.2 # chat model\n```\n\n```python\nimport asyncio\nfrom datetime import date\nfrom pathlib import Path\nfrom ollama import chat\nfrom memsearch import MemSearch\n\nMEMORY_DIR = \"./memory\"\nmem = MemSearch(paths=[MEMORY_DIR], embedding_provider=\"ollama\")\n\ndef save_memory(content: str):\n p = Path(MEMORY_DIR) / f\"{date.today()}.md\"\n p.parent.mkdir(parents=True, exist_ok=True)\n with open(p, \"a\") as f:\n f.write(f\"\\n{content}\\n\")\n\nasync def agent_chat(user_input: str) -> str:\n # 1. Recall\n memories = await mem.search(user_input, top_k=3)\n context = \"\\n\".join(f\"- {m['content'][:200]}\" for m in memories)\n\n # 2. Think — call Ollama locally\n resp = chat(\n model=\"llama3.2\",\n messages=[\n {\"role\": \"system\", \"content\": f\"You have these memories:\\n{context}\"},\n {\"role\": \"user\", \"content\": user_input},\n ],\n )\n answer = resp.message.content\n\n # 3. Remember\n save_memory(f\"## {user_input}\\n{answer}\")\n await mem.index()\n return answer\n\nasync def main():\n save_memory(\"## Team\\n- Alice: frontend lead\\n- Bob: backend lead\")\n await mem.index()\n print(await agent_chat(\"Who is our frontend lead?\"))\n\nasyncio.run(main())\n```\n\n\n\n> 📖 Full Python API reference: [Python API docs](https://zilliztech.github.io/memsearch/python-api/)\n\n### ⌨️ CLI Usage\n\n**Setup:**\n\n```bash\nmemsearch config init # interactive setup wizard\nmemsearch config set embedding.provider onnx # switch embedding provider\nmemsearch config set milvus.uri http://localhost:19530 # switch Milvus backend\n```\n\n**Index & Search:**\n\n```bash\nmemsearch index ./memory/ # index markdown files\nmemsearch index ./memory/ ./notes/ --force # re-embed everything\nmemsearch index . --ignore-file .gitignore # opt in to repository ignore rules\nmemsearch search \"Redis caching\" # hybrid search (BM25 + vector)\nmemsearch search \"auth flow\" --top-k 10 --json-output # JSON for scripting\nmemsearch expand # show full section around a chunk\n```\n\n**Live Sync & Maintenance:**\n\n```bash\nmemsearch watch ./memory/ # live file watcher (auto-index on change)\nmemsearch compact # LLM-powered chunk summarization\nmemsearch stats # show indexed chunk count\nmemsearch reset --yes # drop all indexed data and rebuild\n```\n\n> 📖 Full CLI reference with all flags: [CLI docs](https://zilliztech.github.io/memsearch/cli/)\n\n## ⚙️ Configuration\n\nEmbedding and Milvus backend settings → [Configuration (all platforms)](#️-configuration-all-platforms)\n\nCollection priority: integration-derived default → `~/.memsearch/config.toml` → `.memsearch.toml` → explicit `--collection` or Python argument. Without an integration-derived default, the built-in collection is used.\n\n> 📖 Full config guide: [Configuration](https://zilliztech.github.io/memsearch/home/configuration/)\n\n## 🔗 Links\n\n- 📖 [Documentation](https://zilliztech.github.io/memsearch/) — full guides, API reference, and architecture details\n- 🔌 [Platform Plugins](https://zilliztech.github.io/memsearch/platforms/) — Claude Code, Codex, DeepSeek Harness, OpenClaw, OpenCode\n- 💡 [Design Philosophy](https://zilliztech.github.io/memsearch/design-philosophy/) — why markdown, why Milvus, competitor comparison\n- 🦞 [OpenClaw](https://github.com/openclaw/openclaw) — the memory architecture that inspired memsearch\n- 🗄️ [Milvus](https://milvus.io/) | [Zilliz Cloud](https://cloud.zilliz.com/signup?utm_source=github&utm_medium=referral&utm_campaign=memsearch-readme) — the vector database powering memsearch\n\n## 🤝 Contributing\n\nBug reports, feature requests, and pull requests are welcome! See the [Contributing Guide](CONTRIBUTING.md) for development setup, testing, and plugin development instructions. For questions and discussions, join us on [Discord](https://discord.com/invite/FG6hMJStWu).\n\n## 📄 License\n\n[MIT](LICENSE)\n",
"bytes": 29356,
"sha": "c52b5f0576aa0460b0b80abf0f1f59ed8285ebac91607acf27cab3e66f56236a",
"repo_slug": "zilliztech/memsearch",
"fonte": "repo",
"truncated": false,
"api": "https://api.agentalog.com/api/listings/skl_zilliztech_memsearch_memory_recall_7d166b34/readme"
}
 \n \n memsearch\n


