 \n
\n \n
LLM Usage & Cost Tracker — your local-first spend watchdog
\n\n\n  \n
 \n
 \n
 \n
English | 中文
\n\nStop treating your LLM API bills like a scary horror movie you only look at through your fingers at the end of the month. Know what your LLM calls actually cost — across every provider, in one place, on your own machine. Ask your coding agent (MCP) or type a command (CLI).\n\nIt's a cost **meter**, not a router: it tells you what you spent and which provider fits a workload — it never changes your calls. Pairs happily alongside a router or a model-leaderboard tool.\n\n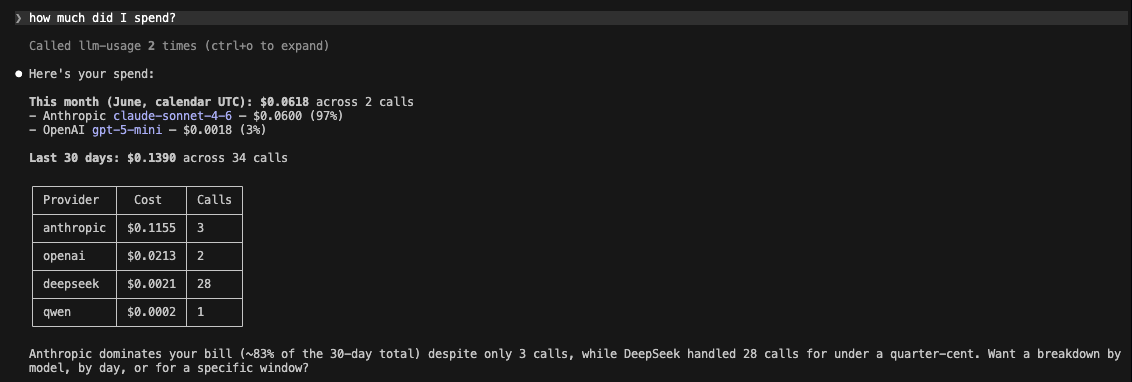\n\nOr straight from the terminal — your week's spend, broken down by provider, and a cross-provider cost comparison before you commit to a model:\n\n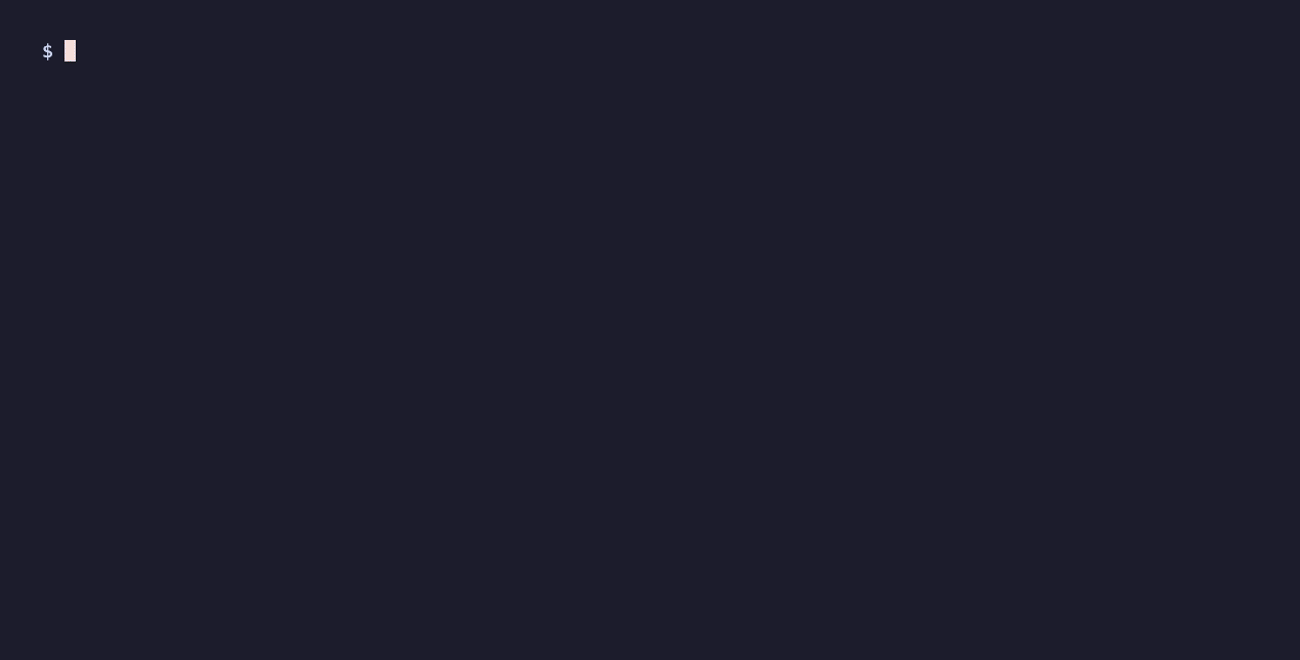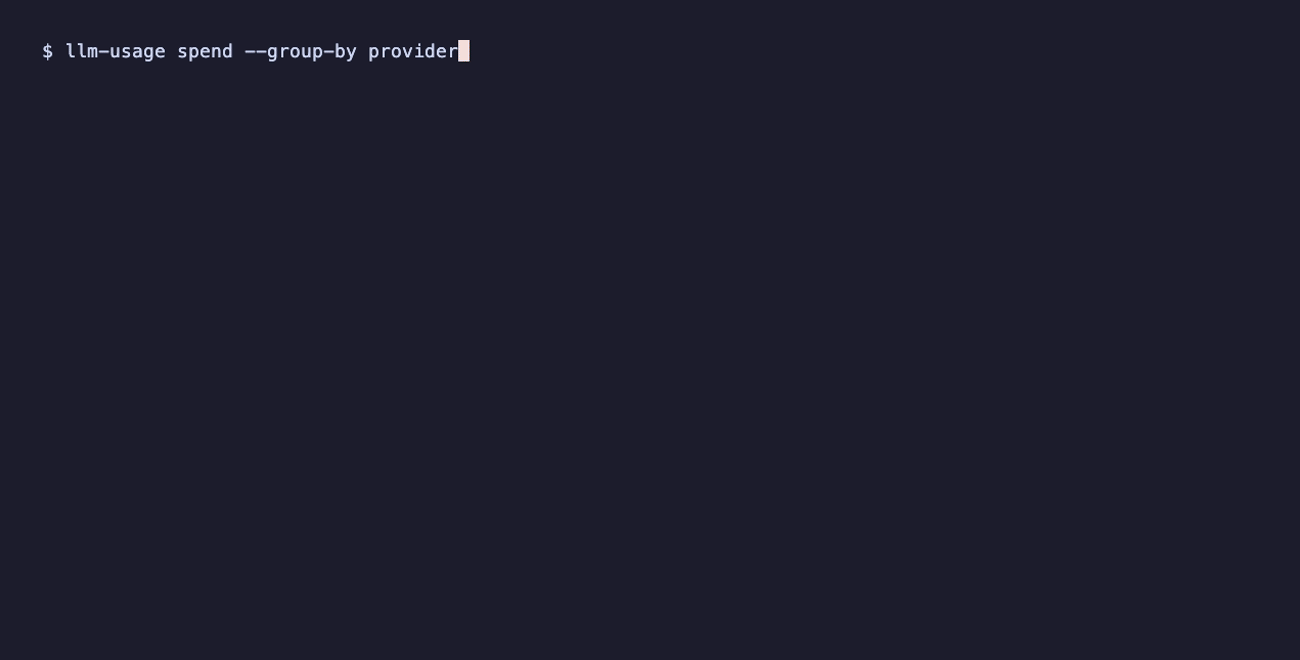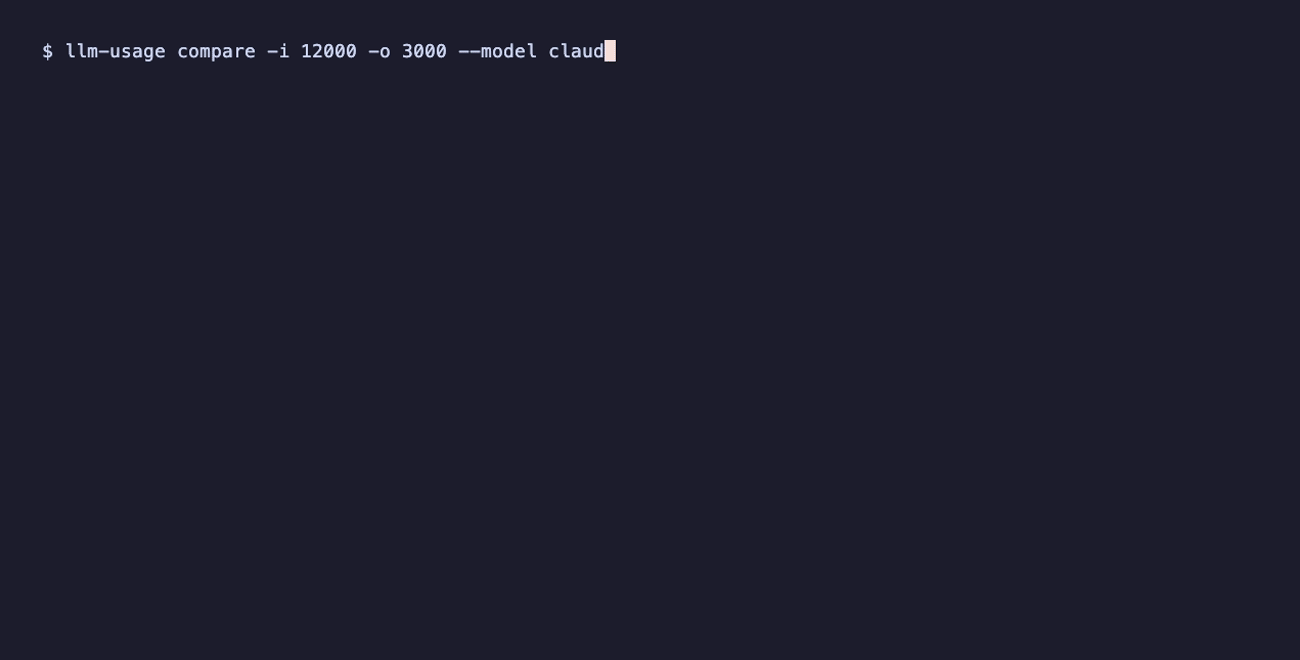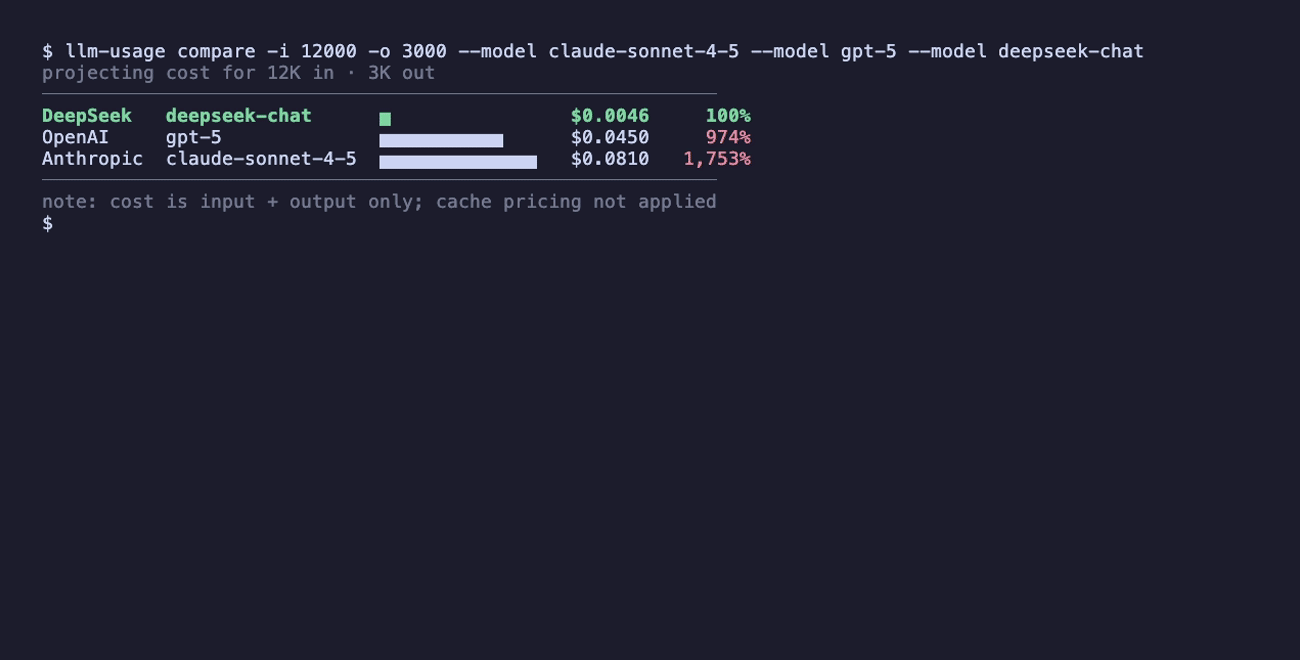\n\n## Why you'd want this\n\nYou're calling LLMs from a handful of providers — Claude, GPT, plus Chinese models like Qwen and DeepSeek. Each one bills in its own dashboard, in its own currency, with its own rules for what a \"cached token\" costs. So the simplest possible question — *how much am I spending, and on what?* — turns into four browser logins, looking up exchange rates for RMB to USD, and trying to decipher what a \"cached context token discount\" actually means in midnight math. Most people just cross their fingers and let the bill be a surprise at the end of the month.\n\n`llm-usage-mcp` captures every call you make into one local store, costs it correctly per provider at the moment it happens, and hands the answer back **two ways**:\n\n- **Ask your coding agent.** It's an MCP server, so Claude Code, Cursor, or any MCP client can answer *\"how much did I spend on Claude this week?\"* or *\"which provider is cheapest for a 10k-in / 2k-out call?\"* in plain English.\n- **Or type a command.** It's also a CLI — `llm-usage spend`, `llm-usage compare`, `llm-usage recommend` — for when you'd rather not round-trip through an agent.\n\nAnd it stays out of your way:\n\n- **Local-first.** No SaaS, no signup, no telemetry. Just a SQLite file at `~/.llm-usage/usage.db`. Privacy is a feature, not a setting.\n- **Multi-provider, Chinese models included.** Anthropic, OpenAI, DeepSeek, Qwen — streaming and non-streaming for all four. DeepSeek and Qwen run the same capture path as Anthropic and OpenAI, not a bolted-on afterthought. More providers (Gemini, Bedrock, Moonshot, …) are [on the way](#supported-providers).\n\n## Quickstart\n\nTwo minutes from `git clone` to your first captured call. This part is about **capture** — getting calls recorded. [Reading the data back](#querying-your-spend) comes next.\n\n### 1. Install\n\nInstall from PyPI with [uv](https://docs.astral.sh/uv/) (or `pipx`) — this puts the three console scripts on your `PATH`:\n\n```bash\nuv tool install llm-usage-mcp # or: pipx install llm-usage-mcp\n```\n\nPrefer to hack on it? Clone and sync from source instead:\n\n```bash\ngit clone https://github.com/zhaoyue722/llm-usage-mcp.git\ncd llm-usage-mcp\nuv sync\n```\n\nEither way you get three console scripts:\n- `llm-usage` — the multi-command CLI. See [From the command line (CLI)](#from-the-command-line-cli) below.\n- `llm-usage-mcp` — the stdio MCP server.\n- `llm-usage-proxy` — a back-compat alias; identical to `llm-usage proxy`.\n\n> The Quickstart below uses `uv run …` (the from-source workflow). If you installed from PyPI, the scripts are already on your `PATH` — drop the `uv run` prefix, and register the MCP server with `claude mcp add llm-usage -- llm-usage-mcp`.\n\n### 2. Set at least one API key\n\nYou only need a key for the provider(s) you actually use; the proxy starts regardless and per-route requests return `503 configuration_error` for any provider whose key is missing.\n\n```bash\nexport ANTHROPIC_API_KEY=sk-ant-...\n# and/or:\nexport OPENAI_API_KEY=sk-...\nexport DEEPSEEK_API_KEY=sk-...\nexport DASHSCOPE_API_KEY=sk-... # Qwen\n```\n\nFull env-var reference: [`docs/configuration.md`](https://github.com/zhaoyue722/llm-usage-mcp/blob/main/docs/configuration.md) (or copy [`.env.example`](https://github.com/zhaoyue722/llm-usage-mcp/blob/main/.env.example) to `.env` and fill in).\n\n### 3. Run the capture proxy\n\n```bash\nuv run llm-usage-proxy\n```\n\nIt binds **loopback-only** (`127.0.0.1:5525`) — never reachable from the network. The proxy holds your API keys server-side; clients never need them.\n\n### 4. Point your coding agent at the proxy\n\nThe proxy exposes one route per provider. Set the matching `*_BASE_URL` env var on the client side:\n\n| Provider | Client env var | Value |\n|---|---|---|\n| Anthropic | `ANTHROPIC_BASE_URL` | `http://127.0.0.1:5525` |\n| OpenAI | `OPENAI_BASE_URL` | `http://127.0.0.1:5525/openai/v1` |\n| DeepSeek | `DEEPSEEK_BASE_URL` (or any OpenAI-SDK base-url override) | `http://127.0.0.1:5525/deepseek/v1` |\n| Qwen | DashScope OpenAI-compatible base | `http://127.0.0.1:5525/qwen/v1` |\n\nExample — launch Claude Code with calls routed through the proxy:\n\n```bash\nANTHROPIC_BASE_URL=http://127.0.0.1:5525 claude\n```\n\n### 5. Confirm it's capturing\n\nMake a call through your agent (or any client pointed at the proxy), then check it landed:\n\n```bash\nuv run llm-usage spend\n```\n\nEvery call lands in `~/.llm-usage/usage.db` with tokens, cost, latency, and a `request_id` for idempotency — and shows up in that headline. That's the whole loop: capture on one side, answers on the other.\n\n## Querying your spend\n\nOnce calls are being captured, you read them back two ways. Same data, same numbers — pick whichever fits the moment.\n\n### Ask your coding agent (MCP)\n\nRegister the MCP server with Claude Code:\n\n```bash\nclaude mcp add llm-usage -- uv --directory $(pwd) run llm-usage-mcp\n```\n\nThen just ask, in plain English, inside that session:\n\n> How much did I spend on Anthropic today? Which provider is cheapest for a 10k-input / 2k-output call?\n\nClaude picks the right tool and reads the numbers back. Seven tools are exposed over stdio; full param/return shapes are in [`docs/spec.md`](https://github.com/zhaoyue722/llm-usage-mcp/blob/main/docs/spec.md).\n\n| Tool | Purpose |\n|---|---|\n| `query_spend` | Totals + per-group rollups over a time window (group by provider / model / project / tag / day). |\n| `usage_summary` | Headline summary for `today` / `week` / `month` / `year` — totals, top-N providers + models, largest call. |\n| `compare_providers` | Given a hypothetical workload (tokens in / out), rank every priced model by cost. |\n| `recommend_provider` | Pick the cheapest priced model that fits a stated budget. |\n| `get_pricing` | Inspect the vendored pricing snapshot. |\n| `list_providers` | List providers + their models + OpenAI-compatibility flag. |\n| `record_usage` | Manual write path — log a call when the capture proxy isn't in the picture. |\n\n`query_spend` and `usage_summary` default to `include_failed=false` so partial-stream rows don't pollute totals; opt-in via the param.\n\n### From the command line (CLI)\n\nThe same questions, as a CLI — eight subcommands under one `llm-usage` console, for when typing is faster than asking your agent.\n\n> The examples below assume `llm-usage` is on your `PATH` — either `source .venv/bin/activate` or `uv tool install .`. Otherwise, prefix each command with `uv run` (e.g. `uv run llm-usage spend`).\n\n```text\n$ llm-usage\n Local-first LLM spend capture + query, exposed over MCP.\n\n Commands\n proxy Run the local LLM capture proxy on 127.0.0.1.\n compare Project the cost of a hypothetical workload across every priced model.\n models Browse the local pricing catalog.\n recommend Recommend the cheapest priced model for a workload + budget.\n spend Show recorded spend over a calendar period.\n status Snapshot of the local install: DB, proxy, providers, pricing.\n providers List configured providers with key state, wire-format, model count.\n about Show version, author, license, and the project homepage.\n```\n\n| Command | The question it answers |\n|---|---|\n| [`compare`](#compare) | Given a workload, who's cheapest? |\n| [`models`](#models) | What do they actually charge per million tokens? |\n| [`recommend`](#recommend) | I've got $0.04 left — which model won't bankrupt me? |\n| [`spend`](#spend) | How much did I just spend? |\n| [`status`](#status) | Is everything actually working? |\n| [`providers`](#providers) | What's configured locally? |\n| [`about`](#about) | What is this, and where do I report a bug? |\n| `proxy` | Run the capture proxy (same as `llm-usage-proxy`). |\n\nConventions that hold across every command:\n\n- `--json` emits the same Pydantic shape the matching MCP tool returns. Pipe straight into `jq`.\n- `--color {auto,always,never}` honors `NO_COLOR` and TTY detection. The palette is a warm, low-contrast dark theme — easy on the eyes at 11pm.\n- Filter flags (`--provider`, `--model`) are case-insensitive on providers, case-sensitive on models, and repeatable where they act as whitelists.\n- `--version` / `-V` prints the version and exits. `--install-completion {bash|zsh|fish|powershell}` installs a tab-completion script — one shell restart later, every flag is `