{
"markdown": "# Pseudolife-MCP\n\n\n\n[](https://pypi.org/project/pseudolife-mcp/)\n[](https://github.com/Pseudogiant-xr/Pseudolife-MCP/actions/workflows/ci.yml)\n[](LICENSE)\n[](https://pypi.org/project/pseudolife-mcp/)\n\n[简体中文](docs/i18n/README.zh.md) ·\n[日本語](docs/i18n/README.ja.md) ·\n[한국어](docs/i18n/README.ko.md) ·\n[Português (BR)](docs/i18n/README.pt-br.md) ·\n[Español](docs/i18n/README.es.md)\n\n**Persistent long-term memory for Claude Code, Codex, and other MCP clients.**\n\nAn MCP server that gives coding agents a long-term memory that persists across\nsessions — surviving context compactions and fresh tasks. Your coding agent is\nthe intelligence; this server is its memory on disk.\n\n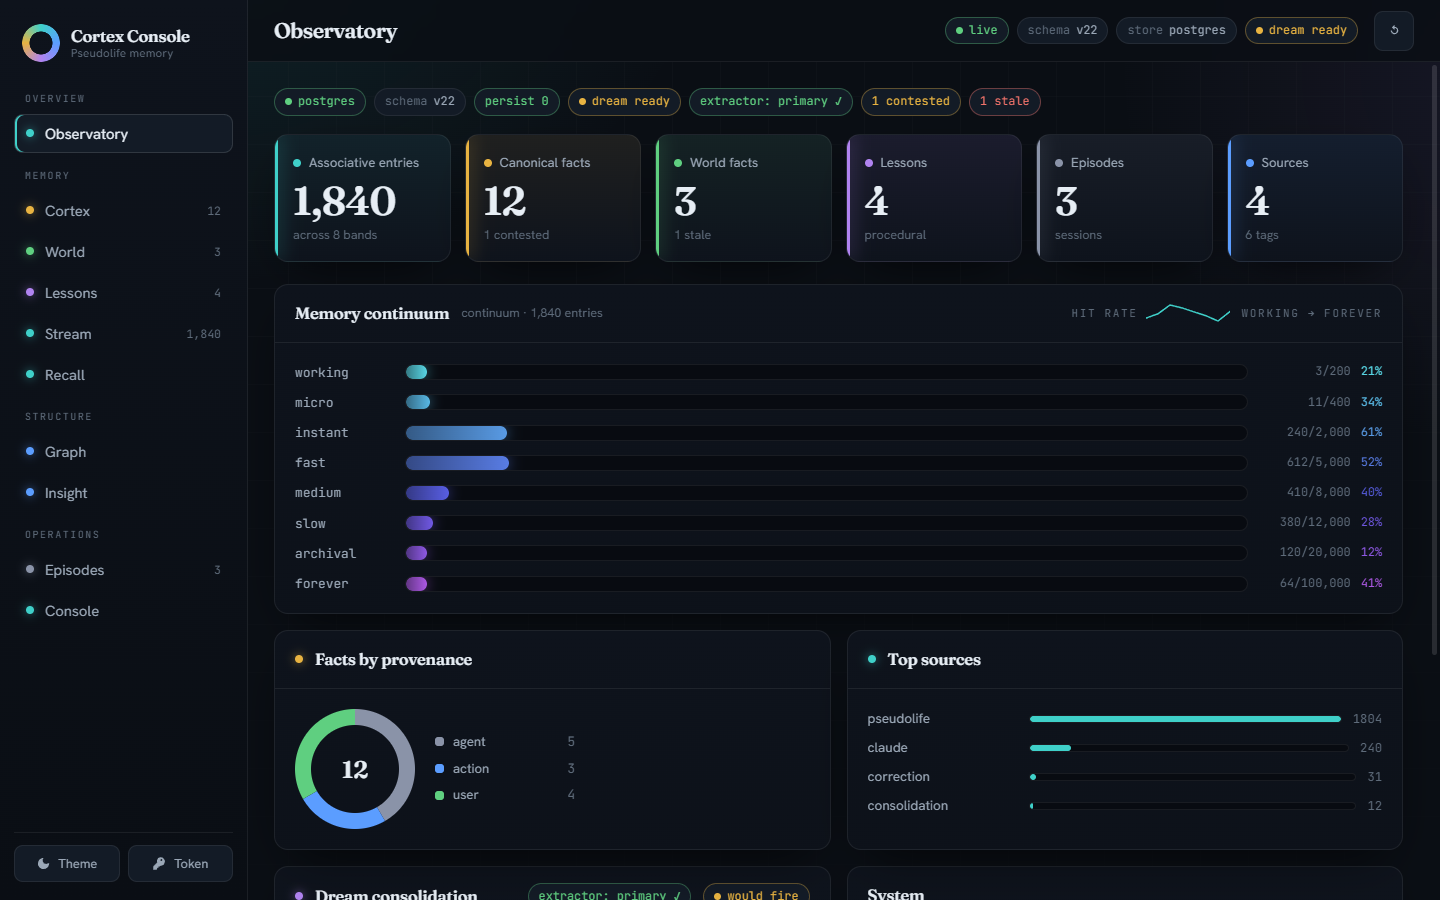\n\nWhat you get:\n\n- **Associative memory with honest forgetting** — a flat similarity store\n ranked by hybrid dense-plus-lexical retrieval, with contradiction\n detection and supersession. (The measured verdict: a preregistered\n ablation campaign found the previous 8-band continuum tied a flat store\n on every gate, so the simpler structure ships; the continuum remains\n one config line away.)\n- **Canonical facts, not vibes** — one *current* value per `entity.attribute`\n slot (or a member set, for slots that hold many concurrent values);\n corrections supersede rather than silently overwrite, and the full\n version history survives.\n- **Dreams** — a bundled local extractor, or any OpenAI-compatible endpoint\n (a Claude model on your Max plan, a GPT-5.6 model on a ChatGPT plan, LM\n Studio, Ollama, vLLM), consolidates the memory stream into facts and a\n knowledge graph while you're not looking.\n- **Lessons from its own work** — successes, dead-ends, and your corrections\n become do/avoid guidance surfaced at the start of every session.\n- **A web console to watch it think** — the Cortex Console above, plus cited\n world facts, session episodes, and document RAG.\n\nMeasured, with receipts — the **full 500-question LongMemEval sweep**, all\nsix question types, and every number ships with its committed run artifact:\n\n| LongMemEval oracle, 500 questions | naive RAG | commit-gated cascade |\n|---|---:|---:|\n| accuracy, all six question types | 0.688 | 0.690 |\n| context tokens per question | ~1210 | **~883** |\n| knowledge-update slice (78 of the 500) | 0.859 | ~~0.936~~ (retired — see below) |\n\nEqual accuracy to naive RAG across the whole benchmark on **~73% of the\ncontext**, and better calibrated about what it does not know: on BEAM-100K's\nabstention questions the fact spine scores **0.950** against naive RAG's\n0.775, unchanged under two independent judges. Read that as calibration,\nnot recall — in the budget-matched five-arm run of 2026-09-02 (rag 0.725 there;\none replicate, local judge) an arm served no memory at all scores 1.000 on\nthe same questions, because refusing is the right answer there and an\nempty context always refuses. The fact spine loses where an answer has to\nbe aggregated across sessions. The second claim to survive a judge swap is\na win rather than a wash: re-run on 2026-09-04 with the hybrid arm\n**budget-matched** to the control at 6 turns, the same 500 questions give\nhybrid **0.730** against naive RAG's 0.690 under the local judge and\n**0.736** against 0.694 under `claude-opus-5` — paired **+0.040 / +0.042**,\np 0.015 / 0.013 — bought with *more* context, ~1229 tokens against the\ncontrol's ~1124, not less, and carried mostly by temporal-reasoning\nquestions. Graded by a local, byte-reproducible judge (the cross-judge check\nnames its second judge) — compare within rows, never against GPT-judged\nleaderboards.\n\n> **Retired 2026-08-25 (#188): the 0.936 knowledge-update headline.** It was\n> measured on the 2026-07-30 bench stack (Qwen3.6-27B answerer and judge).\n> Re-running the same 78 questions after the 2026-08-17 migration to\n> Qwen3.8-27B puts the cascade at **0.846**, below the naive-RAG control —\n> which lands on 0.859 on both stacks. The cascade serves the fact-spine\n> answer unless that channel says \"I don't know\", so it measures the\n> *answerer's* abstention behaviour as much as the memory: 32/78 abstentions\n> at 46/46 commit precision on the old stack, 22/78 at 0.839 on the new one.\n> The 500-question table above is on the older judge and has not been\n> re-judged, so read its cascade row as an upper bound.\n\nFull tables, the per-type breakdown, both stacks side by side, and every\nartifact: [Benchmarks](docs/guide/benchmarks.md).\n\n## Quickstart\n\nTwo commands. No Docker, no database to set up, no container runtime:\n\n```bash\npip install \"pseudolife-mcp[lite]\"\nclaude mcp add --scope user pseudolife-memory -- pseudolife-mcp\n```\n\nCodex instead of Claude Code — same shape:\n\n```bash\npip install \"pseudolife-mcp[lite]\"\ncodex mcp add pseudolife-memory -- pseudolife-mcp\n```\n\nThen in either coding agent: *\"remember that my staging box is haze-02\"* →\nthe agent calls `memory_store`; next session, *\"which box is staging?\"* →\n`memory_search` finds it. Browse everything at the Cortex Console:\n.\n\nThe first session auto-starts the daemon, which provisions an **embedded\nPostgreSQL 18** (pgvector included, via `pg0-embedded`) under a stable\nper-user data dir and downloads the embedding model (~1.2 GB, one-time).\nIt is a real Postgres bank, not a cut-down one: `pseudolife-mcp backup`\nwrites a standard owner-free `pg_dump` archive (plus a state archive, 7-day\nrotation) that restores into any PostgreSQL 18 target regardless of role —\nthe Docker tier included — so outgrowing lite is a dump/restore, not a\nmigration project ([backups](docs/guide/configuration.md#backups)). For a\ntier- and Postgres-version-independent copy, `pseudolife-mcp export` /\n`import` move the whole bank as portable JSONL\n([logical export / import](docs/guide/configuration.md#logical-export--import)).\nWindows needs an ASCII-only data path\n([`PSEUDOLIFE_MCP_DATA_DIR`](docs/guide/configuration.md#connection--deployment-env-vars)).\n\n### What lite gives you, and the one thing it doesn't\n\n| | lite (pip) | durable (Docker) |\n|---|---|---|\n| Associative store, hybrid search, supersession, version history | yes | yes |\n| Cortex facts, knowledge graph, lessons, world facts, episodes | yes | yes |\n| Cortex Console, document RAG, `pseudolife-mcp backup` | yes | yes |\n| **Dream consolidation filling the cortex on its own** | **no extractor ships** | yes — bundled local CPU sidecar |\n| External volumes, health-checked services, deploy/rollback tooling | no | yes |\n\n**The gap, stated plainly.** Lite ships no **extractor**, so the **dream**\npass still runs, prunes, and advances its **cursor**, but writes no\ncanonical facts: on this path `memory_fact_set` is the only **cortex**\nwriter. Everything else above works. Nothing about this is silent —\n`curl http://127.0.0.1:8765/health` reports `\"extractor\": \"none\"`, and the\nstdio shim says the same on stderr at session start.\n\nAny OpenAI-compatible endpoint closes it. The daemon inherits the\nenvironment it starts from, so two variables are the whole fix — with a\nlocal Ollama:\n\n```bash\nexport PSEUDOLIFE_DREAM_BASE_URL=http://localhost:11434/v1\nexport PSEUDOLIFE_DREAM_MODEL=qwen2.5:7b\npseudolife-mcp serve\n```\n\n```powershell\n$env:PSEUDOLIFE_DREAM_BASE_URL = \"http://localhost:11434/v1\"\n$env:PSEUDOLIFE_DREAM_MODEL = \"qwen2.5:7b\"\npseudolife-mcp serve\n```\n\n`/health` then reports `\"extractor\": \"configured\"`. One gotcha: a daemon\nthat is already running keeps the environment it started with, and the shim\nreattaches to it rather than spawning a new one — stop the old daemon\nfirst. A hosted endpoint works too, and costs you the zero-egress\nproperty: memory text leaves the machine. Extractor tiers, quality, and the\ntrade-offs: [Dreaming](docs/guide/dreaming.md).\n\n## Durable tier — Docker (recommended for a long-lived bank)\n\nEverything above plus the bundled extractor, external volumes,\nhealth-checked services, and backup/rollback tooling. Requires Docker and\nat least one MCP-capable coding agent — Claude Code, Codex, and Gemini CLI\nare wired end-to-end; anything else gets paste-ready config\n([provider matrix](docs/guide/providers.md)). One command from clone to\nfirst memory:\n\n```bash\ngit clone https://github.com/Pseudogiant-xr/Pseudolife-MCP.git\ncd Pseudolife-MCP\nops/install.sh # Linux / macOS\nops\\install.ps1 # Windows (pwsh 7+)\n# Codex: add --client codex / -Client codex\n# Both: add --client both / -Client both\n# Gemini: add --client gemini — or several: --client claude,codex,gemini\n# Other MCP agents (Cursor, Windsurf, Zed, ...): --client generic\n```\n\nThe installer asks which agents to wire (multi-select, with a capability\nmatrix showing exactly what each one gets — session briefing, per-turn\ndiscipline, standing file), runs the preflight (one exact fix line per\nmissing prerequisite), then asks which **dream extractor** should\nconsolidate memories —\n\n- **sidecar** — the bundled local CPU model; no Claude plan needed, works\n for everyone, and keeps every memory on the box (~11.8 GB image);\n- **sonnet-only** — the lightest install: a Claude model via a CLI shim\n (`claude-opus-5` by default; the mode name is historical. Needs a\n logged-in Max-plan `claude` CLI); the sidecar image is **never built or\n pulled** (~11.8 GB lighter; dreams pause while the shim is down);\n- **sonnet-fallback** — the Claude shim primary, the bundled sidecar as\n automatic fallback (Max-plan CLI plus the ~11.8 GB image);\n- **codex-only / codex-fallback** — the same two shapes on an OpenAI\n subscription: a GPT-5.6 model (Sol / Terra / Luna) via the Codex CLI\n shim on a signed-in ChatGPT plan (extraction quality unmeasured — see\n the [dreaming guide](docs/guide/dreaming.md)) —\n\nthen brings the stack up, installs the selected clients' session hooks\n(where the client has a hook system), registers the MCP transport (the\nstdio shim by default, with a per-provider writer id; direct HTTP via\n`--transport http`), and health-checks the daemon — finishing with a\nper-agent ladder of what got wired and what that agent's platform cannot\nsupport. Where a session-hook briefing exists (Claude, Codex off-Windows)\nno standing-file edit is needed; for hook-less providers (Gemini CLI,\ngeneric agents, Codex on Windows) the installer offers to append the\nstanding block instead — there it *is* the briefing. `--instructions\nappend` always writes the block from `examples/CLAUDE.memory.md` into\n`~/.claude/CLAUDE.md` / `~/.codex/AGENTS.md` / `~/.gemini/GEMINI.md`\n(useful for subagent visibility even with hooks).\nIdempotent — re-run any time; `--extractor ` switches extractor\nsetups. Non-interactive example:\n`ops/install.sh --extractor sidecar --client codex`.\nLinux (Docker Engine): your user must be in the `docker` group —\n`sudo usermod -aG docker $USER`, then log out/in (the preflight checks this).\n\nImage sizes, the Windows WSL2 memory cap, and what the installer automates:\n[the containerized install](#install--containerized-any-os) below.\n\n\nManual install (the steps the installer automates)
\n\n```bash\nops/preflight.sh --client codex # or ops\\preflight.ps1 -Client codex\ndocker volume create pseudolife-mcp-bank\ndocker volume create pseudolife-mcp-state\ndocker compose -f ops/docker-compose.yml up -d --build # first build, once\n\n# ...or pull the prebuilt images instead of building (releases >= 0.14.0):\ndocker compose -f ops/docker-compose.yml -f ops/docker-compose.ghcr.yml pull pseudolife-pg pseudolife-daemon\ndocker compose -f ops/docker-compose.yml -f ops/docker-compose.ghcr.yml up -d\n\n# Verify, then wire the transport into one or both clients.\ncurl http://127.0.0.1:8765/health\n\n# Stdio shim (the installer's default — per-session episode identity).\n# PSEUDOLIFE_MCP_NO_SPAWN=1 makes the shim wait for the container instead\n# of spawning a host fallback that can shadow the Docker bank after a\n# reboot; set it on Docker-tier registrations like these.\npip install pseudolife-mcp\nclaude mcp add --scope user pseudolife-memory --env PSEUDOLIFE_MCP_NO_SPAWN=1 -- pseudolife-mcp\ncodex mcp add pseudolife-memory --env PSEUDOLIFE_MCP_NO_SPAWN=1 -- pseudolife-mcp\n\n# ...or direct HTTP (no pip package needed; fine for single-session setups):\nclaude mcp add --transport http --scope user pseudolife-memory http://127.0.0.1:8765/mcp\ncodex mcp add pseudolife-memory --url http://127.0.0.1:8765/mcp\n\n# Reinforce the protocol-level memory loop with a global standing instruction:\ncat examples/CLAUDE.memory.md >> ~/.claude/CLAUDE.md\ncat examples/CLAUDE.memory.md >> ~/.codex/AGENTS.md\n# (PowerShell: Add-Content \"$env:USERPROFILE\\.claude\\CLAUDE.md\" (Get-Content examples\\CLAUDE.memory.md -Raw))\n```\n\nOptional knobs live in `ops/.env` (`cp ops/.env.example ops/.env` — the\ninstall/update scripts scaffold it too; every value is commented, a missing\nfile runs entirely on defaults).\n \n\n## What this is\n\nA memory engine exposed over MCP. There's no chat UI and no LLM doing the\nthinking — your coding agent is the intelligence; these are tools it calls to store and\nrecall what matters. (Models *are* bundled as plumbing: baked embedding\nweights for retrieval, and the optional CPU extractor sidecar that\nconsolidates memories into facts while you sleep.)\n\nWhere it sits among the common approaches to agent memory — each column\nis a fair tool for what it's for; this table is about *what question each\none answers*, not who's wrong:\n\n| | notes file (`CLAUDE.md`) | auto-journaling plugin | plain vector store | Pseudolife-MCP |\n|---|---|---|---|---|\n| Survives sessions and compactions | yes | yes | yes | yes |\n| \"What is X *now*?\" has one current answer | if you curate it | no — replays what happened | no — every stored version competes at recall | yes — slot-keyed cortex |\n| A correction replaces the old value | you edit the file | appended beside it | old and new both retrievable, unranked by recency of truth | supersedes, with full version history kept |\n| Facts know their age and go stale | no | no | no | dated, freshness-decayed, quarantined when stale |\n| Distils do/avoid lessons from its own outcomes | no | no | no | yes |\n| Benchmark numbers ship with their raw run artifacts | — | typically no | typically no | every published number, test-enforced |\n\nAuto-journaling records what the agent *did*; Pseudolife curates what it\n*learned*. Both are useful — they answer different questions. Named\nalternatives — Mem0, Zep/Graphiti, Letta, Cognee, memU, Memori — and the\ncases where one of them is the better pick:\n[Comparison](docs/guide/comparison.md).\n\nIt layers several complementary stores: the **associative store** (a flat\nembedding store ranked by cosine similarity fused with a BM25 lexical pool\n(on by default), with contradiction detection and supersession; an 8-tier\nbanded layout is available as an opt-in preset); the **cortex** (slot-keyed canonical facts — one *current*\nvalue per `entity.attribute`, or a member set for set-valued slots — with\nprovenance tiers and contender parking instead of silent overwrites); a typed **knowledge graph** over those facts\nwith a closed relation vocabulary and on-read inference; the **world\ncortex** (durable *cited* facts about external reality, age-decayed trust);\n**procedural lessons** learned from the agent's own work; and a ChromaDB\n**reference bank** for document RAG. The canonical layers in depth:\n[the memory model](docs/guide/memory-model.md); the graph and multi-hop\nrecall: [retrieval](docs/guide/retrieval.md).\n\nState lives in Postgres (the durable source of truth) behind a single\nlong-lived daemon; every session attaches through a thin stdio shim\n(installer default — per-session identity) or directly over HTTP\n(single-session setups). The result: Claude can pick up where it left\noff, correct itself when facts change, and reason over relationships —\nwithout you re-explaining context each session.\n\n## Documentation\n\nThis README is the front door — install, wiring, and the basic loop. The\ndeep material lives in the user guide:\n\n| Page | What's in it |\n|---|---|\n| [Configuration](docs/guide/configuration.md) | Env vars, tuned defaults, toolset tiers, stdio shim, LAN sharing, data layout, backups, schema history |\n| [Providers](docs/guide/providers.md) | Capability matrix per coding agent, the hook-equivalent ladder, AGENTS.md standard, Codex hooks opt-in, writer ids |\n| [Retrieval](docs/guide/retrieval.md) | Reranker, BM25 hybrid, abstention floors, ranking-trace debugging, `memory_recall`, the knowledge graph |\n| [Dreaming](docs/guide/dreaming.md) | Extractor tiers, the bundled sidecar, upgrading the extractor, Sonnet-fallback, cadence, deep dream, consolidation |\n| [Episodes & sessions](docs/guide/episodes.md) | Daemon-owned session episodes, the briefing hook, nested sub-episodes, tags |\n| [The memory model](docs/guide/memory-model.md) | Cortex slots, provenance contenders, world cortex, lessons, temporal/HLC stamps |\n| [Benchmarks](docs/guide/benchmarks.md) | LongMemEval results; why extraction quality dominates |\n| [Comparison](docs/guide/comparison.md) | Mem0, Zep/Graphiti, Letta, Cognee, memU, Memori — the axes, and when to use something else |\n| [Security posture](docs/guide/security-posture.md) | Memory poisoning (ASI06): every shipped mitigation, and what is not defended |\n\nPlus [`evals/README.md`](evals/README.md) (full benchmark methodology) and\n[CONTRIBUTING](CONTRIBUTING.md).\n\n## Tools exposed\n\nThe surface was consolidated 2026-07-02 (55 → 32 tools; now 35 with\n`memory_toolset` and the set-slot pair): lifecycle families became verb-dispatched tools\n(`memory_dream`, `memory_forget`, `memory_graph_review`), and\ndump/introspection views moved to the Cortex Console (REST) — the manifest\nis agent context every session, so it stays lean.\n\n| Tool | Purpose |\n|------|---------|\n| `memory_store(text, source?, tags?, origin?, episode?, authority?, distortion_tolerance?)` | Remember one durable fact / decision / observation (canonical facts reach the cortex via the dream pass or `memory_fact_set`); `authority`/`distortion_tolerance` label the speech act and how exactly it must survive — `auto` (default) is a deterministic form heuristic, no model call, and both labels are inherited through supersession unless restated |\n| `memory_search(query, top_k?, filters..., rerank?, bm25?, explain?, verbose?)` | Associative retrieval; canonical `cortex` facts surface ahead of recall hits, each dated (`asserted_at` / `last_confirmed` / human `age`, plus `stale` when it has rotted); `explain=True` attaches a ranking trace |\n| `memory_recent(n?, sources?, episodes?, tags?, verbose?)` | Newest stores, timestamp-ordered (debug + session catch-up) |\n| `memory_supersede(old_text, new_text)` | Explicit correction — mark a memory obsolete, keep it as history; the result's `derived_flagged` names the canonical facts the dream built on what was corrected (flagged, never rewritten) |\n| `memory_forget(scope, ...)` | Forget from one store: `memory` (by text/substring/source/episode/tag) and `fact` hard-delete; `world` and `lesson` (by entity/attribute) retire the slot with an audit row — reversible via `memory_graph_review(action=\"restore_slot\")` |\n| `memory_stats()` | Store occupancy, hit rates, totals |\n| `memory_get(entry_id)` / `memory_reinforce(entry_id)` | Dereference a memory id to its full episode (+ `consolidated_into`); reinforce it after finding it useful |\n| `memory_fact_get(entity, attribute)` | The one CURRENT canonical value at a slot (+ parked contenders); on an empty slot returns ranked `candidates` (same-entity, then similar slots); aged/contested facts carry a ready-made `correct_with` call (as do `memory_search` / `memory_world_search` hits) |\n| `memory_fact_set(entity, attribute, value, origin?, confidence?, episode?, freshness_class?, authority?, distortion_tolerance?)` | Assert a canonical fact deliberately (insert / confirm / supersede / contest); `freshness_class` (`auto` default) says how fast the slot rots — `auto` infers it from the entity's kind; `authority`/`distortion_tolerance` (`auto` = deterministic form heuristic, no model call) inherit the slot's labels unless restated |\n| `memory_fact_resolve(entity, attribute, accept)` | Settle a contested slot — adopt (`true`) or discard (`false`) the contender |\n| `memory_set_add(entity, attribute, member)` / `memory_set_remove(entity, attribute, member)` | Add/confirm or retract one member of a set-valued slot (many concurrent values, e.g. tags — not one NOW value); a scalar there converts to a set one-way on first `memory_set_add`, except a number-led aggregate scalar (\"32\", \"$1,500\"), which is protected — the add parks as a contender instead. Read with `memory_fact_get`, which returns `{kind: \"set\", members, removed}` for these slots |\n| `memory_history(entity, attribute?)` | With `attribute`: version timeline at a slot, with writer/temporal stamps. Without: the entity's causal chain — dated fact/entry/edge/lesson events (\"what led to X\") |\n| `memory_world_set(entity, attribute, value, source_url?, ...)` | Assert a cited WORLD fact (external knowledge; age-decayed trust by freshness class) |\n| `memory_world_search(query, top_k?, verbose?)` | Search world facts — each carries `effective_confidence`, a `stale` flag, and its citation |\n| `memory_outcome(task, outcome, about?, detail?, polarity?, episode?, used_ids?)` | Record a procedural outcome signal (`success`/`failure`/`correction`); the dream distils signals into lessons. `used_ids` names the search hits the work actually turned on — each credits every `retrieval_events` row in the session window that served it with a `retrieval_uses` label (`used_via=outcome`), the relevance signal a learned reranker trains on; same session, within `use_window_seconds`, or nothing is credited |\n| `memory_lesson_search(query, top_k?, verbose?)` | Recall learned lessons for the task at hand — heed `polarity` `-` dead-ends; `re_verify` flags lessons whose subject facts changed since |\n| `memory_dream(action, limit?, cursor?, apply?, snippets?, run_id?)` | Drive the dream: `status` / `pull` / `commit` / `run` (server-side extractor) / `runs` (audit trail of recent passes) / `rollback` (revert the latest committed pass from its pre-image journal) / `deep` (full-corpus graph consolidation; dry-run unless `apply`, which snapshots the graph tables first; `snippets=false` omits candidate evidence; responses carry evidence-enriched `merge_proposals` for near-duplicate triage) |\n| `memory_graph_review(action, proposal_id?, proposal_ids?, proposals?, scope?, src?, dst?, relation?, store?)` | Work the review queue: `list` / `propose` / `relate` (link a pair *and* dismiss its duplicate proposal in one call) / `dismiss_pair` / `dismiss_slot_pair` / `restore_slot` / `accept_link` / `reject_link` / `accept_merge` / `accept_junk` / `reject_entity` (merge/entity decisions are audit-stamped `decided_by=agent` over MCP, `human` via Console); `proposal_ids` settles many id-actions in one call; `restore_slot` undoes a `memory_forget(scope=\"lesson\"/\"world\")` retirement — `store` + the retired `entity|attribute` key in `src` (or a bare entity to restore every retired aspect) |\n| `memory_session_title(title, episode?)` | Name THIS session's auto-opened episode (default titles are generic); `episode` is your session handle from the briefing — concurrent sessions share one HTTP connection, so pass it to land the rename on your own episode |\n| `memory_episode_start(title, hint?, episode?)` / `memory_episode_end(episode?)` | Open/close a nested sub-episode for a substantial task; entries stored while open carry its id; `episode` is your session handle so the nest/pop lands in your own tree when several sessions run concurrently |\n| `memory_episode_summary(id)` | Stats + tag/source distribution + recent entries within an episode |\n| `memory_consolidation_candidates(query?, episode?, ...)` | Cluster near-duplicate memories ripe for consolidation |\n| `memory_consolidate(replaces, new_text, source?, tags?)` | Atomic supersede + store — replace a cluster with one canonical note |\n| `memory_graph_relate(src, relation, dst, ...)` | Assert a typed edge (closed relation vocabulary; re-assertion bumps confidence) |\n| `memory_graph_unrelate(src, relation, dst)` | Retract an edge (superseded, kept for audit) |\n| `memory_alias(entity, alias)` | Bind an alternative name — lookups resolve aliases first |\n| `memory_graph(entity, depth?, include_facts?, to?, relation_filter?)` | Entity neighborhood (≤3 hops) with derived transitive/inverse edges and per-edge `EXTRACTED/INFERRED/AMBIGUOUS` provenance tags; `to` returns the shortest path between two entities |\n| `memory_recall(query, hops?, top_k?, verbose?)` | Multi-hop retrieval for relational questions; `low_confidence: true` → fall back to `memory_search` |\n| `memory_relation_define(name, description, ...)` | Grow the closed relation vocabulary (deliberate, rare act) |\n| `document_ingest(path, source?)` | Index a file (txt/md/pdf/html) verbatim in the reference bank — the lossless complement to agent-side distillation ([division of labor](docs/guide/memory-model.md#background-documents--the-reference-bank)) |\n| `document_search(query, top_k?)` | RAG search over the reference bank only |\n| `memory_toolset(action)` | Check or change this principal's visibility tier: `status` / `expand` / `collapse` |\n\nEach tool returns plain JSON. See `pseudolife_memory/mcp_server.py` for\ndocstrings — those are what Claude reads to decide when to call which tool.\nThe five recall-path tools return **compact entries** by default (result\npayloads are agent context on every retrieval); pass `verbose=true` for full\nmetadata. Full-table dumps and topology views live in the **Cortex Console**\n(`/api/*`) and the `pseudolife-mcp briefing` CLI.\n\n**Toolset tiers.** Three visibility tiers — `minimal` (9 tools), `core`\n(22), `full` (35) — filtered per principal at\n`tools/list`; a principal (the named bearer-token identity, or the writer\nid for single-token installs) steps its own tier up or down with\n`memory_toolset` before calling a hidden tool. Defaults, per-client mapping, and weak-model\ndeployments:\n[Configuration — toolset tiers](docs/guide/configuration.md#toolset-tiers).\n\n## Architecture\n\nOne **memory daemon** owns the bank and serves MCP over streamable HTTP\nat `/mcp`; every Claude Code session (and any LAN agent) attaches to it.\n**Postgres 18 + pgvector** (in Docker on the durable tier; the lite tier\nruns the same Postgres embedded, no container) is the durable source of\ntruth —\nthe in-memory store is a write-through cache hydrated at startup\n(a small `weights.pt` persists only counters — there are no MLP weights).\n\nThe daemon runs **either** containerized (recommended — portable, no host\nPython) **or** as a host process. Claude Code attaches through a thin\ntorch-free stdio **shim** (the installer default — per-session identity,\nneeded for concurrent sessions) **or** directly over **HTTP** (simpler for\na single session):\n\n```\nClaude session A ─┐ stdio shim (installer default) or HTTP\nClaude session B ─┼───────────────────► pseudolife-mcp daemon ─► Postgres (Docker)\nLAN agent ────────┘ or stdio shim (single writer) pgvector\n (per session) host proc OR Docker\n```\n\nThis kills two v0.1 hazards by construction: a single writer means\nconcurrent sessions can't clobber each other, and entries are transactional\nso a crash can't wipe the bank. On top of the associative store sit the\ncanonical layers — cortex, world facts, lessons, temporal/HLC stamps\n([the memory model](docs/guide/memory-model.md)) — joined to a typed\nknowledge graph walkable via `memory_graph` and multi-hop `memory_recall`\n([retrieval & the graph](docs/guide/retrieval.md)).\n\n## Install — containerized (any OS)\n\nWhat [the durable tier](#durable-tier--docker-recommended-for-a-long-lived-bank)\ninstaller above does, by hand. The whole stack — Postgres **and** the memory daemon — runs in Docker.\nNo host Python, no torch install, no version skew; the daemon image bakes\nin CPU-only torch and the embedding weights — `Qwen/Qwen3-Embedding-0.6B`\n(the default retrieval backbone since schema v25) plus `all-MiniLM-L6-v2`\n(kept baked for the ONNX-parity test path) — so it runs identically on\nWindows / macOS / Linux. Requires only Docker; built once: ~5.0 GB daemon\nimage (measured 2026-07-29 on the deployed build) + ~0.6 GB Postgres +\n~11.8 GB extractor sidecar (measured 2026-08-20 with the v3 multi-task\nbake; skip the sidecar entirely with the installer's `sonnet-only` mode).\nThe ~12.6 GB and ~10.4 GB figures published before\n2026-07-29 are retired: both were inflated by a CUDA torch build that a\ndependency-resolution bug pulled into the image (see the CHANGELOG); the\ndaemon has always been CPU-only.\n\n```bash\ngit clone https://github.com/Pseudogiant-xr/Pseudolife-MCP.git\ncd Pseudolife-MCP\n\n# 1. One-time: create the two persistent volumes (bank + daemon state).\ndocker volume create pseudolife-mcp-bank\ndocker volume create pseudolife-mcp-state\n\n# 2. Build + start all three services (Postgres, extractor, then the daemon).\ndocker compose -f ops/docker-compose.yml up -d --build\n```\n\nOr skip the ~5 GB daemon build entirely and **pull the prebuilt images**\n(releases ≥ 0.14.0):\n\n```bash\ndocker compose -f ops/docker-compose.yml -f ops/docker-compose.ghcr.yml pull pseudolife-pg pseudolife-daemon\ndocker compose -f ops/docker-compose.yml -f ops/docker-compose.ghcr.yml up -d\n```\n\nThe extractor sidecar is not published and still builds locally; updates on\nthe pull path are `pull` + `up -d`, not `ops/update.ps1`.\n\n> **Upgrading from a pre-rename install** (volumes `ops_pseudolife_pgdata` /\n> `ops_pseudolife_data`)? Don't rename those volumes — keep pointing at them by\n> creating `ops/.env` with `PSEUDOLIFE_BANK_VOLUME=ops_pseudolife_pgdata` and\n> `PSEUDOLIFE_STATE_VOLUME=ops_pseudolife_data` before `up`. See the compose header.\n\n> **Windows:** cap Docker Desktop's WSL2 VM, which otherwise claims up to\n> ~50% of host RAM — how much the stack actually needs, the\n> `ops/wslconfig.example` template, and the daemon container's own memory\n> cap: [Configuration — Windows / WSL2 memory](docs/guide/configuration.md#windows--wsl2-memory-docker-tier).\n\nThe daemon serves MCP at `http://127.0.0.1:8765/mcp` and restarts with\nDocker — no logon task needed. First build downloads the model into the\nimage (once); every container start after that is offline and fast. Wire\nClaude Code in via the stdio shim (installer default) or directly over\nHTTP (both below). Where the data actually lives, and\nhow to back it up:\n[Configuration — data layout](docs/guide/configuration.md#data-layout).\n\n**Host-process install (Windows, for GPU / dev):** run Postgres in Docker\nbut the daemon on host Python — for hacking on the daemon or running the\nembedder on a local GPU. Steps, the `pseudolife-mcp` CLI modes, and the\nlogon autostart task:\n[Configuration — host-process install](docs/guide/configuration.md#host-process-install-windows-for-gpu--dev).\n\n## Updating\n\n**Lite tier:** one command, bank untouched:\n\n```bash\npip install -U \"pseudolife-mcp[lite]\"\n```\n\n**Docker tier:** after a `git pull` (or local code change), redeploy the\n**daemon only** — safely, without touching Postgres or the extractor:\n\n```powershell\n.\\ops\\update.ps1 # Windows\n```\n```bash\n./ops/update.sh # Linux / macOS\n```\n\nIt backs up the bank (`pg_dump` + a state-volume tar), tags a rollback\nimage (when a previous one exists — it says so loudly when there isn't),\nrebuilds + recreates **only** the daemon, and waits for `/health`.\nIt never runs `down -v`. (Host-process install: just restart the daemon —\n`pip install -e .` is editable.) Build cache is pruned automatically after\nevery healthy deploy; see\n[Docker disk retention](docs/runbooks/docker-disk-retention.md) for the\nweekly Scheduled Task and the manual `.vhdx` compact. Never run\n`docker system prune --volumes`, which deletes volumes.\n\n> **Two upgrades are not automatic**, because neither can be done safely\n> in place. Both have a step-by-step runbook — backup, dry run, apply,\n> verify, roll back — and a fresh install needs neither:\n>\n> - **A bank older than 0.11.0 (schema v25)**: every embedding column moved\n> from `vector(384)` to `vector(1024)`, so the daemon refuses to start\n> rather than half-migrate. Re-embed offline with\n> `ops/migrate_embeddings.py` —\n> [the v25 migration runbook](docs/runbooks/embedding-v25-migration.md).\n> - **A Docker-tier bank created before 2026-08-14 (PostgreSQL 16 → 18)**:\n> a Postgres major bump cannot reuse the old data volume. Run\n> `pwsh ops/migrate-pg18.ps1` —\n> [the PostgreSQL 18 migration runbook](docs/runbooks/postgres-18-migration.md).\n\n## Wire into your coding agent\n\n**Plugin (hooks + commands).** With the daemon running, two commands inside\nClaude Code wire the session hooks (briefing + episode identity), the\nmemory-loop instructions, and the `/dream` + `/memory-status` commands:\n\n```\n/plugin marketplace add Pseudogiant-xr/Pseudolife-MCP\n/plugin install pseudolife-memory@pseudolife-mcp\n```\n\nThe plugin replaces the settings.json hook **and** the CLAUDE.md block below\n— the same standing instructions arrive as session context from the daemon.\nIt deliberately does **not** bundle the MCP server: Claude Code loads a\nplugin server alongside any user-registered one with no deduplication, which\ndoubled every session's tool namespace next to the installer's registration\n— so the transport is registered exactly once, by `ops/install.*` (stdio\nshim by default — per-session episode identity) or the one-liner below.\nDetails, non-default ports/tokens, and migration:\n[plugin/README.md](plugin/README.md).\n\n**Manual transport registration.** The installer's default (shim mode)\nregisters a thin stdio shim — one shim process per session, so every\nsession carries its own tier-1 identity. The same wiring by hand:\n\n```bash\npip install pseudolife-mcp # daemon in Docker; add [lite] for the pip tier\nclaude mcp add --scope user pseudolife-memory --env PSEUDOLIFE_MCP_NO_SPAWN=1 -- pseudolife-mcp\n```\n\n`PSEUDOLIFE_MCP_NO_SPAWN=1` belongs on Docker-tier registrations: the shim\nthen waits for the container instead of spawning a host-side fallback whose\nport bind can race a still-booting Docker and shadow the real bank. On the\n`[lite]` pip tier drop the `--env` — there the spawn fallback *is* the\nzero-config path.\n\nDirect HTTP works too — the daemon serves MCP over HTTP natively (no shim,\nno host command, nothing OS-specific; concurrent sessions then share one\nepisode identity, so it fits single-session setups best):\n\n```bash\nclaude mcp add --transport http --scope user pseudolife-memory http://127.0.0.1:8765/mcp\n```\n\n(`--scope user` registers it for every project; drop it to register for the\ncurrent project only.) Or write the equivalent JSON yourself — into\n`~/.claude.json` under the top-level `mcpServers` key for user scope, or into\na `.mcp.json` at a project root for project scope:\n\n```json\n{\n \"mcpServers\": {\n \"pseudolife-memory\": {\n \"type\": \"http\",\n \"url\": \"http://127.0.0.1:8765/mcp\"\n }\n }\n}\n```\n\nFor a token-protected daemon, add a `headers` key to that Claude JSON entry:\n`\"headers\": { \"Authorization\": \"Bearer \" }`.\n\nCodex — the installer's default (shim mode) wires the same stdio shim, so a\nCodex session gets its own tier-1 identity instead of inheriting a\nconcurrent Claude session's episode:\n\n```bash\npip install pseudolife-mcp\ncodex mcp add pseudolife-memory --env PSEUDOLIFE_MCP_NO_SPAWN=1 -- pseudolife-mcp\n```\n\n(Same Docker-tier note as the Claude wiring above: keep\n`PSEUDOLIFE_MCP_NO_SPAWN=1` when the daemon runs in Docker; drop it on the\n`[lite]` pip tier.)\n\nThe HTTP one-liner works too (no pip package needed):\n\n```bash\ncodex mcp add pseudolife-memory --url http://127.0.0.1:8765/mcp\n```\n\nOr add the equivalent user-level entry to `~/.codex/config.toml`:\n\n```toml\n[mcp_servers.pseudolife-memory]\nurl = \"http://127.0.0.1:8765/mcp\"\nbearer_token_env_var = \"PSEUDOLIFE_MCP_TOKEN\"\n```\n\nFor that Codex HTTP configuration, export `PSEUDOLIFE_MCP_TOKEN` in the\nenvironment that launches Codex. The token stays out of `config.toml`, and\nCodex reads it when connecting. This is unnecessary for the default stdio shim.\n\nGemini CLI — same shape (`-s user` matters: Gemini defaults to project\nscope; the `-e` env gives Gemini sessions their own write attribution, and\nthe same Docker-tier `PSEUDOLIFE_MCP_NO_SPAWN=1` note as above applies):\n\n```bash\npip install pseudolife-mcp\ngemini mcp add -s user -e PSEUDOLIFE_WRITER_ID=gemini -e PSEUDOLIFE_MCP_NO_SPAWN=1 pseudolife-memory pseudolife-mcp\n```\n\nOr HTTP, no pip package needed:\n\n```bash\ngemini mcp add -s user -t http pseudolife-memory http://127.0.0.1:8765/mcp\n```\n\nNote: since 2026-06-18 Google no longer serves individual-tier accounts\n(free, AI Pro, AI Ultra) through Gemini CLI — OAuth sign-in fails and\npoints at Antigravity. The wiring above stays correct, but individual\naccounts need API-key auth (`GEMINI_API_KEY`) to actually run sessions —\nor use Google Antigravity itself, which connects to the same bank via\n`~/.gemini/config/mcp_config.json`; both are covered in\n[the providers guide](docs/guide/providers.md#gemini-cli).\n\n**Any other MCP-capable agent** (Cursor, Windsurf, Zed, Copilot CLI, …) —\nadd the generic `mcpServers` entry to that tool's MCP config (`ops/install.sh\n--client generic` prints both shapes ready to paste):\n\n```json\n{\n \"mcpServers\": {\n \"pseudolife-memory\": {\n \"command\": \"pseudolife-mcp\",\n \"env\": {\n \"PSEUDOLIFE_WRITER_ID\": \"mcp-client\",\n \"PSEUDOLIFE_MCP_NO_SPAWN\": \"1\"\n }\n }\n }\n}\n```\n\nWhat each agent gets — and what its platform can't support (hooks,\nper-turn discipline): [the provider matrix](docs/guide/providers.md).\n\n**Verify:** run `claude mcp list`, `codex mcp list`, or `gemini mcp list`\n(the server should report connected), then ask the agent to *\"store a memory\nthat this install works\"* and check it\nappears in the Stream tab of the Console at .\n\nPreferring stdio (this is what the installer wires by default, for\nper-session identity)? A thin torch-free **shim** proxies stdio to the\ndaemon:\n[stdio shim](docs/guide/configuration.md#stdio-shim-per-session-identity)\n· [LAN sharing](docs/guide/configuration.md#sharing-memory-on-the-lan)\n· [backups & restore rehearsal](docs/guide/configuration.md#backups).\n\n## Recommended agent setup (CLAUDE.md / AGENTS.md)\n\nThe server's value depends entirely on the agent *using* it well — **this step\nis what makes the memory loop actually fire**. The MCP server advertises the\ncore loop through protocol-level `instructions`, and the session hook (one\ncommand, below) delivers the full block every session — **plugin users and\nhook users need nothing more**. If you want it in a standing file instead —\nor additionally, for subagent visibility (subagents read `CLAUDE.md` but not\nhook output) — append it to Claude's global `~/.claude/CLAUDE.md`, Codex's\nglobal `~/.codex/AGENTS.md`, Gemini's global `~/.gemini/GEMINI.md`, or a\nper-project `CLAUDE.md` / `AGENTS.md`:\n\n```bash\ncat examples/CLAUDE.memory.md >> ~/.claude/CLAUDE.md\ncat examples/CLAUDE.memory.md >> ~/.codex/AGENTS.md\ncat examples/CLAUDE.memory.md >> ~/.gemini/GEMINI.md\n```\n\n```powershell\nAdd-Content \"$env:USERPROFILE\\.claude\\CLAUDE.md\" (Get-Content examples\\CLAUDE.memory.md -Raw)\nAdd-Content \"$env:USERPROFILE\\.codex\\AGENTS.md\" (Get-Content examples\\CLAUDE.memory.md -Raw)\n```\n\nFor hook-less providers this standing block is not a nice-to-have — it *is*\nthe session briefing. `AGENTS.md` is the cross-vendor standard for standing\nagent instructions (Linux Foundation-governed; read by Codex, Copilot,\nCursor, Gemini CLI, Zed, and 30+ others), so a per-project `AGENTS.md`\ncarrying the block reaches almost every agent at once. Claude Code is the\nholdout — it reads `CLAUDE.md` — but a `CLAUDE.md` whose first line is\n`@AGENTS.md` imports the shared file, so one copy serves every tool.\n\nThe block ([`examples/CLAUDE.memory.md`](examples/CLAUDE.memory.md)) teaches\nthe loop: **RECALL at the start** (`memory_search` / `memory_lesson_search` /\n`memory_fact_get` / `memory_world_search`), **CAPTURE as you go**\n(`memory_store` with an honest `origin`, `memory_fact_set` for canonical\nfacts, `memory_world_set` for cited external facts, `source=\"status\"` for\nverbose logs so they stay out of the dream), **REFLECT at the end**\n(`memory_outcome`, with `used_ids` naming the hits you actually used — the\ndream distils these signals into the lessons surfaced at your next session\nstart).\n\nOne command — `ops\\install-hook.ps1 -Client codex` (Windows, PowerShell 7) or\n`ops/install-hook.sh --client codex` (Linux/macOS) — installs the\n**SessionStart briefing hook** for the selected client (what your memory is\nunsure about + lessons from past work + verified world facts + where we left\noff, injected at every session start) and, for the Claude client, a\n**UserPromptSubmit discipline hook**: a static one-line memory reminder on\nevery turn — recall before reviewing code, docs, or PRs, then compare memory\nagainst the files; status questions are memory questions; log outcomes.\n(Codex is excluded from the per-turn hook: its per-prompt hook support is\nunverified, and every new Codex hook needs a manual trust review.) The\ninstaller backs up `~/.claude/settings.json`\nor `~/.codex/hooks.json` and is idempotent. The manual hook JSON,\nthe briefing budget flags, and how session episodes open/close/resume\nwithout any hooks: [Episodes & sessions](docs/guide/episodes.md).\n\n**Codex hooks are experimental and off by default** (and not available on\nWindows — use the standing AGENTS.md block there). Writing `hooks.json` is\nnot enough on its own; first enable the hook engine in `~/.codex/config.toml`:\n\n```toml\n[features]\ncodex_hooks = true\n```\n\n**Codex hook trust:** Codex also skips every new or changed hook until you\nreview and trust its exact definition. After installing the Codex hook, start\nCodex, open `/hooks`, review the definition from `~/.codex/hooks.json`, and\napprove it. Until then, MCP tools still work and the server-level\n`instructions` still load, but the richer session briefing is not injected.\n\n## Usage patterns\n\n**At session start** — loads what you've worked on before, persistent\nacross compactions:\n```\nmemory_search(\"project context for X\")\n```\n\n**During work** — store real decisions; skip fleeting chatter (the shipped\nstore gate is permissive, so deliberate, durable claims only):\n```\nmemory_store(\"Decided to use stdio transport for the MCP because no port conflicts\", source=\"pseudolife\")\n```\n\n**When corrected** — marks the old fact superseded *and* stores the\ncorrection; both surface in future retrieval, the new one ranked higher:\n```\nmemory_supersede(\n \"Provider interface uses synchronous calls\",\n \"Provider interface uses async calls — sync version was the v0.7 prototype only\"\n)\n```\n\n**Hygiene** — `memory` and `fact` scopes hard-delete (at least one filter\nis required for scope `memory`, preventing accidental wholesale deletion);\n`lesson` and `world` scopes retire the slot with an audit row and are\nreversible with `memory_graph_review(action=\"restore_slot\", store=...,\nsrc=\"entity|attribute\")`; for \"keep the history but mark it wrong\" use\n`memory_supersede` instead:\n```\nmemory_forget(scope=\"memory\", source=\"test-noise\")\nmemory_forget(scope=\"fact\", entity=\"test-entity\")\n```\n\n**Discovering what's in the bank:** open the Cortex Console — sources, tags,\nepisodes, and full-table views all live there. Going deeper:\n[reranking, BM25, abstention, and trace debugging](docs/guide/retrieval.md)\n· [episodes + tags](docs/guide/episodes.md#episodes--tags)\n· [canonical facts, contenders, world facts, lessons](docs/guide/memory-model.md)\n· [the consolidation workflow](docs/guide/dreaming.md#consolidation-workflow-agent-driven-dedup).\n\n## Dreaming — consolidating memories into facts\n\nA **dream** distils the recent associative stream into canonical cortex\nfacts while you're not looking: pull unconsolidated memories → extract\n`(entity, attribute, value)` → advance a cursor so nothing is reprocessed.\nExtraction is pluggable:\n\n| Tier | How it runs | Needs | Quality |\n|------|-------------|-------|---------|\n| **0 — none** | no extractor configured — the dream still runs, prunes, and advances its cursor, but writes no canonical facts | nothing | none (`memory_fact_set` is your only cortex writer) |\n| **1 — agent-driven** | the **agent itself** is the gateway: the `/dream` judgment session (its manual-extraction branch fires only when no endpoint is configured) | the agent you already run | highest |\n| **2 — shipped default** | daemon auto-sweep → the bundled CPU sidecar, or any OpenAI-compatible endpoint | nothing (sidecar) | high; free if local |\n\nThe stack ships tier 2 preconfigured (the bespoke Gemma 4 E4B extractor\nfine-tune in a llama.cpp sidecar, internal-only). The sweep cadence,\npointing dreams at a bigger local model or at Claude Sonnet with automatic\nsidecar fallback, the full-corpus **deep dream** graph pass, and the\nprivacy/cost trade-offs: [Dreaming](docs/guide/dreaming.md).\n\n## Benchmarks\n\nThe headline is the **whole benchmark, not a slice**: all six\n[LongMemEval](https://arxiv.org/abs/2410.10813) question types, 500\nquestions, oracle variant, run end to end through the memory (qwen-27b\nextraction under the v25 embedding backbone, BM25-on turn retrieval).\nSingle pass, graded by the local Qwen3.6-27B bench judge (2026-08-03):\n\n| arm | accuracy | context tokens/question |\n|-----|----------|------------------------|\n| naive RAG (top-6 turns) | 0.688 | ~1210 |\n| cortex facts only | 0.416 | **~158** |\n| hybrid (facts + top-3 turns) | 0.664 | ~842 |\n| **commit-gated cascade** | **0.690** | ~883 |\n\nThe **cascade** is a serving policy, not a fourth pipeline: answer from\nthe consolidated facts when that channel *commits*, fall back to raw-turn\nRAG when it abstains. Overall this is **a wash on accuracy at ~73% of the\ncontext** — 0.690 vs 0.688 is one question in 500 on a single pass, and\nnobody should read it as a win. The fact spine alone answers at ~13% of\nRAG's token budget, at a large accuracy cost outside the types it is built\nfor. The structure is per type:\n\n| question type | n | naive RAG | commit-gated cascade |\n|---|---:|---:|---:|\n| knowledge-update (facts change) | 78 | 0.859 | ~~0.936~~ (retired — [why](docs/guide/benchmarks.md#the-knowledge-update-slice-78-of-the-500)) |\n| single-session-user | 70 | 0.929 | 0.943 |\n| single-session-assistant | 56 | 0.911 | 0.929 |\n| single-session-preference | 30 | 0.800 | 0.700 |\n| temporal-reasoning | 133 | 0.526 | 0.526 |\n| multi-session | 133 | 0.504 | 0.474 |\n\nThe consolidated spine helps where a fact changes and where the answer\nsits inside one session; it loses where the answer must be aggregated\nacross sessions or ordered in time, because per-fact consolidation is\nexactly what discards that structure. BEAM-100K reproduces the same shape\nindependently. Its abstention questions are where the spine looks best —\nthe fact-spine arm scores 0.950 against naive RAG's 0.775, identical under\nthe local judge and under an independent Opus-class judge — but the\n2026-09-02 five-arm run bounds that reading: a no-memory arm scores 1.000\nthere, so the edge is calibration (a small fact context refuses where raw\nturns confabulate), not evidence that the memory recalled anything. Setup, caveats,\nboth bench stacks side by side, and the evidence that extraction quality is\nthe dominant factor: [Benchmarks](docs/guide/benchmarks.md); full\nmethodology: [`evals/README.md`](evals/README.md).\n\nRetrieval itself was re-measured on the same corpus before the v25 backbone\nswap (150 questions, 74,183 haystack turns, 299 gold turns; pure recall — no\nreader, no judge): `Qwen/Qwen3-Embedding-0.6B` reaches **R@10 0.809** against\n`bge-base-en-v1.5`'s 0.742 and the previously-shipped `all-MiniLM-L6-v2`'s\n0.572, and beats bge-base head-to-head **+32/−12 at k=10 (p=0.004)**.\nArtifacts: [`embedder-recall-shootout-20260727.json`](evals/results/embedder-recall-shootout-20260727.json),\n[`embedder-recall-qwen-vs-bge-20260728.json`](evals/results/embedder-recall-qwen-vs-bge-20260728.json).\n\n## Cortex Console (web UI)\n\nAn operator dashboard served by the daemon itself — point a browser at\n**`http://127.0.0.1:8765/ui/`** (the `/health` and `/mcp` endpoints are\nunchanged; the console is additive). It's a read-mostly instrument panel for\nseeing and steering the memory a human otherwise can't observe:\n**Observatory** (health, per-layer counts, the memory store's capacity meter, dream\ngauges), **Cortex** (canonical facts with provenance, version-history\ntimelines, inline Accept/Discard for contested slots), **World / Lessons /\nEpisodes**, **Stream** (live search with rerank/BM25 toggles and a\nranking-trace debugger), **Graph** (interactive force-directed visualiser, with a review drawer that\ncan Accept/Reject merges or — for a source file and its own bare concept,\n`band.py` ↔ `band` — record an `implements` edge instead of forcing\nmerge-or-dismiss; proposals a background dream has already judged carry a\nverdict chip — accept/reject/leave with confidence, the model's reason in\nthe tooltip — as a lead, never a decision), and **Console** (every safe `config.yaml` scalar with live-vs-restart\nbadges, diff-preview, and atomic save).\n\n**Auth** mirrors `/mcp`: `/ui` (static shell) and `/health` are open; `/api/*`\nrequires the same `PSEUDOLIFE_MCP_TOKEN` bearer when one is set (the console\nprompts for it and stores it locally). No build step, no CDN, fully offline —\nvanilla ES modules + vendored OFL fonts served straight from the daemon.\nDeveloping the UI? A fixture-backed dev server (no Postgres, no torch)\nrenders the real frontend against canned data:\n`python -m pseudolife_memory.web.devserver` → `http://127.0.0.1:8770/ui/`.\nIts payloads self-announce (`\"fixtures\": true` on `/health`), and the\ntopbar shows a \"DEMO DATA — fixture server, not a real bank\" chip in\nplace of the live chip, so a fixture run is never mistaken for a real\nbank.\n\n## Capabilities at a glance\n\n| Capability | Status |\n|---|---|\n| Transport | Streamable-HTTP MCP daemon (`/mcp`); stdio shim is the installer default (per-session identity) — HTTP remains for single-session setups |\n| Storage | Postgres 18 + pgvector (source of truth); ChromaDB for the reference bank |\n| Associative store | Flat similarity store (default since the 2026-08-15 measured verdict; the 8-tier banded preset remains opt-in); hybrid dense + BM25 ranking (BM25 on by default); contradiction detection and supersession, including a deterministic slot-identity path that fires regardless of embedding similarity |\n| Canonical-fact cortex | Single-writer: LLM dream pass + `memory_fact_*` (regex auto-promote opt-in, default off) |\n| Set-valued slots | `memory_set_add` / `memory_set_remove` for many-current-value slots; one-way scalar→set conversion, aggregate scalars guarded (park as contender); an `assistant`-origin add cannot convert or join another tier's set, and cannot retract another tier's member |\n| Provenance contenders | Tier-rank guard `user > action > agent > assistant`; `memory_fact_resolve` |\n| Fact currency | Every cortex fact is dated (`asserted_at` / `age`); `freshness_class` (`evergreen` / `slow` / `volatile`) decays `effective_confidence` and flags `stale`. Left `auto`, the class is inferred from the entity's kind (schema v24 `entity_kinds`) — only `system` entities can rot; artifacts and concepts stay evergreen |\n| Write-time labels | `authority` (`directive` / `observation` / `quoted` — the speech act, orthogonal to the `origin` tier) and `distortion_tolerance` (`constraint` / `procedural` / `belief` / `preference` / `episodic`) on entries and facts, set at write time (explicit, or a deterministic heuristic under `auto`) and inherited through supersession unless restated. A `constraint` source is carried verbatim through the dream (with a post-dream guard) and pinned ahead of cosine in `memory_search`'s cortex block and `memory_recall` when the query names its entity; a `quoted` source is low-trust for the two-man rule (schema v35) |\n| Knowledge graph | Typed entities/edges, closed relation vocab, on-read closure (Postgres + NetworkX, no AGE/Cypher) |\n| World cortex | `memory_world_*` — cited external facts + age-decayed freshness (manual ingest) |\n| Procedural memory | `memory_outcome` (signals) → dream-synthesised lessons via `memory_lesson_search`; `prefers`/`avoids` graph edges; single-writer |\n| Sense of time + multi-writer | Per-write stamp (tx/valid time, HLC ordering, writer/session); `memory_history`; relative `age` on reads; `write_mode` seam (snapshot live, occ Phase-2) |\n| Episodes + tags | Session episodes daemon-owned, keyed by a resolved five-tier session identity; hook/shim eager-open or lazy-open + idle reaper + prune-empty + resume-after-reap; nested sub-episodes with subtree-expanded recall; multi-valued `tags=[...]` |\n| Session briefing | SessionStart hook injects unsure-graph + lessons + verified world facts + last-session recap (`pseudolife-mcp briefing`) |\n| Consolidation | `memory_consolidation_candidates` + `memory_consolidate` |\n| Optional components | Cross-encoder reranker (`rerank=True`, ~80 MB); ONNX embedding backend (`pip install .[onnx]` — ~3x faster CPU encode, bit-identical, auto-enabled when installed; the default Qwen3-Embedding-0.6B has no ONNX export and falls back to torch, so this currently only speeds up MiniLM-family models); NLI contradiction scorer (`pip install .[nli]`, ~278 MB) |\n| Web console | Cortex Console at `/ui/` — health/stats, fact review + history, graph visualiser, search/trace, config editor (read-mostly, token-gated like `/mcp`) |\n| Schema version | v37 (Postgres meta version) — additive `ADD COLUMN IF NOT EXISTS` migrations on daemon start, **except v25**: the `vector(384)`→`vector(1024)` move is not additive, so the daemon refuses to start against an older-dimensioned bank until you run [`ops/migrate_embeddings.py`](docs/runbooks/embedding-v25-migration.md); legacy file-mode `.pt` banks auto-migrate into Postgres; [full version history](docs/guide/configuration.md#schema-version-history) |\n\n## Troubleshooting\n\nStart with `curl http://127.0.0.1:8765/health` — it reports the schema\nversion, storage backend, auth state, and `persist_errors` (non-zero means\nwrites are failing to reach Postgres; check `docker logs\npseudolife-mcp-daemon`).\n\n- **The cortex stays empty** (canonical facts never appear on their own).\n `/health` reporting `\"extractor\": \"none\"` means no extractor is\n configured, so the dream writes no facts and `memory_fact_set` is the\n only cortex writer — expected on the lite tier. Point the daemon at an\n OpenAI-compatible endpoint\n ([Quickstart](#what-lite-gives-you-and-the-one-thing-it-doesnt)) or use\n the Docker tier's bundled sidecar. `\"extractor\": \"disabled\"` instead\n means dreaming itself is switched off in config.\n- **Lite daemon refuses to start on Windows** with a message about the data\n path: the embedded Postgres runtime needs an **ASCII-only** data\n directory. Set `PSEUDOLIFE_MCP_DATA_DIR` to one (e.g.\n `C:\\pseudolife-data`) —\n [Configuration](docs/guide/configuration.md#connection--deployment-env-vars).\n- **First build is slow / big.** The daemon image (~5.0 GB, several\n minutes to build) bakes in CPU torch and the embedding weights (Qwen3-Embedding-0.6B\n plus MiniLM); the extractor sidecar\n adds a ~5.3 GB model download on its first build. Every start after that is\n offline and fast — if a *rebuild* is re-downloading models, the Docker\n layer cache was pruned.\n- **Daemon unreachable after `wsl --shutdown`** (Windows): the host port\n forward is gone — `docker restart pseudolife-mcp-daemon` re-establishes it.\n- **Docker eating RAM** (Windows): the WSL2 VM (`Vmmem`) claims up to ~50% of\n host memory by default. Copy `ops/wslconfig.example` to\n `%USERPROFILE%\\.wslconfig`, tune `memory=`, then `wsl --shutdown`.\n- **Port already in use**: the stack binds `127.0.0.1:8765` (daemon) and\n `127.0.0.1:5433` (Postgres). Change the host side in\n `ops/docker-compose.yml` if either collides.\n- **Console shows \"offline\" / Unauthorized**: \"offline\" means the daemon\n isn't reachable (see above); a 401 prompt means it runs with\n `PSEUDOLIFE_MCP_TOKEN` — paste that token into the Console's Token dialog.\n- **The coding agent doesn't see the tools**: `claude mcp list` or\n `codex mcp list` should show\n `pseudolife-memory` ✓ connected. If not, re-check the URL\n (`http://127.0.0.1:8765/mcp` — the `/mcp` path matters) and the bearer\n header when a token is set. The daemon preloads the embedder on a warmup\n thread at start (~5–10 s); a very early first call can race it and take a\n few seconds.\n- **Tools vanish after an upgrade / the client log says \"Connection\n closed\"**: the shim's registered command can live outside the repo venv,\n and the MCP SDK v2 migration set an `mcp>=2.1` floor — an older SDK in\n that environment crashes the shim on start. The shim detects this and\n prints the interpreter path and the exact fix on stderr: `pip install -U\n \"mcp>=2.1,<3\"` in that interpreter, or re-run the installer (which\n registers the project venv's shim).\n- **A harness \"removed tools\" notice is not an outage.** A resumed session\n can carry a larger tool roster in its transcript than the current\n [toolset tier](docs/guide/configuration.md#toolset-tiers) serves —\n that's a visibility filter, not a disconnect. Make one `memory_search`\n call before concluding the MCP is down.\n\n## Uninstall\n\n**Lite tier:** remove the MCP registration (`claude mcp remove\npseudolife-memory` / `codex mcp remove pseudolife-memory`), then\n`pip uninstall pseudolife-mcp`. If you also want the bank gone, delete\nthe per-user data directory (`%LOCALAPPDATA%\\pseudolife-mcp` on Windows,\n`~/.local/share/pseudolife-mcp` on Linux, `~/Library/Application\nSupport/pseudolife-mcp` on macOS — or wherever `PSEUDOLIFE_MCP_DATA_DIR`\npoints). Back it up first: `pseudolife-mcp backup` works on lite too.\n\n**Docker tier** — deletion is deliberate at every step:\n\n```bash\n# 1. Optional: take a final backup first (ops/backup.ps1 or ops/backup.sh).\n# 2. Stop and remove the containers (volumes survive this).\ndocker compose -f ops/docker-compose.yml down\n# 3. Remove the MCP registration.\nclaude mcp remove pseudolife-memory\ncodex mcp remove pseudolife-memory\ngemini mcp remove pseudolife-memory -s user\n# 4. Only when you're sure: delete the data volumes (THIS is the memory).\ndocker volume rm pseudolife-mcp-bank pseudolife-mcp-state\n```\n\nHost-process installs: also unregister the logon task\n(`Unregister-ScheduledTask -TaskName \"Pseudolife-MCP Daemon\"`) and remove\nthe SessionStart briefing hook — plus, Claude client, the UserPromptSubmit\ndiscipline hook — from `~/.claude/settings.json` and/or\n`~/.codex/hooks.json` (a timestamped `.bak-*` sits next to each edited file).\n\n## Testing\n\n`pip install -e .[dev]`, then `pytest tests/`. The suite covers every\nlayer, from the MemoryService surface to the Cortex Console REST API;\nmodel-heavy pieces are stubbed so it stays fast and offline. The PG-backed\nsuites each target a throwaway per-run `pseudolife_memory_test_`\ndatabase on the bundled dev container (never your real bank; concurrent\nruns can't collide), dropped on exit, and skip cleanly without Postgres.\nFull dev setup: [CONTRIBUTING](CONTRIBUTING.md).\n\n## What's not built yet\n\n- **Reflection via MCP sampling** — would let the dream borrow *Clau",
"bytes": 60000,
"sha": "bc5ca49224d87311993f45be1cfc0cd2ac42c3b4c9c45139710415fec7f52fd9",
"repo_slug": "pseudogiant-xr/pseudolife-mcp",
"fonte": "repo",
"truncated": false,
"api": "https://agentalog.com/api/listings/mcp_io_github_pseudogiant_xr_pseudolife_mcp_6dd87716/readme"
}